Future of Privacy Forum Releases Comprehensive Report On Algorithmic Personalization in Youth Online Experiences
As policymakers continue to debate youth online safety regulations, a new FPF report assesses the role of data-driven personalization and its implications for emerging policy and product design
WASHINGTON, D.C. — (June 10, 2026) — The Future of Privacy Forum — a global non-profit focused on data protection, AI, and emerging technologies —today released Personalization and Youth Online: Assessing Benefits, Risks, and Safeguards, a comprehensive report examining the role of algorithmic personalization in young people’s digital lives and its implications for emerging policy and product design.
Personalization—the use of personal data to tailor content and services to individual users—sits at the center of today’s most contested debates about youth and digital technology. It appears in nearly every digital service young people use—influencing the content they see, how information is ranked, which recommendations are surfaced, and what prompts or ads are presented. While it offers a host of functional and protective benefits, the practice has also become a recurring regulatory focus of efforts to protect minors from online harms, including by targeting the specific product features and design elements through which personalization operates.
“Personalization is an incredibly nuanced topic; the same mechanisms that may be associated with risks may also enable benefits such as adaptive learning, community discovery, and age-appropriate protections that make the online experience safer for young people,” said Daniel Hales, Policy Counsel for the Future of Privacy Forum and co-author of the report. “Understanding the tradeoffs that come with any risk mitigation strategy is critical, so you don’t inadvertently limit the benefits of personalization along with the harms.”
In an effort to help policymakers and companies effectively evaluate these tradeoffs, the report examines the intersection of personalization and youth online experiences in five parts: key definitions and common use cases; key benefits of personalization in youth online experiences; common risks of harm; an assessment of more than a dozen emerging mitigation proposals and the associated tradeoffs; and an analysis of the emerging policy and regulatory landscape.
Examples of the mitigation strategies examined in the report include:
Alternative approaches to curating content, such as feeds that display content chronologically, by popularity, or by categories and preferences a user has explicitly selected. While these approaches may reduce data-intensive curation, the report notes that they may have unintended effects, including the potential to inadvertently amplify spam and misinformation, and limit platforms’ ability to suppress age-inappropriate content.
Data minimization rules applied without reference to the purpose of how the data is being used may curtail beneficial personalization alongside higher-risk applications. Purpose-based limitations, which restrict data use according to processing context rather than data category alone, may better preserve the protective uses of personalization while constraining its riskier applications.
Risk mitigations related to conversational AI chatbots, including those designed to facilitate transparency, consent, responsible data practices, and safety-by-design. Each of these comes with its own tradeoffs; for example, on-device processing of sensitive data protects privacy, but can reduce model quality, which may ultimately push users toward less protective alternatives. Effective safeguards for AI personalization will require careful attention to which constraints reduce overall risk and which simply shift it.
Safety and well-being measures, including parental control and oversight, increasing digital literacy, measures to improve digital well-being, and control over personal data use. Many of these tactics will be most effective when paired with other measures; for example, increased digital literacy and making default wellbeing features like time-use limits and sleep and nighttime protections do not address the underlying design features that generate risk.
“Effective regulation must account for some precise questions: how personalization is implemented, what data it uses, and what purpose it serves,” said Holly Hawkins, Director for Youth Policy for the Future of Privacy Forum and the other co-author of the report. “While no single mitigation strategy is going to effectively address the full range of risks, we know that the most effective approaches share a common characteristic: they take a risk-proportionate approach to limiting higher-impact potential harms while preserving the functional and protective benefits of personalization for young people. We hope that this report can serve as a valuable resource to policymakers and companies who are attempting to find this delicate balance.”
The report’s release follows a growing interest from policymakers at both the federal and state levels in regulating personalization practices as part of efforts to strengthen protections for youth online. Both New York and California have passed laws prohibiting online services from providing algorithmically curated feeds to minors without parental consent; South Carolina and Nebraska’s age-appropriate design code laws require services to offer an opt-out of personalized recommender systems.
The full report, including an appendix tracking a sample of enacted and proposed youth online safety laws worldwide that address personalization, is available here.
To learn more about the Future of Privacy Forum, visit fpf.org.
###
Frontier AI Goes Federal: How the Great American AI Act Compares to State Laws
Introduction
It has been an unusually active few weeks for AI safety policy. Following a new frontier model safety bill passed in Illinois, and a White House executive order on AI security, Rep. Jay Obernolte (R-CA) and Rep. Lori Trahan (D-MA) released a bipartisan discussion draft for the Great American AI Act of 2026, adding another major federal proposal to the rapidly developing frontier AI landscape.
The draft is broad, covering issues ranging from workforce development and AI literacy to cybersecurity and international standards. But for many AI developers and deployers, the most important provisions are those focused on frontier model regulation. The draft would create requirements related to frontier AI transparency, critical safety incident reporting, employee whistleblower protections, and independent verification organizations. It would also include a three-year preemption clause restricting state laws that specifically regulate AI model development.
This blog highlights four key takeaways of the discussion draft:
The draft is one of the first bipartisan attempts in Congress to address both frontier model safety and preemption of AI. These aspects make it a notable legislative effort, even if its prospects are uncertain.
The draft incorporates many of the frontier model safety provisions in existing state laws but also has key distinctions. Compared to recent state frontier AI laws in California, New York, and Illinois (pending signature), the bill makes some important adjustments, like adding a revenue threshold for “frontier developers,” modifying the definition of “critical safety incident,” and utilizing a different penalty structure.
The draft brings the preemption debate back into the federal AI policy conversation.It includes a three-year preemption clause focused on state laws that specifically regulate AI model development.
The draft also reaches beyond frontier model safety. Other notable provisions include a study content moderation, a federal voluntary model testing program, and disclosure requirements for AI-related mass layoffs.
The Act Enters the AI Safety and Preemption Debate
Amidst a crowded but unsettled federal AI policy landscape, the Great American AI Act is notable for its regulatory focus, bipartisan backing, and what it may signal for federal AI governance ahead. Though Congress has introduced no shortage of AI bills, there has been limited movement toward enacted legislation. Congress has considered sector-specific bills on chatbots1, regulatory sandboxes, defense, elections, and financial scams, as well as broader proposals aimed at establishing a national AI framework like Sen. Blackburn’s (R-TN) TRUMP AMERICA AI Act.
Amid this activity, the Great American AI Act steps into two of the most active and contested AI policy debates: frontier model safety and federal preemption. On AI safety, the draft follows a period of growing attention to frontier model oversight at both the state and federal levels, where policymakers are trying to balance concerns about catastrophic risks and national security with concerns that overly burdensome requirements could slow AI innovation or weaken U.S. competitiveness.
On preemption, the draft arrives less than a year after Congress rejected a much broader effort to pause state AI regulation. In July 2025, the Senate voted 99-1 to remove a proposed 10-year moratorium on state AI laws from the budget reconciliation package. By contrast, the Great American AI Act includes a narrower three-year preemption provision focused on state laws that specifically regulate AI model development.
The draft is also significant because of both who introduced it and how they introduced it. Other federal AI bills have addressed AI safety or included preemption language, but this proposal comes from bipartisan sponsors who have been closely involved in federal AI policy2. In introducing the draft, the sponsors emphasized that “policy for a technology this transformative can only be built to last if it’s written by both parties.” Just as importantly, they have framed the draft as a starting point rather than a final product, describing it as “the start of a serious national conversation.” Whether the bill advances in its current form remains uncertain, especially given the sensitivity of federal preemption and the range of issues addressed. Even if the draft changes, it may help shape the terms of future federal debates over AI safety. At a minimum, it is another sign that Congress is increasingly focused on how to govern AI systems and how federal rules should interact with the fast-moving state AI landscape.
Frontier AI Requirements: Where the Draft Aligns with State Laws
The draft’s frontier model provisions are not starting from scratch. They closely track the framework emerging from California’s SB 53, New York’s RAISE Act, and Illinois’ SB 315 (awaiting signature), including requirements for frontier AI frameworks, transparency reports, safety incident reporting, enforcement, and whistleblower protections. But the federal draft makes some important adjustments, including a revenue threshold for “frontier developers,” a definition of “critical safety incident” that is broader in some respects and narrower in others, and a federal enforcement structure with penalties of up to $1 million per day.
Key Definitions
The Draft largely aligns with recent state frontier AI laws’ definitions of “large frontier developer,” “frontier model” (encompassing foundation models trained using more than 10^26 computational operations), and “catastrophic risk” (covering certain risks of death, serious injury, or major property damage arising from frontier models). For more background on SB 53 and the RAISE Act, see FPF’s prior analysis. There are, however, a few notable differences.
First, unlike the state laws, the Draft requires “frontier developers” to have a gross revenue exceeding $50 million. The state laws only include a gross revenue qualifier in the definition of “large frontier developer.”
Second, the draft’s definition of “catastrophic risk” does not specify that the death, serious injury, or property damage must arise from a “single incident,” as in the state laws.
Finally, the draft’s definition of “critical safety incident” differs from the state laws by not mandating actual harm occur (such as death, bodily injury, or property loss), nor does it include scenarios where the model uses deceptive techniques to evade developer controls or monitoring.
Core Frontier Model Obligations
The draft would impose several obligations on frontier developers and large frontier developers that also largely mirror the recent state frontier AI laws. The main requirements include:
Frontier AI Framework: Large frontier developers would need to write and publicly post a frontier AI framework addressing catastrophic-risk thresholds and mitigations, model weight cybersecurity, internal governance, and decisions about internal use and deployment. Developers would need to review the framework at least annually and publish any material modification within 30 days. These requirements closely track the state laws.
Transparency Reports: Before, or concurrently with, deploying a new frontier model or a model with a substantial modification, frontier developers would need to publish a transparency report covering information such as release date, supported languages, output modalities, intended uses, restrictions, risk assessments, third-party involvement, and mitigation steps. These requirements largely align with recent state frontier AI laws.
Reporting Mechanisms: The draft would require confidential reporting mechanisms for critical safety incidents and for catastrophic risks arising from a large frontier developer’s own use of its frontier models, including internal use and internally deployed models. This is similar to the state laws in allowing both frontier developers and members of the public to report critical safety incidents, but the draft adds a separate mechanism for reporting catastrophic risks from developers’ own model use.
Critical Safety Incident Disclosures: Frontier developers would need to report critical safety incidents to the Center for AI Standards and Innovation (CASI) within 15 days of discovery, or within 24 hours if the incident poses an imminent risk of death or serious injury. This mirrors California’s SB 53, while New York and Illinois require a shorter 72-hour reporting window.
Enforcement: Violations can result in fines of up to $1 million per violation, with each day treated as a separate violation. Federal and state attorneys general may also seek injunctions. This penalty structure may be less stringent than the state laws: SB 53 allows penalties of up to $1 million per violation, while the RAISE Act and SB 315 allow penalties of up to $3 million for subsequent violations. However, unlike the draft, those laws do not clearly cap penalties for a continuing violation at $1 million per day, meaning multiple violations could potentially be enforced in a single day.
Definitional Updates and Rulemaking: Beginning by January 1, 2028, the CAISI Director would need to issue annual recommendations on whether key definitions should be updated. The Secretary of Commerce would also have authority to adopt rules implementing the provisions, including criteria for determining when model modifications are “substantial” or “material.” California’s SB 53 includes a similar definitional update requirement, while New York’s RAISE Act similarly provides rulemaking authority.
Employee Whistleblower Protections: In a separate section, the draft would prohibit AI companies from retaliating against employees for lawfully reporting violations of federal AI laws and would provide remedies for employees who experience retaliation. This provision is similar to whistleblower protections in California’s SB 53 and Illinois’ SB 315, though those laws go further by requiring frontier developers to provide covered employees with clear notice of their rights and access to a reasonable internal process for anonymously disclosing information.
Taken together, the draft would bring much of the emerging state frontier AI framework into federal law. The broad architecture is familiar, but the federal draft contains key distinctions. It also does not carry over every state-law mechanism, most notably the frontier developer disclosure programs in the RAISE Act and SB 315, which require large frontier developers to maintain current filings with state agencies on ownership and business information.
Independent Verification Organizations and Audits
The draft would also put independent auditors at the center of its frontier AI framework. Within one year of enactment, and every six months thereafter, large frontier developers would need to retain a licensed independent verification organization (IVO) to verify compliance with the draft and assess whether the developer’s risk mitigation efforts are adequate to address catastrophic risks.
The provision reflects a broader trend toward independent evaluation of frontier models. Illinois SB 315 would also require large frontier developers to undergo independent third-party audits, but it does not create a licensing and oversight system for IVOs like the one proposed in the draft. However, other states, like Virginia, have begun exploring this model. Virginia enacted SB 384 this year, which directs the Joint Commission on Technology and Science to study the future development of an IVO framework (after earlier versions of the bill would have created an IVO licensing structure akin to this draft).
These provisions would require:
Access: Large frontier developers would have to provide IVOs with timely access to unredacted materials and other information reasonably necessary to conduct audits and assessments. Developers could impose reasonable security protocols and access limitations to protect trade secrets and confidential business information.
Audit and Assessment Content: IVO reports would have to describe the scope, time period covered, materials reviewed, methods used, and any limits on the assessment. They would also assess the developer’s compliance efforts; the adequacy of its frontier AI framework, and risk-monitoring; any “failure, deficiency, or material weakness;” and internal controls.
Ad Hoc Audits and Assessments: The Director of CASI could require additional audits when necessary to verify compliance, validate prior findings, or monitor significant changes in risk, including after a critical safety incident or substantial modification.
Supplemental Reports: IVOs could also need to submit supplemental reports when new information, unexpected model capabilities, or major model changes call into question an earlier finding that the developer was adequately managing catastrophic risks.
Additionally, the Bill would create a federal licensing and oversight system for the auditors themselves, making IVOs a potential new layer of AI governance.
Together, these proposals suggest that policymakers are increasingly looking to independent verification as a middle ground between company self-assessment and direct government review. The Great American AI Act would take that idea further by specifying who can serve as an independent verifier, what they must review, and how their findings may be shared with enforcement authorities.
Federal Preemption and the State AI Landscape
One of the draft’s most consequential provisions is its three-year preemption clause. The draft would prohibit states from establishing, continuing in effect, or enforcing any law or regulation that specifically regulates the development of an AI model (emphasis added). It would not preempt laws of general applicability, state authority granted under the draft, or laws governing post-deployment activities, including the implementation, distribution, offering, or use of AI systems, products, or services.
This approach differs significantly from the AI moratorium Congress considered last year as part of the One Big Beautiful Bill Act. That proposal would have broadly restricted states from enforcing laws or regulations that “limit,” “restrict,” or “regulate” AI models, AI systems, or automated decision systems, while allowing laws viewed as “facilitating” AI. It also evolved from a proposed ten-year pause to a five-year compromise before ultimately being removed from the package. By contrast, the Great American AI Act uses narrower language: it applies only to laws that specifically regulate AI model development and sunsets after three years.
However, as always, preemption would be complicated. Many state AI laws do not neatly separate development from deployment. They may impose obligations on developers and deployers, or require pre-deployment documentation or risk assessments for systems that are ultimately used in employment or other high-impact contexts.
As drafted, the draft’s preemptive effect would likely be greatest for state laws focused on frontier model development, such as California’s SB 53, New York’s RAISE Act, and Illinois SB 315. But the clause could also create uncertainty for other AI laws. For example, a chatbot law focused on how companies offer chatbots to the public would likely be easier to preserve under the post-deployment carveout. But if a law requires changes to how a model is trained, fine-tuned, tested, or designed before release, the line between deployment and development may be harder to draw.
The result is a preemption provision that is far narrower than last year’s proposed 10-year moratorium, but still raises significant interpretive questions. The answer to those questions is likely to have an impact on both developers and deployers, and would likely depend on how regulators and courts characterize specific laws and their requirements.
Other Key Provisions
Although the frontier model provisions are the most significant for most AI developers, the draft reaches well beyond AI safety: It also includes several provisions focused on the broader AI ecosystem, including workforce development and displacement. This section highlights three additional provisions worth watching: a study on government engagement with AI platforms, new federal AI testbeds and voluntary model testing, and disclosure requirements for AI-related mass layoffs.
Study on Protecting Free Speech: The draft would direct the Secretary of Commerce to study how the government encourages or pressures AI companies on content moderation, information prioritization, and output generation. The report must examine legal frameworks governing federal agency interactions with AI platforms and recommend legislation providing individuals with redress against unlawful government censorship, including transparency and oversight mechanisms. While this section is only a study requirement, it signals congressional interest in how the government communicates with AI companies about content moderation and model outputs. For AI companies, this study may lead to future regulation on transparency and government oversight.
AI Testbeds:The draft would direct the establishment of an AI testbed program for testing, evaluating, and assessing AI systems, including automated evaluations, security vulnerability assessments, and computational resource assessments. It would also establish a voluntary foundation model testing program for vendors of foundation models, AI virtual agents, and robots that incorporate foundation models. This provision parallels recent federal activity around voluntary AI testing and evaluation, including the White House’s June 2026 executive order establishing a voluntary framework for certain frontier AI developers to share models with the federal government before public release for national security and cybersecurity assessment.
Disclosures for AI Layoffs: The draft would require employers to provide 60 days’ advance notice when AI is a “substantial factor” in a mass layoff, including information on the AI involved, the estimated share of job losses attributable to AI, and pre-layoff upskilling or retraining efforts. A similar requirement was recently enacted in Connecticut’s SB 5, which requires employers issuing mass layoff notices to tell the state’s Labor Department whether the layoffs are related to the employer’s use of AI. This provision reflects growing interest in how AI may affect workforce displacement and whether existing worker-notice frameworks should account for AI-related job losses.
Conclusion
The Great American AI Act is still a discussion draft; whether it will advance in its current form remains uncertain. Federal AI legislation has faced a difficult path in Congress and the draft touches on issues, especially frontier model safety and preemption, that are likely to generate significant debate.
But the draft is still an important marker in the federal AI conversation. It shows that Congress is continuing to consider how to regulate frontier model development, how to structure independent oversight, and how federal rules should interact with the growing number of state AI laws. Even if this bill changes substantially, these questions are unlikely to go away.
In the meantime, states are likely to continue to test different approaches to AI regulation, including laws that regulate frontier model development, deployment, or both. That could make the draft’s preemption language especially important to watch. The next phase of AI policymaking could be defined not only by the rules new proposals would set, but also by the coalitions advancing them and the venues where they move forward: Congress, the Executive Branch, the states, or all three.
Five major federal chatbot proposals have been introduced: the CHAT Act (S.2714/H.R. 7218), GUARD Act (S.3062/HB 8623), SAFE BOTs Act (H.R. 6489), Youth AI Privacy Act (S. 4199), and the CHATBOT Act (S 4407). ↩︎
Rep. Obernolte (R-CA) previously co-chaired the bipartisan House Task Force on Artificial Intelligence, which released its final report in December 2024. Rep. Trahan (D-MA), a member of the House Energy and Commerce Committee’s Innovation, Data, and Commerce Subcommittee, has also been active on technology accountability issues. ↩︎
Privacy Becomes You, Bayou State: A Look at the Louisiana Data Privacy Act
Louisiana has become the 22nd U.S. state to enact a comprehensive consumer privacy law—and the third this year following Oklahoma and Alabama—after Governor Landry signed the Louisiana Data Privacy Act (LDPA) (SB 386) on May 29. Overall, this is a fairly standard state privacy law that follows the Washington Privacy Act framework apart from the law’s CCPA-style applicability thresholds. The law will go into effect on January 1, 2027. This blog post covers the LDPA’s scope, consumer rights, business obligations, and enforcement.
Scope
Applicability: Like other comprehensive privacy laws based on the Washington Privacy Act (WPA) framework, this law regulates controllers’ and processors’ collection and use of personal data.
Departing from the common WPA framework, this law’s applicability thresholds are modeled on those under the California Consumer Privacy Act (CCPA). The LDPA only applies to a person or entity doing business in Louisiana that either—
Has annual gross revenues exceeding $25 million;
Annually buys, “receives for the business’s commercial purposes,” sells, or shares for commercial purposes the “personal information” of at least 75,000 consumers, households, or devices; or
Derives 50% or more of its annual revenues from selling consumers’ “personal information.”
Not only do these thresholds reflect those under the CCPA, they also use the undefined term “personal information” (which is used in the CCPA) rather than the defined term “personal data” used throughout the LDPA. One unique aspect of these applicability thresholds is that prong (2) adds the criteria “receives for the business’s commercial purposes,” which is not present in the CCPA’s text although that law defines “commercial purpose” and uses the term in other contexts. (§ 1780.2(A).)
The LDPA includes broad entity- and data-level exemptions, including for—
State agencies or political subdivisions;
Financial institutions, affiliates, or data subject to the GLBA;
Covered entities, business associates, and protected health information governed by HIPAA;
Health records;
Information included in a limited data set maintained as required under 45 C.F.R. 164.514(e);
Nonprofits, including political organizations;
Institutions of higher education;
Information collected, used, or disclosed by a consumer reporting agency or furnisher to the extent regulated by and authorized under FCRA;
Personal data collected, processed, sold, or disclosed in compliance with the DPPA;
Personal data regulated under FERPA; and more. (§ 1780.2(B)-(C).)
Key Definitions: Personal data is defined consistently with other state laws as information that is linked or reasonably linkable to an identified or identifiable individual, and it does not include deidentified data or publicly available information. Sensitive data includes: personal data revealing racial or ethnic origin, religious beliefs, mental or physical health diagnosis, sexuality, or citizenship or immigration status; genetic or biometric data processed for uniquely identifying an individual; personal data collected from a known child (under 13); and precise geolocation data (within a radius of 1,750’). This definition is narrower than in many of the newer state laws, which often include other categories such as consumer health data, neural data, or status as a victim of a crime. (§ 1780.1.)
This law includes many of the key definitions associated with the Connecticut-model of state laws. For example: the definition of “biometric data” includes data generated from a photograph or video or audio recording if generated to identify a specific individual; “dark patterns” are defined and prohibited for obtaining consent; and “sale” is defined broadly to include exchanges of personal data for “other valuable consideration” apart from monetary consideration. (§ 1780.1.)
Consumer Rights
Consumers will have the standard rights to: confirm whether their personal data is being processed; access their personal data; correct inaccuracies in their personal data; have their personal data deleted; obtain a copy of their personal data in a portable format (if available in a digital format); and opt-out of the processing of their personal data for the purposes of targeted advertising, the sale of personal data, and profiling in furtherance of a decision that produces a legal or similarly significant effect concerning the consumer. Like the laws in Tennessee and Alabama, these consumer rights (including the opt-out right) do not apply to pseudonymous data if the controller is able to demonstrate that information necessary to identify the consumer is kept separately and subject to effective technical and organizational controls that prevent the controller from accessing the information. (§ 1780.3(A), 1780.4(O),)
Controllers must respond to consumer rights requests within 45 days, which can be extended an additional 45 days if necessary so long as the consumer is informed of the extension and the reason. If a controller declines to act on a consumer request, then it must inform the consumer of the decision, the justification, and how to appeal the decision. A controller is not required to comply with a rights request that it cannot authenticate, and that the authentication requirement extends to the consumer opt-outs as well. Some states, like Connecticut, provide that a controller does not need to authenticate an opt-out request but may deny an opt-out request if it has a good faith, reasonable and documented belief that the request is fraudulent. (§ 1780.3(B).)
In another departure from the Connecticut-style suite of state laws, the LDPA does not appear to require a controller to provide consumers with a mechanism to revoke previously given consent.
What about Agents and OOPS? A consumer will be able to designate another person to serve as the consumer’s authorized agent to opt-out of the processing of consumer’s personal data for targeted advertising or the sale of personal data. Although the law does not reference opt-out preference signals (OOPS) or universal opt-out mechanisms (UOOM), it does provide that a consumer can “designate an authorized agent using a technology, including . . . a global setting on an electronic device,” that allows the consumer to indicate the consumer’s intent to opt out of the processing for targeted advertising, for sale of personal data, or both.” Additionally, a “technology” described in the subsection may not “unfairly disadvantage another controller,” make use of a default setting (instead requiring “an affirmative, freely given, and unambiguous choice” by the consumer), and be consumer-friendly and easy to use. These are the common requirements for an OOPS under the state comprehensive privacy laws.
The use of a technologically-designated authorized agent by a consumer could be limited due to several exceptions under the law. A controller is not required to comply with an opt-out request from an authorized agent if: the authorized agent does not communicate the request in a clear and unambiguous manner; the controller cannot verify (with reasonable effort) that the consumer is a resident of Louisiana; the controller does not possess the ability to process the request; or the controller “does not process similar or identical requests the controller receives from consumers for the purpose of complying with similar or identical laws or regulations of another state.”(§ 1780.3(E)(5)-(6).)
Business Obligations
Consistent with most of the state privacy laws, controllers and processors are subject to an enumerated list of duties under the law—including transparency, data minimization, data security, non-retaliation, oversight of processors, data protection assessments, and children-specific protections—as well as a list of broad exceptions.
Transparency: Controllers must provide consumers with a “reasonably accessible and clear privacy notice” including information such as categories of personal data processed, processing purposes, how consumers can exercise their data rights, categories of personal data sold to third parties, and categories of third parties to whom data is sold. If the controller sells personal data, processes personal data for targeted advertising, sells sensitive data, or sells biometric data, there are additional notices that must be provided in the privacy notice (e.g., “NOTICE: We may sell your sensitive data”). (§ 1780.4(B).)
Data Minimization: The LDPA includes common procedural data minimization and purpose limitation restrictions. A controller must—
“[L]imit the collection of personal data to what is adequate, relevant, and reasonably necessary in relation to the purposes for which that personal data is processed, as disclosed to the consumer”
Obtain the consumer’s consent to “process personal data for a purpose that is neither reasonably necessary to nor compatible with the disclosed purpose for which the personal data is processed, as disclosed to the consumer”; and
Obtain the consumer’s consent to process the consumer’s sensitive data. (§ 1780.4(A).)
Data Security: A controller must establish, implement, and maintain reasonable administrative, technical, and physical data security practices that are appropriate to the volume and nature of the data. (§ 1780.4(A)(1)(b).)
Anti-discrimination and Non-retaliation: Controllers cannot process personal data in violation of state and federal laws that prohibit unlawful discrimination against consumers. Controllers also may not deny goods or services, charge different prices or rates for goods or service, or provide a different level of quality of goods or services to the consumer as retaliation for a consumer exercising any of their rights under the LDPA, subject to exceptions (e.g., if the data is necessary to provide a service or processed in connection with a bona fide loyalty program). (§ 1780.4(A).)
Processors: Processors must adhere to the instructions of a controller and assist the controller in complying with the controller’s duties or requirements under the law. Whether a person is acting as a controller or processor is a fact-based determination depending on context, but a processor remains a processor if they are adhering to a controller’s instructions with respect to a specific processing activity. There must be a valid contract in place between the controller and processor that meets statutory criteria (e.g., clear instructions for processing, deleting or returning personal data after the service is concluded). (§ 1780.4(D).)
Children’s Privacy: Consistent with most other state comprehensive privacy laws, the LDPA includes protections for children’s personal data and provisions that address COPPA compliance. “Sensitive data” includes personal data collected from a known child, and a controller must process the sensitive data of a known child in accordance with COPPA. Parents are able to exercise consumer rights on behalf of a child whose personal data is processed. Controllers and processors that comply with the verifiable parental consent requirements of COPPA are deemed to be in compliance with any requirement to obtain parental consent under the LDPA. In contrast to many of the newer state comprehensive privacy laws, the LDPA does not include opt-in rights for teenagers with respect to targeted advertising or the sale of personal data. (§§ 1780.1, 1780.2(E), 1780.3(A) & 1780.4(A).)
Data Protection Assessments: Controllers must conduct and document a data protection assessment for processing activities that present a heightened risk of harm to consumers, including processing personal data for targeted advertising, selling personal data, processing personal data for profiling that presents a reasonably foreseeable risk of substantial injury to consumers, and processing sensitive data. A controller must make a data protection assessment available to the Louisiana attorney general if requested in a civil investigative demand (although that requirement includes a cross-reference to a non-existent subsection of the law). (§ 1780.4(E).)
Exceptions: This bill includes a number of common exceptions, providing that nothing in the law shall be construed to limit a controller’s or processor’s ability to: comply with state, federal, or local laws or regulations; comply with regulatory inquiries or investigations; provide a specifically requested product or service; engage in public or peer-reviewed research in the public interest adhering to relevant safeguards; cooperating with law enforcement agencies; internal use of data for conducting research, effectuating a product recall, identifying and repairing technical errors, performing internal operations reasonably aligned with consumers’ expectations; and more. (§ 1780.4(G)-(I).)
Miscellaneous: This law includes one unique provision related to the sale of sensitive data. Section 1780.4(P) provides that “[a] person or entity described by R.S. 51:1780.2(A)(3) may not engage in the sale of personal data that is sensitive without receiving prior consent from the consumer,” and violation of that requirement subjects a person to a penalty under the law. The cross-reference is to the applicability threshold for a person or entity that does business in the state and that derives fifty percent or more of its annual revenues from selling consumers’ “personal information.” This is an ambiguous requirement. An entity meeting that threshold would already be under the requirement to obtain consent prior to processing sensitive data, which includes selling data, so it is not clear that this is an added responsibility, unless it is meant to apply more broadly. But there is no other language in the requirement suggesting that it would apply notwithstanding the law’s broad entity-level exemptions.
Enforcement
The Louisiana Attorney General will enforce the LDPA and violations will constitute unfair and deceptive trade practices under Louisiana’s Unfair Trade Practices and Consumer Protection Law. Notably, the private rights of action under the unfair trade practices law do not extend to violations of the LDPA. For the first six months of enforcement (January 1, 2027 to July 31, 2027), the attorney general must give persons notice of alleged violations and at least 30 days to cure those violations prior to initiating an investigation.
The attorney general is required to post online information regarding controllers’ and processors’ responsibilities and consumer rights under the law, and money received from enforcement actions will go towards funding the attorney general’s consumer protection efforts or promoting consumer protection and education.
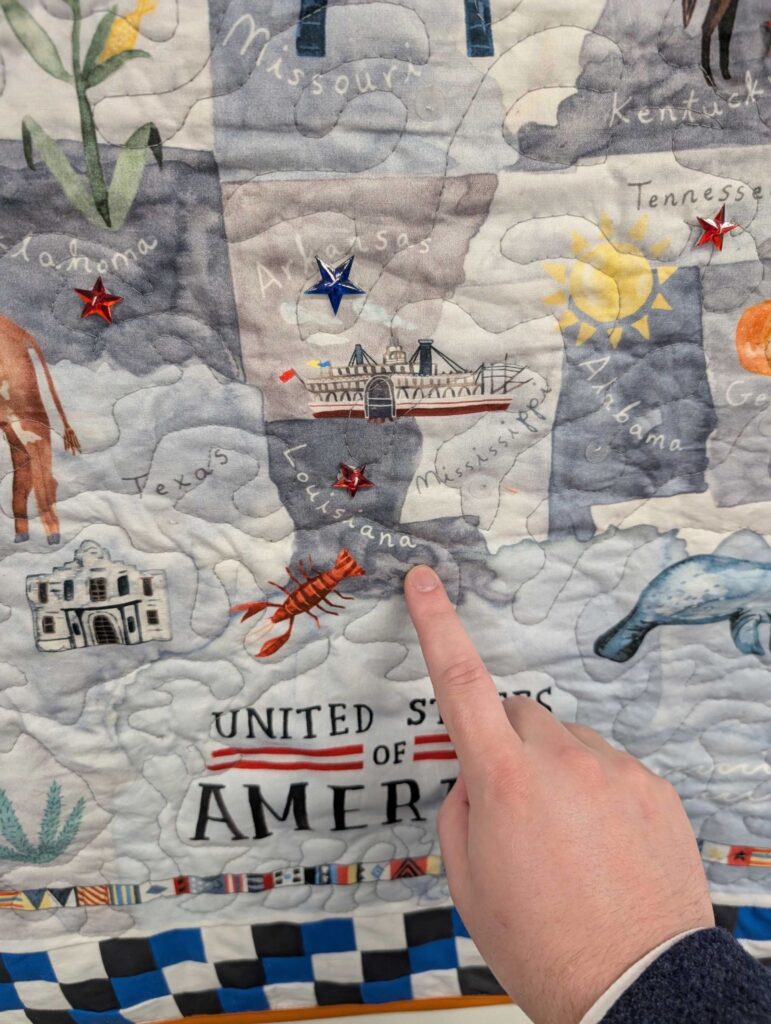
Pictured: Louisiana receiving its star on the FPF “Privacy Patchwork” quilt.
Comparing Enacted App Store Accountability Acts
On May 28, 2026, the 5th Circuit granted a stay on the preliminary injunction blocking enforcement of Texas’s App Store Accountability Act (ASAA)—meaning the law is now in effect while litigation on the merits continues. In 2025, Utah, Texas, and Louisiana enacted App Store Accountability Acts (ASAAs) which impose novel and significant age assurance obligations on app store providers and app developers. These laws require account holder age verification and parental consent for minors at the app store level, with age band and consent data transmitted between the two parties via bespoke “age signals.” Texas’s law was the first scheduled to go into effect on January 1, 2026. Before the law took effect, however, two groups filed suit challenging its constitutionality on First Amendment grounds. In December 2025, a federal judge issued a preliminary injunction blocking the law, finding it more likely than not an unconstitutional content-based regulation. Attorney General Paxton quickly appealed this decision to the 5th Circuit seeking a stay on the injunction, which was subsequently granted last week.
The uncertain constitutional outlook of ASAAs puts compliance teams in a difficult position. Moving slowly risks liability if the laws survive legal challenge; moving quickly risks sunken compliance costs if ASAAs are ultimately struck down—costs that could have otherwise been diverted to other important trust and safety priorities. While Utah’s, Texas’s, and Louisiana’s laws impose broadly similar obligations on app store providers and developers, important distinctions will shape how companies ultimately achieve compliance. Amendments to Utah’s and Louisiana’s laws in 2026 further shape the developing obligations in each state. FPF created a comparison chart detailing the key terms, scope, and core obligations of these laws, including changes incorporated by 2026 amendments. The chart also includes an Appendix detailing current information about Developer APIs released publicly by app stores to aid developers as these requirements go into effect.
Scope: These laws apply broadly to apps publicly available to consumers for download in an app store with very narrow exceptions, such as for settings apps or essential device drivers, and no wholesale exemptions from application. Uniquely, Louisiana also applies to apps that are available for download from an app store onto connected devices.
Obligations: These laws require app store providers to implement age verification and obtain parental consent for minor account holders making purchases, downloads, in-app transactions, or significant account changes. Utah and Louisiana extend this requirement to a minor’s first-time access to many pre-loaded apps. Developers must request and receive age signals from app stores, use that data to manage minor access, and implement appropriate safety features. Utah and Louisiana add notable nuances for developers, such as allowing them to request that app stores block minor access to their apps entirely, or permitting reliance on a primary account holder’s age data for “family account apps.”
Enforcement: Private rights of action (PRAs) are a trending enforcement mechanism in ASAA models. While Utah relies solely on a PRA for enforcement, Texas’s law only allows a PRA through incorporated references to the Deceptive Trade Practices Act (DTPA). Louisiana is the only law that does not include a PRA.
The ASAA trend has continued into 2026 with Alabama enacting a new ASAA law back in February. Alabama’s law largely tracks with the ASAA models in Utah and Louisiana following their 2026 amendments. As ASAA legislation and litigation continues to develop, the 5th Circuit’s stay on injunction means that compliance teams must figure out how to navigate this growing thicket of app store age signals and online safety requirements in the meantime.
No Silver Bullet, But a Silver Lining? PETs and International Data Transfers
Is there a role for Privacy Enhancing Technologies (PETs) to play in the context of international data transfers? The answer to this question could be one of the keys to unlock trusted cross-border data flows at scale in the age of AI.
This was the topic explored in a session organized by the Future of Privacy Forum (FPF) during the Global CBPR Forum in Lima, Peru. Bringing together technical, regulatory, policy, and academic perspectives, the session provided an in-depth overview of initiatives centering on PETs in data transfer developments. It included a technical presentation of two of the most promising such technologies available – trusted execution environments and differential privacy, as well as a recent use case from a US-UK policy pilot and a regional perspective on PETs adoption in Latin America.
The session highlighted both the growing maturity of PETs deployments, as well as the structural challenges that continue to shape their adoption. A central takeaway was that PETs are increasingly being positioned as enabling tools for data use and collaboration — particularly in contexts where legal, regulatory, or trust constraints have historically limited data sharing. By illustrating a specific medical use case and their technical features, speakers demonstrated how PETs can support more responsible data ecosystems and trusted data sharing.
You can read the full blog on the Global CBPR Forum’s website here.
Career Choice in the AI Age: What Next for Privacy and Data Professionals?
When I was in college, privacy existed but the privacy profession did not. Some cynics might say that the reverse is true now, but the reality is more complex: even amidst mounting pressures on individual privacy, there are arguably more privacy protections enshrined into law around the world than ever before.
One point, though, is beyond debate: the privacy profession is changing. The rise of AI and AI governance work, under the broad umbrella of privacy and compliance work, raises questions about law and policy, how to be effective internally, how to take basic data governance and map it to AI governance, and how to create sustainable governance structures and processes. But it also raises fundamental – and familiar – questions about how we map our careers and what choices we make.
Many of the first privacy professionals started by doing other things and in many cases being appointed by their organization to handle the new privacy issues that arose. I started in government affairs and lobbying and bounced into privacy via trust and safety. Many privacy lawyers were simply lawyers in legal departments working on contracts or compliance or intellectual property and were “volunteered” to handle privacy.
Over time a new generation of privacy pros arose, intentionally choosing to work on these interesting new issues. Some loved learning the new technologies. Some were attracted to the idea of upholding the core and important values of privacy. Others liked the multidisciplinary nature of the work. It was a basket of “cool” legal and policy issues on the leading edge of technology.
Eventually the profession got more specialized, with engineers, project managers, non-lawyers and the like finding important roles. And over time, the uphill nature of the work caught up with some privacy pros (but not all), giving rise to burnout from constantly feeling like the organization resists the compliance work or concept of risk that privacy pros perceive.
AI is a major technological leap, raises new issues of law and policy and governance, and arrived so fast that few data or AI professionals were in a position to intentionally choose the work they do now. This has implications for how people might think about their careers in data, privacy, and AI.
One might characterize privacy professionals in four categories since AI swept in.
Adopting – They love the job and they’re making it their own. They think the tech is cool, they’re optimistic about what AI will be able to do. The law, policy, and governance challenges are interesting. This work gives them purpose and meaning.
Adapting — Realistic and pragmatic, figuring it out and making it work. The adapters might be struggling because they didn’t really wish for AI; they wouldn’t have chosen it. They’re in a privacy role and now they must adapt to this new technology and this new set of issues and this new pace of change. They try to make the most of it but now career questions arise: Is this the work they want to do? Purpose and meaning are in question.
Enduring — Hanging on, fighting the good fight, until something else feels more rewarding. A sense of obligation or duty, such as a need to support a family, supplants purpose and meaning.
Resisting – Resistance takes two broad forms. The change is too much, there’s no interest in the technology, fear and anxiety predominate, and change is resisted. Some people withdraw. These are the “quiet quitters” who don’t know what to do, think they are in a comfort zone and don’t want to leave it. Alternatively, people get angry and rebel, resist, push back and try to stop it or bring about meaningful change.
Where Are You Going?
Maybe you see yourself in one of these categories. Maybe you fit into a category not mentioned here (tell us about it!). For three of the four, career choices loom: Is this what I want to work on, work that chose me that I did not choose? What’s next?
Here are some helpful lenses or frameworks to think about the career choices and mapping we face:
Run toward, not away. It’s important to feel like you’re running towards something desirable rather than running away. That means you need to do the work to figure out what you want. That often connects to a deeper meaning or purpose.
Enlarge, not diminish. Another useful lens for looking at big decisions (career or otherwise) is an idea put forth years ago by James Hollis, a Washington DC area psychologist. He suggests asking this question: “Does this choice diminish me, or enlarge me?”2 It’s a powerful question. If working on AI makes you feel bigger in the organization, or it feels like growth to you or it makes you feel more influential more on top of things then that’s clearly a good choice – for you. If it makes you feel smaller, like you’re being pushed down in the organization, like you can’t keep up, like you’re overwhelmed, then maybe this isn’t a good choice and a good place to stay in your career.
Practice, practice, practice. What is the practice in your profession, the thing you seek to perfect? Surgeons seek to get better at surgery. Pianists practice to constantly get better. Professional athletes, lawyers, teachers, coaches, all seek to get better at what they do. That refinement of the craft, through daily practice, provides meaning and focus. What is it in your role that is the daily practice, the craft you seek to refine, the talent you seek to develop? If that question is hard to answer, it might be time for a change.
When in doubt, choose growth. So often what feels like languishing or burnout might simply be an absence of growth. Feeling like we are growing creates meaning and focus. Horizontal growth, the learning of new information, broadening one’s horizons, can be entertaining but insufficient. Vertical development – growing soft skills, ability to lead people and across teams, expanding impact in the org or profession – is more meaningful for people. Are you growing now? What would feel like growth to you?
What changes if you have a clear destination or desired outcome to move toward? What does it feel like to simply move and act and see where change takes you – or leaves you?
We hope we don’t have to simply endure. If we do, we might hope we’d have the courage to resist. In the end, we will all have to be adapters, but what could it feel like to intentionally choose? What would it feel like to find direction and purpose, to feel new growth and adopt one’s work, role, and the technological change underway?
It’s important to be clear about what’s happening with you, to identify which category above you’re in and find a lens through which to see your choices. If you’re just making it up as you go along, you might still find yourself in a place you don’t want to be. It’s normal human behavior to want to stay in our comfort zones, but how can a place where you merely endure and do not grow be a comfort?
Privacy and data professionals are multi-faceted and multi-talented people. They may be guided by core values like privacy, excited by technology, eager to launch new products, or simply do good work. The lenses set out above are not the only ones: you can start with why, think about what you long for, explore the Ikegai matrix, or any number of other ways to think about what’s next. But make a choice, rather than let events simply happen to you. Our careers are often set up as default opt-out, but we can choose to opt-in to the work that fulfills us. AI presents us with that choice.
Twelfth Night, Act II scene 5: “Be not afraid of greatness: some men are born great, some achieve greatness and some have greatness thrust upon them.” ↩︎
James Hollis, What Matters Most: Living a More Considered Life, p.13. “Ask yourself of every dilemma, every choice, every relationship, every commitment, or every failure to commit, “Does this choice diminish me, or enlarge me?” Do not ask this question if you are afraid to find the answer.” ↩︎
FPF Releases Practitioner Guides on Privacy Enhancing Technologies for Education Stakeholders
The Future of Privacy Forum (FPF) has released a suite of practitioner resources on Privacy Enhancing Technologies (PETs) for the education sector. Building on FPF’s 2025 landscape analysis of PETs adoption by State Education Agencies, the new resources move from landscape analysis to implementation considerations — providing audience-specific guidance for the three practitioner communities most responsible for handling student data: state education agencies and statewide longitudinal data systems, education researchers, and EdTech vendors.
FPF worked with AEM Corporation to develop the resources, which include three practitioner guides and a comparative reference chart covering seven PETs relevant to education data environments.
Addressing a Gap Between Awareness and Practice
FPF’s 2025 landscape analysis found that awareness of PETs among education practitioners remains limited, and that even practitioners who understand what PETs are often lack the use case guidance needed to match a specific technology to a specific workflow. The new guides are designed to close that gap. Each is written for its audience’s actual decision context —as a practical resource for the people who manage longitudinal data systems, design research studies, or build and test EdTech products using student data.
“State education agencies, researchers, and EdTech vendors all work with student data, but they face different risks, different analytical requirements, and different governance obligations,” said Jim Siegl, FPF Senior Fellow for Youth & Education Privacy. “These guides are designed to help each audience understand not just what PETs can do, but what each approach costs analytically — and how to make and document those tradeoffs responsibly.”
What the Guides Cover
Privacy Enhancing Technologies for State Education Agencies: A practical guide to privacy-preserving computation for state education data systems addresses the specific challenges of SEA and SLDS environments, where linked longitudinal records create both high analytical value and elevated re-identification risk. The guide explains how PETs can reduce how often student-level data must be copied, moved, or distributed to support analysis, and provides use case guidance for cross-agency computation, public reporting, and research partnerships. It also addresses a tension that is particularly acute in state education data: the student populations most at risk of re-identification — small districts, low-incidence disability categories, and rare demographic combinations — are often those for whom noise-based methods like Differential Privacy perform least well analytically.
Privacy Enhancing Technologies for Education Researchers: A practical guide to conducting education research with reduced data exposure addresses the analytical tradeoffs researchers need to understand before selecting a PET for a given study. Results produced under Differential Privacy carry an epsilon parameter that should be reported. Synthetic data findings require disclosure of generation methodology and fidelity validation. The guide frames PET selection as a methodological decision with implications for replication and publication, not just a data governance requirement.
Privacy Enhancing Technologies for EdTech Vendors: A practical guide to handling student data across product, testing, and analytics workflows addresses the range of vendor workflows — system testing, staff training, product analytics, and collaborative research with agencies — that involve student data and carry different PET requirements. The guide emphasizes that vendors operate under a dual obligation: to deliver useful analytics and product capabilities, and to handle student data in ways that honor the trust schools and agencies have placed in them. It includes guidance on transparency with agency partners when PET-protected outputs are shared, including disclosure of noise parameters and fidelity limitations.
The Comparison Chart
Accompanying the three guides is a comparative reference chart covering seven PETs — Differential Privacy, Synthetic Data, Federated Learning, Trusted Execution Environments, Secure Multi-Party Computation, Homomorphic Encryption, and Zero-Knowledge Proofs — across six dimensions: approach, benefits, limitations, example use case, data utility impact, and implementation complexity. The chart is designed as a standalone reference for practitioners who need to quickly orient to the PET landscape or compare options for a specific workflow, without reading all three guides in full.
Selecting the Right PET
A consistent theme across all three guides is that PET selection is a methodological decision, not a compliance checkbox. Each approach involves a tradeoff between privacy protection and analytical precision, and that tradeoff varies by method and by context. Differential Privacy introduces noise that grows more distorting as group sizes decrease. Synthetic data may misrepresent rare populations. Secure Multi-Party Computation and Trusted Execution Environments constrain which analyses can be run. Federated Learning reduces raw data exposure but can produce less accurate models when district data is heterogeneous.
The guides encourage practitioners to identify the acceptable level of analytical imprecision for their specific workflow before selecting a PET, to document that choice and its rationale, and to disclose relevant parameters — such as epsilon values for Differential Privacy or fidelity validation results for synthetic data — where outputs are shared or published. PETs work best when integrated into existing data governance frameworks rather than treated as standalone solutions.
FPF has actively contributed to shaping policy and practice around PETs through discussion papers, reports, stakeholder engagement, and its PETs Repository, launched in November 2024 as a centralized resource for practitioners seeking practical information about these technologies. The new practitioner guides extend that work by providing the audience-specific implementation guidance the landscape analysis identified as a critical gap.
SB 5 in Five: What to Know About Connecticut’s New AI Law
Connecticut’s SB 5 fits a lot of AI obligations into a small bill number. This week, Governor Lamont (D) signed the 39-section bill into law, creating new requirements across several fast-moving areas of AI policy, including companion chatbots, automated employment decision tools (AEDTs), social media, and provenance data. The law also includes provisions related to frontier AI whistleblower protections, AI-related layoff notices, and planning for a state AI regulatory sandbox, making it one of the broader state AI packages enacted this year. The law’s provisions phase in over time, with effective dates ranging from October 2026 to January 2028.
The law follows several years of debate in Connecticut over how to regulate AI, including last year’s SB 2, which cleared the Senate but ultimately fell apart after a veto threat from Governor Lamont over concerns that the bill could hamper innovation. SB 5 takes a different path. Rather than establishing a single comprehensive high-risk AI framework, it stitches together a set of more targeted obligations, alongside provisions focused on innovation, workforce development, and future study.
The result is a wide-ranging law that touches many of the AI issues currently moving through state legislatures. With so much packed into SB 5, here are five things to know about Connecticut’s new AI law.
Note: The Governor also signed SB 4, a broad privacy bill that establishes a data broker registry and accessible deletion mechanism, regulates data-driven pricing, updates the CTDPA, and regulates direct-to-consumer genetic testing, which is covered in FPF’s recent blog.
Companion chatbots get their Connecticut chapter
SB 5 gives companion chatbots their Connecticut chapter, adding the state to a growing list of jurisdictions (New York, California, Washington, Oregon, Nebraska, Idaho, Iowa, and Georgia) writing rules for chatbot systems that can sustain relationships with users. The law would impose baseline protections for all users, including safety protocols for suicidal ideation and clear non-human disclosures, while also introducing minor-specific safeguards such as parental tools to manage privacy and screen time, as well as limits on engagement-maximizing features. For those following this rapidly evolving area, FPF maintains a continuously updated chatbot legislation trackerthat monitors activity in this space.
Scope: SB 5 uses a detailed set of carveouts to narrow the systems covered, similar to Nebraska’s and Idaho’s laws. But Connecticut’s definition of “AI companion” is more targeted: it focuses on systems that provide adaptive, human-like responses and can sustain a relationship over time. One carveout is especially notable: the law excludes “narrow, task-specific” tools that provide outputs related to a discrete topic or function, so long as the tool’s primary function is not to discuss mental health. Similar narrow-task carveouts appear in other state chatbot laws, but Connecticut’s version appears narrower because the exclusion may not apply where the tool’s primary function is mental health-related.
Requirements for all users: SB 5 follows several other companion chatbot laws enacted this year in setting a familiar baseline: safety protocols, non-human disclosures, and safeguards to keep AI companions from presenting themselves as human. Operators would need to publicly post safety protocols using “evidence-based methods” to detect and “clinical best practices and expertise” to respond to user expressions indicating suicide, self-harm, or physical violence. Because “evidence-based methods” and “clinical best practices” are not defined, operators may face questions about what detection tools or clinical inputs are sufficient to meet that standard.
The law would also require clear non-human disclosures when an AI companion could reasonably lead a user to believe they are interacting with a human. Like Washington and Georgia, Connecticut applies a one-hour disclosure interval for minors and a three-hour interval for adults. Although the law distinguishes between users, the shorter minor-focused interval could become the practical default if operators choose to comply uniformly.
Minor-Specific Requirements: For minors, SB 5 moves beyond “tell users it is AI” and into the harder question of how companion chatbots are designed to interact and build relationships over time. Similar to Oregon’s law, Connecticut’s protections apply when an operator “knows or has reason to believe” that a user is under 18, a standard that may require operators to account for contextual signals, not just direct knowledge of age.
Similar to Washington’s chatbot law, SB 5 would require operators to prevent their chatbots from engaging in certain harmful conduct before providing an AI companion to a minor, including encouraging disordered eating or physical violence; romantic interactions; and manipulative techniques intended to extend engagement, such as encouraging isolation from family or friends or fostering inappropriate emotional dependence. Terms like “inappropriate emotional dependence” and “disordered eating” are not further defined, raising questions about how operators should distinguish benign interactions from those prohibited under the law. The law also includes a broader provision prohibiting operators from “optimizing user engagement in any manner that disregards” the minor-specific safeguards, which may extend the reach of the minor protections beyond listed outputs.
Finally, SB 5 also requires tools for parents and minors to manage screen time and account settings, a feature that appears in other state chatbot laws, including Idaho, Nebraska, and Georgia.
Enforcement: SB 5 would make violations an unfair or deceptive trade practice enforced by the Attorney General, keeping the law in the AG-enforcement lane rather than creating a private right of action. These requirements take effect January 1, 2027.
For employment AI, SB 5 asks for a heads-up, not an audit or assessment
Employment AI gets its turn in SB 5, with new transparency requirements for automated employment-related decision technologies (AEDTs) used to shape decisions about hiring, promotion, discipline, and discharge. The section draws from broader ADMT laws, including California’s CPPA ADMT regulations, the Colorado AI Act as originally enacted in 2024, as well as employment-specific laws such as New York City’s LL 144. But unlike other state frameworks, Connecticut does not require AEDTs to undergo bias audits or risk assessments. Instead, SB 5 focuses on disclosures and written notice to applicants and employees, similar to the revised Colorado ADM Act.
Scope: SB 5 is narrower than broader ADMT frameworks that apply across sectors such as housing and education. It covers AEDTs that are a “substantial factor” used to “make or materially influence” an employment-related decision. The law defines “substantial factor” as something that “meaningfully alters” the outcome, a narrower definition than the Colorado AI Act’s 2024 language covering systems that are “capable of altering” or “assist” in making a consequential decision.
Notice obligations: The notice obligations are allocated between actors in the AI value chain, similar to the current and previous version of the Colorado AI law. Beginning October 1, 2027, developers that market AEDTs for employment decisions would need to provide deployers with information about the tool. Deployers would then need to disclose to employees or applicants that an AEDT has been deployed, the purpose and nature of the decision, the tool’s trade name, the categories and sources of personal data used, how that data will be assessed, and contact information for the deployer. Developers and deployers do not need to disclose trade secrets, but must tell individuals when information is withheld on that basis.
Civil rights and enforcement: SB 5 may be notice-first, but it is not notice-only. The law also amends Connecticut’s human rights statute to clarify that using an AEDT is not a defense to discrimination claims, while allowing courts or the commission to consider evidence of anti-bias testing and related efforts when evaluating those claims. That consideration of anti-bias testing also builds on a related theme in last year’s amendments to the Connecticut Data Privacy Act, which included an exemption allowing controllers to process personal data for internal use to allow them to use data for bias testing. California and Illinois have similarly amended employment or human rights laws to address automated decision systems in the workplace. As a result, entities may not be required to conduct bias testing or assessments under Connecticut law, but are strongly encouraged to reduce their regulatory risk.
Violations would be treated as unfair or deceptive trade practices and enforced by the Attorney General, with a potential 60-day cure period through the end of 2027 and no private right of action. These requirements take effect October 1, 2026.
Social media and AI regulations increasingly become the dynamic duo in online safety
As the online safety landscape continues to evolve and other jurisdictions weigh pairing social media and chatbot regulations—Connecticut strikes first by incorporating a section on online safety obligations for social platforms into SB 5. Similar to laws enacted in California and New York, SB 5 restricts operators from providing minors under 18 access to a platform that “recommends, selects, or prioritizes for display…media items” shared by other users—also known as personalized recommender systems–unless certain requirements are met.
Age assurance and parental consent: As is commonly the case in social media frameworks, SB 5 requires that covered operators implement “commercially reasonable and technically feasible methods” to determine whether a user is an adult or a minor. In the case of a minor, a covered operator may not offer access to personalized recommender systems without first obtaining parental consent. Unlike California and New York, however, SB 5 does not authorize agency rulemaking to provide guidance on acceptable forms of age assurance under this law, potentially creating ambiguity for compliance teams.
Default safety features: The law also requires certain minor-specific default safety features seen in other recent frameworks, such as South Carolina’s Age Appropriate Design Code (AADC), including preventing unconnected users from viewing or contacting minor accounts and restricting minors from viewing “sensitive content.” Notably, SB 5 broadly defines “sensitive content” to include any material violative of platform community standards, “or any similar guidelines or standards” established by the covered operator. Lastly, in a novel move, covered operators would be required to limit minors’ access to personalized recommender systems to one hour per day by default, comparable to a recently enjoined obligation in Virginia. Only a minors’ parent can adjust the default time limit on personalized recommender system access through parental control mechanisms.
Parental controls: Covered operators must establish and provide parents or guardians access to prescribed controls for supervising the accounts of their children. These controls include providing parents the ability to prevent minors from receiving notifications outside of preset timeframes and limiting minor access to personalized recommender systems to specific times indicated by the parent. SB 5 would also require covered platforms to provide parents with a mechanism for setting the minor’s account to a protected mode that does not allow unconnected users to view published content of or exchange messages with minors—although it is unclear how this particular parental tool is supposed to be implemented alongside the seemingly identical default safety feature noted above.
Disclosures: SB 5 requires covered operators to provide two kinds of disclosures. First, minors must be provided a health warning from the Surgeon General concerning the potential harms of social media use. Secondly, covered operators must annually disclose to the state Attorney General’s office, in a publicly accessible format, information related to platform use, such as the total number of covered users for whom the covered operator obtained parental consent, enabled default settings, and the average amount of time covered users spent on the platform per day. SB 5’s reliance on disclosure obligations follows a growing trend of requiring various kinds of disclosures in online safety legislation to both individuals, like in Colorado’srecently enjoined social media warnings law, and to state entities for public accessibility, like in South Carolina’s AADC.
Enforcement: A covered operator’s violation of these requirements constitutes an unfair or deceptive trade practice under Connecticut consumer protection law, which includes a private right of action in addition to state enforcement authority. These requirements become effective on January 1, 2028.
AI provenance rules make their way east in SB 5
SB 5 picks up the provenance trend seen in western states–adding Connecticut to the growing list of states setting requirements for AI-generated content. SB 5 would require covered providers to include provenance data in content that is created or materially altered by a generative AI system. California spearheaded AI provenance data disclosure with the California AI Transparency Act, enacted in 2024 and amended in 2025. Other states with provenance data laws include Utah and Washington.
The provision is relatively targeted. It applies to covered providers that produce publicly accessible generative AI systems for personal use with more than 1 million monthly users. It also focuses on content that is created or “materially altered” by a generative AI system, while excluding minor modifications such as changes in color or resizing. That distinction helps to focus the law’s requirement on more meaningful generative AI edits, rather than changes unlikely to affect the substance of the content.
The law requires provenance data to be difficult to tamper with or remove. At the same time, covered providers are not required to include information relating to an identified or reasonably identifiable individual, trade secrets, or confidential or proprietary information.
These provenance requirements are narrower than SB 5’s provisions on chatbots or AEDTs, but still notable because they place Connecticut within a growing state-level push to make AI-generated and altered content easier to trace. Other provenance data bills are still pending in states like Arizona and New Jersey. These requirements take effect October 1, 2026.
Whistleblowers, layoff notices, and sandboxes get targeted treatment in SB 5
SB 5 also borrows from a few other state AI playbooks, like frontier AI protections and regulatory sandboxes. But in both cases, Connecticut takes a narrower path. Rather than creating a full frontier model governance framework or immediately launching a sandbox program, SB 5 focuses on employee whistleblower protections and planning for a potential future sandbox, as well as a targeted AI-related layoff notice requirement.
Frontier AI whistleblower protections: SB 5 borrows the language of frontier AI laws, but not the full architecture. Like California’s SB 53 and New York’s RAISE Act, it defines key terms such as “frontier developer,” “large frontier developer,” and “catastrophic risk.” But unlike broader frontier AI frameworks, SB 5 does not require developers to publish governance frameworks, issue transparency reports, or establish critical safety incident reporting mechanisms. Instead, it focuses on solely protecting employees who report certain serious AI-related risks.
The law would prohibit frontier developers from penalizing covered employees for protected whistleblower activity and bar retaliation against employees who report, with reasonable cause, conduct they believe poses a specific and substantial danger to public health or safety due to a catastrophic risk. Large frontier developers would also need to create an internal reporting process by January 1, 2027, allowing employees to anonymously report such risks, provide updates to reporting employees, share reports with directors quarterly, and notify employees of their rights. These requirements take effect October 1, 2026.
AI-related layoff notices: SB 5 also includes a workforce disclosure provision. Employers issuing plant-closing or mass layoff notices would need to disclose to the Labor Department whether the layoffs are related to the employer’s use of AI. These requirements take effect October 1, 2026.
Regulatory sandbox planning: SB 5 directs the Commissioner of Economic and Community Development to develop a plan for an AI regulatory sandbox program, joining a small but growing group of states (Utah, Texas, and Delaware) that have adopted AI sandbox frameworks. The program would allow approved applicants to test innovative AI systems under reduced regulatory requirements.
But here too, Connecticut starts with a blueprint. SB 5 requires planning for a potential sandbox, not the immediate launch of one, and asks the Commissioner to assess the feasibility of a reciprocal, multistate sandbox model. Recommendations are due by January 1, 2028.
Conclusion
SB 5 does not create one comprehensive AI framework. Instead, it reflects a broader trend in state AI policymaking of setting targeted obligations across several use cases, from companion chatbots and employment tools to provenance data and frontier AI employee protections. As states continue experimenting with issue-specific AI laws, Connecticut’s SB 5 offers another example of how significant AI regulation can emerge through issue-specific provisions. Additionally, as states continue to pursue substantive online safety frameworks for minors, whether other jurisdictions will pair social media regulation with chatbot safety requirements remains a trend to watch.
Third Time’s the Charm: Connecticut Enacts Annual Privacy Update
The Connecticut Data Privacy Act (CTDPA) has been revised multiple times since being enacted in 2022: SB 3 added heightened protections for consumer health data and for minors in 2023; and SB 1295 in 2025 expanded the law’s scope, updated and added consumer rights, modified the data minimization and purpose limitation requirements, prescribed impact assessment requirements for profiling, and further heightened protections for minors. Like clockwork, Connecticut has once again passed new privacy legislation.
This year’s efforts include more CTDPA amendments, a new California Delete Act–style data broker registry and accessible deletion mechanism, restrictions on data-driven pricing, and regulation of direct-to-consumer genetic testing. These changes came in a trio of bills: SB 4, HB 5222, and HB 5563. The bulk of the new requirements are located in SB 4, but, due to legislative procedure and timing, there were additional ‘clean-up’ amendments to SB 4 in the other two bills. Governor Lamont signed SB 4 on May 27. Although at the time of publication we are still waiting for HB 5222 and HB 5563 to be signed, this blog post assumes that these bills will be enacted and provides an overview of all three bills’ main requirements.
Key elements of these bills:
Privacy Updates: The CTDPA amendments are less significant than prior revisions in SB 3 or SB 1295. The biggest change is that the law will now ban the sale of precise geolocation data, whether by a controller or a third party. The amendments also narrow the definition of publicly available information, expand the deletion rights, and add transparency requirements for the use of facial recognition technology for security/fraud prevention.
Data Brokers: Connecticut becomes the second state to enact a Delete Act that both requires data brokers to annually register with the state and creates an accessible deletion mechanism allowing consumers to submit deletion requests to many data brokers at once.
Data-Driven Pricing: Amidst growing public scrutiny over data-driven pricing, this law bans “surveillance pricing” by a retail seller or third-party delivery service, subject to exceptions, and subjects any other person engaged in “surveillance pricing” to mandatory disclosures.
Genetics: Connecticut becomes the latest state to regulate direct-to-consumer genetic testing companies. This law includes a slightly unusual “property” right for consumers over their biological samples and DNA testing results.
Note: The legislature also passed SB 5, a broad AI bill that addresses companion chatbots, automated decisionmaking technology, social media, and other AI-related provisions. If that bill is signed by the Governor, then FPF will cover it in a separate blog post.
The updates to the CTDPA primarily affect publicly available information, the consumer deletion right, the sale of precise geolocation data, and the use of facial recognition technology for security purposes in retail. Many of these changes are responsive to legislative recommendations in enforcement reports from the Connecticut AG.
Publicly Available Information: This bill narrows the definition of “publicly available information,” including by adding exceptions for obscene visual depictions, information created by combining personal data with publicly available information, genetic data (unless made publicly available by the consumer), information provided by a consumer on a publicly accessible website or online service (subject to additional criteria), nonconsensual intimate images, and nonconsensual intimate synthetically created images.
Deletion: Prior to SB 4 being enacted, the deletion right extended to personal data provided by, or obtained about, the consumer. This bill expands that right to also apply to some publicly available information. Specifically, a consumer shall have the right to delete (i) publicly available information that is collated and combined to create a consumer profile made available to a user of a publicly accessible website for compensation or free of charge, (ii) publicly available information made available for sale, or (iii) any inference generated from information described in (i) or (ii).
Precise Geolocation Data: This bill prohibits controllers or third parties from selling a consumer’s precise geolocation data. This is consistent with an emerging trend in state privacy law. Maryland banned the sale of sensitive data in 2024. Both Oregon and Virginia banned the sale of precise geolocation data in 2025 and 2026, respectively.
Facial Recognition Technology: Like most state comprehensive privacy laws, the CTDPA includes a broad exception for preventing, detecting, protecting against or responding to security incidents, identity theft, fraud, and similar activities. This bill adds new requirements for a controller (or consumer health data controller) who uses facial recognition technology (“FRT”) pursuant to that exception. FRT is defined as “any technology that analyzes facial features in still images or video to uniquely and personally identify a specific individual.” Notably, this definition does not reference the existing definition of “biometric data.” To use FRT for the security/fraud exception, a controller must: (i) exclusively use FRT to match still images or video to a database maintained exclusively by the controller; and (ii) post clearly legible signage at entrances (other than an entrance to an area restricted to authorized employees) that alerts consumers that FRT is in use and provides a conspicuous hyperlink or quick response code that directs consumers to the controller’s FRT policy. The FRT policy that a controller maintains must include contact information for the AG’s office and “may” disclose the controller’s policies concerning “interactions between the controller’s . . . loss prevention officers and consumers.” A controller is not required to comply with these requirements if they have obtained the consumer’s consent to use FRT “in the course of a commercial transaction.”
These requirements will be effective October 1, 2026.
Data Brokers (SB 4, Sections 1-10; HB 5222, Sections 39-43)
Connecticut joins California, Oregon, Texas, and Vermont by creating a data broker registry. Starting January 1, 2027, this bill would prohibit a “data broker” from selling or licensing “brokered personal data” in Connecticut unless the data broker is actively registered with the Department of Consumer Protection.
Data Broker: Any business or portion of a business that sells or licenses brokered personal data to another person;
Brokered Personal Data: One or more of the listed personal data elements concerning a consumer, if categorized or organized for sale or license to a third party. These data elements include name, address, date or place of birth, mother’s maiden name, unique biometric data (used to identify or authenticate the consumer), name or address of a member of the consumer’s immediate family or household, SSN or other government-issued ID number, or other information that (alone or combined) would allow a reasonable person to identify the consumer with reasonable certainty.
Notable exemptions include: personal data collected or sold in compliance with the Driver’s Privacy Protection Act; consumer reporting agencies and furnishers to the extent they are engaged in activities regulated by FCRA; financial institutions, affiliates and nonaffiliated third parties to the extent they are engaged in activities regulated under Title V of GLBA; covered entities, business associates, and protected health information under HIPAA; and narrow exceptions for activities such as selling or licensing publicly available information (defined narrowly), providing digital access to materials such as newspapers, or providing directory assistance.
Registration will be annual, cost $2,500, and require applications to include extensive, mandated disclosures (e.g., a public website with information on how consumers can exercise consumer rights under the CTDPA, whether the data broker collects certain listed categories of personal information, whether and to what extent the data broker is subject to regulation under FCRA, GLBA, and HIPAA).
The Commissioner of Consumer Protection will establish and update a public website disclosing the information each data broker includes in its registration application. Similar to the California Delete Act, this bill will also require the state to—by July 1, 2028—establish an accessible deletion mechanism that will allow consumers to submit a single deletion request to (up to) all registered data brokers. The Commissioner has authority to adopt regulations to implement sections 2-8 of the bill. Data brokers will be required to comply with deletion requests submitted via the accessible deletion mechanism once every 45 days starting on October 1, 2028. Also consistent with the Delete Act, data brokers will be required to undergo independent third-party audits once every three years (starting in 2031). The penalties under the new data broker provisions are $200 per day per consumer for each violation.
There are two unique aspects of Connecticut’s data broker requirements worth flagging. First, the law is scoped broadly and, unlike other state data broker laws, does not clearly carve out data collected in the context of a first-party relationship. For example, most laws define a data broker as a business that (1) collects and sells personal information concerning a consumer with whom the business does not have a direct relationship, or (2) sells personal data that the business did not collect directly from the consumer. The closest thing to a first-party relationship exception in this bill is a carve out for a business that collects information concerning a consumer if the consumer is or was “in a contractual relationship with the business” or any “similar” relationship. This provision is similar to, but less defined than, language in Oregon’s and Vermont’s laws carving out a business that collects information about a consumer who is a past or present customer, subscriber, or user of the business’s goods or services.
The second ambiguity to note is inconsistent scoping regarding “brokered personal data” versus “personal data.” For example, the obligation for data brokers to comply with a verified deletion request provides that a data broker must “delete any personal data such registered data broker maintains concerning the participating consumer.” This bill adopts the definition of “personal data” from the CTDPA: “any information that is linked or reasonably linkable to an identified or identifiable individual.” However, that term is broader than “brokered personal data,” as utilized within the definition of “data broker,” which is limited to an enumerated list of identifiers. As a result, data brokers may be required to delete more information than what is required to label them as a data broker.
Data-Driven Pricing (HB 5563, Section 501)
This bill (1) bans surveillance pricing by a retail seller or third-party delivery service, subject to exceptions, and (2) subjects any other person engaged in surveillance pricing to mandatory disclosures.
Surveillance Pricing: Establishing a customized price for a consumer good or service that is specific to a consumer (or group of consumers) based in whole or in part on the consumer’s personal data collected (A) through any technology or technological method, system, or tool [examples given include biometric monitoring, camera, device tracking, or sensor] and (B) by the person establishing the customized price, directly or indirectly.
The following activities do not constitute “surveillance pricing,” provided that the retail seller or third-party delivery service prominently posts the discount, discounted price, and terms and conditions in language readily understandable by the average consumer:
Establishing a discounted price for purposes such as retaining a customer, reestablishing a customer, attracting a new customer, cross-selling an item, or reengaging a lapsed customer;
Establishing different prices due to justifiable differences in costs incurred in providing the good or service (e.g., due to physical location or delivery distance) or justifiable temporal differences;
Establishing a discounted price
based on publicly disclosed uniform terms and conditions available to any consumer,
available to all consumers in a broadly defined group (e.g., veterans) based on publicly disclosed discounts and uniform terms and conditions, or
through a loyalty, membership, or rewards program that a consumer affirmatively enrolls in; and
Correcting an erroneous price.
Retail Seller: A retailer (including retail food establishments) engaged in making sales, at retail, of “tangible personal property” (which includes “digital goods”).
Third-Party Delivery Service: An entity—outside of the operation of a retail food establishment’s business—that facilitates delivery or online ordering services to customers of a retail food establishment.
The prohibition on surveillance pricing is narrowly targeted to retail sellers and third-party delivery services. Earlier this year, Maryland enacted a similar but narrower law, the Protection From Predatory Pricing Act (HB 895), which regulates food retailers’ and third-party delivery service providers’ use of dynamic pricing, personal data, and protected class data in setting prices for food.
The disclosure requirements broadly apply to “any person” doing business in Connecticut who engages in surveillance pricing for any reason other than to establish a discounted price for a consumer good or service as part of an online transaction, and who (online) advertises or promotes the price, labels a consumer good with the price, or publishes a statement, image, or announcement disclosing the price. These requirements include providing a mandated disclosure stating “THIS PRICE WAS INCREASED USING YOUR PERSONAL DATA” and informing consumers of their rights under the CTDPA. The disclosure must be “readily visible to the average consumer.” No disclosure is required if the price is the bona fide market price, as defined in the bill. The disclosure requirement is similar to that under New York’s Algorithmic Pricing Disclosure Act.
These provisions are subject to entity-level exemptions, including for persons licensed to operate under the state’s insurance laws and persons whose activities are based on data provided in a consumer report covered by FCRA or data reflecting factors a credit can consider under the Equal Credit Opportunity Act.
Violations of these provisions will be enforced exclusively by the AG as unfair or deceptive trade practices. These requirements will be effective February 1, 2027.
Procedural Note: HB 5563 is substituting its own data-driven pricing requirements in place of those in HB 5222, which was in turn repealing and substituting the data-driven pricing section in SB 4.
Genetic Testing (SB 4, Sections 17-19)
In their most recent enforcement report, the Connecticut OAG “urge[d] the legislature to adopt a standalone genetic data privacy law.” This bill responds to that call, making Connecticut the second state this year after South Dakota (SB 49) to enact a direct-to-consumer genetic testing privacy law. The requirements for direct-to-consumer genetic testing companies include—
Transparency and mandatory disclosures to consumers;
Obtaining express consent for collecting, using or disclosing a consumer’s genetic data;
Obtaining separate consent for disclosures or transfers of genetic data to any person other than a vendor or service provider, secondary uses of genetic data, and retention of a biological sample after completion of the testing;
Obtaining informed consent pursuant to 45 C.F.R. Part 46 for disclosure or transfer of genetic data to a third party for research purposes;
Limits on disclosing consumers’ genetic testing results to any person other than the consumer (without express consent or pursuant to a court order, warrant, or subpoena);
Limits on disclosing a consumer’s genetic data to the consumer’s employer, certain insurers, or third parties whom the company knows or reasonably should know intend to use the data for marketing or targeted advertising;
Implementing reasonable security measures to protect biological samples and genetic data; and
Implementing a process for consumers to access their genetic data, have their genetic data deleted, have their biological samples destroyed, and revoke previously given consent for research.
Similar to Texas’s law, this law also provides consumers with a “property right in, and . . . the right to exercise exclusive control over,” their biological samples used by a direct-to-consumer genetic testing company as well as results of DNA testing by the company. These requirements will be effective October 1, 2026.
On May 15, Governor Polis signed SB 189, revising the Colorado AI Act (CAIA) after two years of intense negotiations and national debate over the original 2024 law’s approach to AI regulation. The revised law, the Colorado ADM Act (CADMA), reflects a fundamental shift in approach: shifting from an algorithmic discrimination framework to a transparency-focused one, as well as narrowing the scope of covered AI systems, streamlining disclosures and consumer rights, and replacing governance requirements with liability allocation under existing anti-discrimination laws.
This post examines the key changes between CAIA and CADMA, explores the context that drove these revisions, and analyzes their practical implications. Side-by-side legislative comparison chart below.
Regulates developers and deployers of covered automated decision-making technologies (ADMT) used for making consequential decisions regarding covered domains (e.g., education, employment, financial or lending)
Requires developers to provide deployers a general statement that includes information regarding the covered ADMT.
Requires deployers to disclose to consumers use of covered ADMT for consequential decisions prior to use.
Requires deployers to notify consumers whether and to what extent a covered ADMT contributed to a consequential decision if an adverse decision is reached.
Provides consumers certain rights if an adverse decision is reached pursuant to deployers’ use of a covered ADMT, including rights of explanation, correction, and appeal.
Clarifies that developers and deployers are subject to existing anti-discrimination law, while developers’ liability is limited to intended use of covered ADMT.
The law will be enforced by the Colorado Attorney General (AG), with no private right of action, and go into effect January 1, 2027.
From Anti-Discrimination Governance to Transparency
Enacted in 2024, Colorado SB 205 (Colorado AI Act) (CAIA) aimed to mitigate risks of discriminatory outcomes from AI-driven decisions in consequential domains by regulating how such systems are developed and deployed. The law subjected developers and deployers to a duty of care to protect consumers from algorithmic discrimination, with such duty presumptively fulfilled if the developer or deployer complied with the Act’s requirements. For developers, those requirements included: disclosing information to deployers regarding known limitations, possible biases, and risk mitigation measures; making publicly available information regarding high-risk AI systems and known or foreseeable risks of algorithmic discrimination; and notifying the state AG upon discovery that a high-risk AI system caused algorithmic discrimination. For deployers, those requirements included: maintaining a risk management policy and program to identify and mitigate the risk of algorithmic discrimination; annually conducting impact assessments on high-risk AI systems; publicly disclosing information regarding high-risk AI use and how known or foreseeable risks of algorithmic discrimination were managed; and also notifying the state AG upon discovery of algorithmic discrimination. See full overview of requirements in FPF’s Colorado AI Act Policy Brief(2024).
CADMA eliminates CAIA’s governance requirements and references to algorithmic discrimination, focusing instead on transparency. Where risk is mentioned, it refers only to undefined “known risks” or “known limitations” rather than discrimination-specific concerns. Key areas of this shift include:
Removal of the duty of care to mitigate algorithmic discrimination;
Removal of algorithmic discrimination incident reporting;
Removal of risk management and impact assessments regarding algorithmic discrimination; and
Narrowing of transparency requirements and removal of disclosing bias-related information, now only “known limitations”;
Why the Change: Upon signature of the original CAIA, Governor Polis expressed reservations about its potential to “tamper innovation and deter competition.” The law faced criticism from some industry groups who argued that compliance costs would disproportionately burden small businesses lacking resources for comprehensive governance programs, while other commentators contended the law reflected ideological priorities, which was later reflected in a constitutional challenge against the law by xAI. Meanwhile, a deregulatory shift in the 2025 legislative landscape, and other states failing to enact comparable AI laws, left Colorado as an outlier.
Nonetheless, a coalition of labor, consumer, civil rights, privacy, and public interest groups continued to support the law, emphasizing the need to protect consumers when AI systems shape critical life and career decisions. After failed negotiations in 2025, Polis convened a working group to develop revisions balancing consumer protection with reduced compliance burdens.
Changes in Scope
CADMA regulates “covered automated decision-making technology” (ADMT), defined as technology that processes personal data and is used to materially influence consequential decisions. In contrast, CAIA regulated “high-risk AI systems” that were a substantial factor in, or are capable of altering, consequential decisions. Although this change was likely intended to streamline coverage, CADMA’s scope is not easily characterized as simply narrower or broader than CAIA’s. It may apply to a narrower set of technologies, but its definition of “consequential decision” may be broader and its exceptions differ from CAIA’s.
Covered Technologies: CADMA narrows the scope of covered technologies through two requirements: systems must process personal data and actually be used to “materially influence” decisions—contrasting with CAIA’s lower bar of being a “substantial factor” or merely capable of altering outcomes.
Covered Decisions / Domains: Both versions address the same domains (employment, housing, education, etc.), but CADMA may broaden coverage by: (1) lowering the impact threshold—decisions need only “relate to” a covered domain, rather than have a “material, legal, or similarly significant effect” as under CAIA; and (2) expanding decision types beyond CAIA’s “provision or denial of, or cost or terms of” to include “delay” and “alteration.” However, CADMA narrows employment coverage to hiring decisions only, whereas CAIA applied to a broader set of employment decisions.
Exemptions: CADMA does not include CAIA’s small deployer exemption. It retains most other CAIA exemptions but removes AI-enabled video games, public interest research, and entities subject to federal standards or contracts. It also narrows CAIA’s broad exemption for legal compliance and investigations to cover only anti-terrorism and money laundering activities. Notably, CADMA adds a new exemption for advertising, which CAIA would have covered under decisions regarding “access to” consequential domains.
Why the Change: The scope changes appear to reflect competing pressures. The higher technology threshold aligns with Governor Polis’s stated streamlining goals, while the broader decision definitions and fewer exemptions may reflect consumer advocates’ push to maintain protective scope. The language shifts may also reflect a change in authorship. Senator Rodriguez’s CAIA borrowed heavily from data privacy law—using “material, legal, or similarly significant effect” from the Colorado Privacy Act and including standard privacy law exemptions. CADMA’s drafting by the Governor’s office moved away from this privacy framework terminology and approach.
Narrowing employment coverage to hiring decisions also likely represents a compromise between industry and advocates–preserving protections for one of the highest-stakes employment decisions while substantially reducing the compliance footprint for ongoing employee management systems.
Streamlining Disclosures and Consumer Rights
CADMA maintains three of CAIA’s transparency requirements regarding covered systems, though in narrower form. However, it removes CAIA’s general disclosure requirement regarding any consumer-facing AI system.
Developers to Deployers: Developers must still provide information to deployers regarding the covered ADMT, though narrowed from CAIA’s “disclosures and documentation” to a general statement regarding the ADMT’s use, limitations, and monitoring.
Deployers to Consumers (Pre-Use): Deployers must still provide information to consumers prior to ADMT use, but CADMA narrows the upfront disclosure to only a statement that ADMT is being used and instructions for obtaining additional information. Details about the system’s purpose and the nature of the decision are required only when the ADMT produces an adverse outcome.
Deployers to Consumers (Post-Adverse Decision): If an adverse decision is reached pursuant to covered ADMT use, deployers must provide consumers a plain language description of the consequential decision and the role the covered ADMT played, instructions on how to request additional information, and an explanation of their rights.
Similarly, CADMA largely maintains the CAIA’s consumer rights (e.g., right to explanation, correction, and appeal) but limits them to instances of adverse decisions. Consumers must be able to request the name of the covered ADMT, the inputs used, and the categories and sources of personal information used; they must be provided the opportunity to correct any inaccurate personal data used by the covered ADMT pursuant to the Colorado Privacy Act (CPA); and they must be provided an opportunity for meaningful human review and reconsideration, to the extent commercially reasonable. Notably, deployers would only need to inform consumers of their existing rights under the CPA when an adverse decision is reached (despite the CPA not containing such limitation). Unlike the CAIA, it does not appear that deployers must respond to consumer requests in a specific time period.
Additionally, while not detailed here, CADMA includes sections regarding when notices under other laws, such as FERPA, satisfy these requirements. Developers and deployers must maintain necessary recordkeeping to demonstrate compliance for at least three years. The state AG may conduct rulemaking on the post-adverse disclosures and consumer rights.
Why the Change: The streamlined transparency requirements and consumer rights reflect Governor Polis’s goals for reduced compliance burdens for small businesses. Nonetheless, retaining these provisions, even in streamlined form, preserves two features: disclosure that enables anti-discrimination claims (discussed below) and universal application to entities of all sizes and sectors, unlike privacy laws that exempt smaller companies and government agencies through threshold requirements.
CADMA explicitly permits compliance with consent requirements through other regulatory frameworks like FERPA and FCRA, likely responding to regulated entities’ desire to integrate AI obligations into existing processes.
From Prescriptive Compliance to Discrimination Liability
The liability framework represents one of CADMA’s most fundamental departures from CAIA. CAIA established a statutory duty of care: compliance with the Act’s breadth of governance, transparency, and consumer rights requirements created a rebuttable presumption that developers and deployers had fulfilled their obligations. Noncompliance exposed entities to AG enforcement, though defendants could assert an affirmative defense by demonstrating they had cured the violation and adopted a recognized risk management framework, such as NIST’s AI RMF. Courts would ultimately assess whether an entity’s conduct was “reasonable” under the duty of care—functionally applying a negligence standard. Importantly, CAIA did not displace liability under existing anti-discrimination statutes, though compliance documentation likely would have served as evidence in both CAIA enforcement actions and parallel discrimination claims.
In contrast, CADMA eliminates the duty of care framework and most governance requirements, making entities primarily liable for transparency and consumer rights violations. Noncompliance triggers AG enforcement, though entities receive a 60-day cure period before penalties attach. CADMA replaces CAIA’s algorithmic discrimination controls by clarifying that existing anti-discrimination law applies to developers and deployers of covered ADMT. However, developers may not be liable if a deployer uses their ADMT in a manner unintended by the developer. CADMA also restricts indemnification, where deployers cannot contractually shift liability to developers.
In practice, this means entities face narrower compliance obligations under CADMA with a 60-day cure opportunity before penalties. However, navigating the courts may become less predictable without prescribed controls to establish “reasonableness” or safe harbors. Additionally, the “intended use” standard for discrimination liability, alongside the indemnification prohibition, makes documentation critical: developers need clear specifications about proper deployment, while deployers must demonstrate they followed those specifications or accept liability for misuse.
Why the Change: The shift from prescriptive controls to liability allocation reflects different regulatory philosophies: whether the state should mandate specific compliance measures or allow market-driven risk management with ex post liability. Organizations with low risk tolerance and substantial resources may prefer detailed upfront requirements that clearly define regulatory expectations and enable comprehensive compliance mapping. But resource-constrained entities with higher risk tolerance, such as startups, may prefer ambiguity: they may rather risk case-by-case adjudication than invest scarce resources in compliance with prescriptive frameworks that may not materialize into actual liability.
This tension manifests as a choice between legislative prescription and judicial development. CAIA’s approach—detailed governance requirements that created a presumption of compliance—favored entities seeking regulatory certainty. CADMA’s approach—limited transparency and general applicability of existing law with liability determined through enforcement or litigation—favors entities preferring to allocate resources to growth rather than preemptive compliance. Given Governor Polis’s emphasis on reducing burdens for startups and innovation-focused businesses, CADMA adopted the latter approach.
Conclusion
After two years of contentious debate and revision, Colorado’s AI regulation has finally reached legislative resolution. With the law scheduled to take effect before the next legislative session, entities can begin compliance planning after prolonged uncertainty. Senator Rodriguez’s retirement further marks the close of this legislative chapter. While others, such as CAIA co-sponsor Representative Brianna Titone (D), may pursue future revisions, Rodriguez’s position as both primary sponsor and Senate Majority Leader was critical to advancing the bill through contentious negotiations. Further statutory changes seem unlikely without similarly positioned leadership, though the AG’s rulemaking process may determine implementation details and enforcement approaches that could significantly affect CADMA’s real-world impact.
Colorado’s journey from comprehensive governance to an approach centered on transparency will continue to offer critical data for the debate on whether consequential algorithmic systems require specialized governance frameworks or can be adequately governed through transparency and existing law.