New FPF Report Analyzes the Rise in Chatbot Legislation & What’s Ahead
As lawmakers look to regulate how AI systems interact with minors, new report breaks down key state and federal chatbot policy developments
WASHINGTON, D.C. – The Future of Privacy Forum (FPF), a global non-profit focused on data protection, AI, and emerging technologies, today released a new report analyzing one of the most active areas of AI policymaking: chatbot regulation. The report, Regulating the Conversation: The U.S. Landscape of AI Chatbot Legislation, provides practical insight into this rapidly-evolving area of technology law and policy, including why chatbot legislation is emerging now; the core components of chatbot laws and the policy tradeoffs they raise; and the key questions likely to shape the next phase of chatbot regulation.
The report identifies two major forces behind the current wave of chatbot legislation: high-profile litigation alleging chatbot-related harms and policymakers’ desire to respond more quickly than they did to alleged harms of social media. The report examines how themes raised in recent litigation are reflected in emerging requirements in new state laws, such as age assurance, crisis response protocols, parental controls, and design restrictions. Much of this activity has focused on “companion chatbots” and youth safety, as lawmakers reflect on how to approach systems that can simulate friendship, emotional support, or other relationship-like exchanges.
The report highlights how active lawmakers have become: 37 states introduced 124 chatbot-related bills in 2026, and 18 state chatbot-specific laws are currently on the books. The report also examines two of the most recent high-profile companion chatbot bills: California’s SB 1119, recently signed into law by Governor Newsom, and New York’s S 9051, which passed the Legislature and is pending Governor Hochul’s signature.
“What makes chatbots different from other technologies, and from much of AI regulation, is their relational quality: they talk back, remember context, and can create the impression that they know the user. Such qualities draw particular attention in the context of use by children and teens, where lawmakers are trying to address potential risks while still preserving beneficial uses of conversational AI” said Justine Gluck, Policy Analyst, AI Policy and Legislation at FPF and the author of the report. “Lawmakers are increasingly focusing on the relationship that can develop between a user and a chatbot over time, not just the AI system powering it. We hope that this report will be a useful guide for policymakers, development and compliance teams, researchers, and others who are navigating this complex environment.”
The report’s key findings include:
Chatbot laws largely target the user experience, not the model, and a few key themes are emerging. Most new laws focus on disclosures, crisis protocols, and minor-specific safeguards, a departure from AI legislation aimed at how models are trained or tested.
There is significant bipartisan interest. Republican lead sponsors introduced 45 percent of chatbot bills, and Democratic sponsors introduced 55 percent.
Preemption debates remain an open question. States have moved first on chatbot regulation, but Congress has also begun introducing chatbot-specific proposals, with 10 bills introduced to date with differing approaches to the role of state law.
Emerging risks raise difficult questions and tradeoffs. Concepts such as emotional dependence, crisis detection, parental controls, and sensitive conversational data require balancing user safety with privacy, autonomy, beneficial use cases, and the practical challenges of applying broad statutory concepts to context-dependent chatbot interactions.
Older adults may be next. Lawmakers have signaled increasing interest beyond minors and companion chatbots to address other vulnerable users or sensitive contexts, such as older adults.
Chatbots offer a preview of how lawmakers may approach AI agents. As AI systems increasingly begin taking actions on a user’s behalf, such as booking services or making purchases, many chatbot regulatory concepts, including transparency and liability, could influence how lawmakers approach agentic AI.
The full report includes an overview of common requirements in enacted chatbot laws, a state and federal bill tracker, an analysis of how federal chatbot proposals would affect state regulation, and a look at emerging data protection requirements in chatbot laws and proposals. It also examines threshold questions around definitions, carveouts, and implementation as companies and regulators begin applying these requirements in practice. It builds on FPF’s extensive work on chatbot legislation, including a 2026 chatbot legislation tracker and analysis of new laws in Oregon, Washington, Colorado, California, and Connecticut.
FPF will host a webinar on October 7 from 1-2 PM EST featuring an expert panel to discuss the report and the chatbot policy landscape in more detail. Click here for more information and to register for the webinar.
For more information about the Future of Privacy Forum, visit www.fpf.org.
# # #
About Future of Privacy Forum (FPF)
FPF is a global non-profit organization that advances principled and pragmatic data protection, AI, and digital governance practices. We convene leaders across industry, academia, and the public sector to provide expert analysis, benchmarking, and best practices that support responsible innovation and regulatory compliance. FPF has offices in Washington D.C., Brussels, and Singapore. Follow FPF on X and LinkedIn.
Call for Nominations: 17th Annual Privacy Papers for Policymakers Awards
The 17th Privacy Papers for Policymakers call for submissions is now open until October 16, 2026. FPF’s Privacy Papers for Policymakers Award recognizes leading privacy research and analytical scholarship relevant to policymakers in the U.S. and internationally. The award highlights important work that analyzes current and emerging privacy issues and proposes achievable short-term solutions or means of analysis that have the potential to lead to real-world policy solutions.
FPF welcomes privacy scholars, researchers, and students to submit completed papers focusing on privacy, AI governance, or youth online and well-being, specifically emphasizing data protection, and be relevant to policymakers in this field. Submissions may include academic papers, books, empirical research, or other longer-form analyses from any region completed, accepted, or published within the last 12 months. Submissions should be submitted in English as a PDF, DOC, or DOCX, or a publicly available link, with a one-page Executive Summary or Abstract, and the author’s complete contact and affiliation information.
Submissions are evaluated by a diverse team of FPF staff, senior fellows, and other invited judges based on originality, applicability to policymaking, and overall quality of writing. Summaries of the winning papers will be published in a digest on the FPF website, and winning authors will have the opportunity to present their work during a virtual event in 2027 in front of top policymakers and privacy leaders. All winners are also highlighted during the event and in a press release to the media.
Updating the Delaware Personal Data Privacy Act: The “First State” Becomes the Latest to Get a Privacy Refresh
Delaware has become the latest state to update its comprehensive privacy law after Governor Meyer signedHB 380 on September 2, amending the Delaware Personal Data Privacy Act (DPDPA). More than half of the 23 states with comprehensive privacy laws have now amended their laws. The bill makes significant revisions to the DPDPA, including—
An expanded definition of sensitive data;
Lowered applicability thresholds;
New contractual and novel due diligence requirements for disclosing personal data to third parties;
Additional contractual requirements and rights for disclosing “reports” to third parties used in profiling decisions made about “residents,” rather than “consumers,” and extending to employee data;
Adding and modifying consumer rights; and more.
These changes will take effect January 1, 2027.
Definitions & Scope
Changes to key definitions track trends in other states. For example, HB 380 narrows the definition of “publicly available information” to exclude biometric data that was collected without the consumer’s consent. “Sensitive data” is similarly broadened to explicitly include “inferences” that reveal sensitive data categories. This bill also adds new categories of sensitive data, including national origin, medical treatment or status (in addition to diagnosis), treatment as transgender or nonbinary (in addition to “status” as such), neural data, financial account information, and government-issued identification numbers. (§ 12D-102)
This bill also lowers the law’s applicability threshold and tightens entity-level exemptions, consistent with other legislative trends from recent years. The law will now apply to any person that, in the past calendar year, controlled or processed the personal data of at least (1) 10,000 Delaware consumers (excluding data processed solely for completing payment transactions) or (2) 5,000 Delaware consumers if the person derived more than 20% of their gross revenue from the sale of personal data. These figures are down from 35,000 and 10,000 in the original law. This bill also expands the law’s scope to include “[t]hird parties who acquire personal data from a controller.” (§§ 12D-103(a), 12D-107A)
Finally, consistent with yet another legislative trend, this bill removes the law’s GLBA-entity level exemption and replaces it with several tailored exemptions for the insurance, banking, and investment industries. The bill also adds new health-related data-level exemptions, including for information in a limited data set subject to protection under 45 CFR § 164.514(e). (§ 12D-103(b)-(c))
Due Diligence for Data Sales
This bill includes new contractual requirements for disclosing personal data to third parties. The contract must specify that the personal data is disclosed only for limited and specified purposes; obligate the third party to comply with the DPDPA’s requirements; grant the controller rights to take “reasonable and appropriate steps to ensure that the third party uses the personal data . . . in a manner consistent with the controller’s obligations under [the DPDPA]”; require the third party to notify the controller if it determines that it can no longer meet its obligations under the DPDPA; and grant the controller the right, upon notice, “to take reasonable and appropriate steps to stop and remediate unauthorized use of personal data.” (§ 12D-106(a)(10))
The controller is required to conduct reasonable due diligence of third party recipients of personal data to assess the recipient’s policies and technical and organizational measures undertaken to comply with the DPDPA. This due diligence must include the use of questionnaires and review of relevant documents, and additional reasonable measures should be taken as commensurate with the sensitivity of the data disclosed. A controller is further prohibited from selling sensitive data unless the disclosure of that data is strictly necessary to provide or maintain a product or service affirmatively requested by the consumer, the controller provides clear and conspicuous notice prior to the sale, the consumer consents to the disclosure, and the controller maintains a record of consent for 5 years. These new consent records must be provided alongside data protection assessments pursuant to the AG’s investigatory powers. (§ 12D-106(a)(11)-(12))
These requirements are similar to the CCPA’s required contracts for the sale of personal information. (See Cal. Civ. Code § 1798.100, subd. (d); CCPA Rules § 7053) Delaware’s requirements may be slightly broader, however, as they apply to the “disclosure” of personal data, “including in a sale of personal data or for targeted advertising.” The more significant difference is Delaware’s novel due diligence requirements, which are not typically seen in other laws.
These new requirements also apply when the disclosure of personal data to a third party is necessary for providing a product or service requested by a consumer (which would otherwise be exempt from the definition of “sale”). (§ 12D-102)
Profiling, Reports, and Adverse Actions
In recent years, various states have introduced heightened protections and rights for consumers with respect to profiling in furtherance of decisions that produce legal or similarly significant effects concerning a consumer (“significant decisions”). Minnesota’s law, for example, includes a broad right to contest adverse profiling decisions. Connecticut’s and Vermont’s laws have a slightly narrowed version that limits aspects of the right to only decisions concerning housing.
Delaware has taken a different approach. Under the amended DPDPA, a controller will have new obligations prior to and after disclosing a report to any third party for use in connection with any significant decision concerning a resident. Key definitions:
“‘Adverse action’ means any denial, cancellation, unfavorable change, increase in charge, exclusion of benefit, or other action adverse to the interests of a consumer or resident in connection with a decision that produces legal or similarly significant effects.”
“‘Decisions that produce legal or similarly significant effects’ means decisions that result in the provision or denial of financial or lending services, housing, insurance, education enrollment or opportunity, criminal justice, employment opportunities, health-care services, or access to essential goods or services.”
“‘Report’ means any written, oral, or other communication of any personal data by a controller or processor, including recommendations, summaries, or automated decisions based on personal data or profiling.”
“‘Resident’ means any natural person residing in the State.” (§ 12D-102)
Prior to disclosing a report to a third party for use in connection with a significant decision concerning a resident, the controller must enter into a contractual agreement with the third party that imposes a number of obligations. Under this required contract, a third party must provide notice to a resident of any adverse action based in whole or in part on any information in the report; provide a description of personal data relied upon in making the adverse action; include a statement that the resident has a right to obtain certain information from the controller, with the controller’s contact information; and include a statement that the resident has a right to request the third party perform a human review of the adverse action, provided that the review must be “technically feasible” and the third party does not have to offer the review if doing so is “not in the best interest of the resident” (e.g., where delay poses a risk to the resident’s life or safety). The required contract between a controller and third party for disclosing a report is “in addition to” the bill’s other new contractual requirement for disclosing personal data to a third party. (§ 12D-106(f)(1))
Apart from entering that contract with a third party prior to disclosing a report, a controller must comply with special access and correction rights for consumers. For the access request, a controller has 30 days to provide a resident with the personal data maintained by the controller concerning the resident, the source of personal data used in profiling, and identification of all third parties who obtained a report concerning the resident in the past 24 months. The controller must also provide the resident with an opportunity to correct any incorrect personal data, although there is no timeline specified for this right. (§ 12D-106(f)(2), (3))
These new requirements apply more broadly than the rest of the law, extending to employment contexts. HB 380 narrowed the law’s data-level exemption for data processed or maintained in “the course of an individual applying to, employed by, or acting as an agent or independent contractor of a controller, processor, or third party,” providing that the exception now does not apply for personal data processed in connection with profiling and reports under these new requirements. While the definition of “consumer” exempts individuals acting in an employment context, these new controller duties apply to the disclosure of a report for use in connection with significant decisions concerning a “resident,” defined broadly as “a natural person residing in [Delaware].” (§§ 12D-102 & 12D-103(c)(11)(a))
Although these requirements are similar in kind to those under the Fair Credit Reporting Act (FCRA), HB 380 preserves the DPDPA’s existing FCRA exemption and clarifies that nothing in this new subsection applies to a controller or third party when the report or personal data consists of an output such as a score, model, or algorithm that is a consumer report—or would be a consumer report if furnished to a third party—and is furnished or disclosed in compliance with the FCRA. (§ 12D-106(g))
New & Modified Consumer Rights
This bill modifies the DPDPA’s consumer rights in several ways, all of which are similar to changes other states have previously made to their respective laws:
The right to access now explicitly includes inferences about the consumer that are derived from personal data and information about whether the consumer’s personal data is being processed for profiling to make a significant decision. The right to access is also narrowed to prohibit a controller from disclosing certain types of information to a consumer—SSNs, government-issued ID numbers, financial account numbers, health insurance and medical ID numbers, account passwords, security questions or answers, and biometric data. Rather, a controller must inform the consumer “with sufficient particularity” that the controller processes any of these types of data.
The right to know third-party recipients of one’s personal data is modified by HB 380. A consumer now has the right to obtain a list of third parties to which the controller disclosed the consumer’s personal data, not merely the categories of such third parties. However, the right no longer applies to pseudonymous data; does not require a controller to list a third party if doing so would reveal a trade secret; and the controller can provide a list of all third-party recipients of personal data rather than a list tailored to the consumer if compiling an individualized list cannot be done with “reasonable effort.”
The right to opt out of profiling is expanded to apply to profiling in furtherance of “automated decisions” that produce legal or similarly significant effects, rather than “solely automated decisions.” (§ 12D-104)
Additional Changes
This bill makes a number of additional changes to the law, including—
Requiring a controller to limit the processing of personal data to what is “reasonably necessary and proportional” in relation to the purposes for which the data is processed, as disclosed to the consumer;
For sensitive data, adding a dual requirement that processing must be pursuant to consent and must be reasonably necessary and proportionate to the disclosed processing purposes;
Adding bias-testing language to the prohibition on processing or profiling in violation of antidiscrimination law;
Expanding the teenager opt-in requirement to include profiling in addition to targeted advertising and the sale of personal data;
Adding a link for consumers to exercise their data rights to applications, not just websites;
Adding more specificity to the required controller-processor contract;
Modifying data protection assessment requirements (which only apply to controllers that process the data of at least 50,000 consumers) and adding new impact assessments for profiling that must be conducted “on a regular basis”;
Requiring that a controller or processor undertake reasonable diligence and oversight to ensure compliance with contractual commitments if that entity wants to benefit from the safe harbor from liability for violations of the DPDPA by a processor or third-party controller that received personal data from the entity; and more.
Many of these changes are similar to those Connecticut made to the CTDPA in 2025.
FPF at the Singapore Data Festival 2026: Agentic AI, Biometrics, and the Future of Digital Trust in APAC
Co-authors: Lauren Koek and Valentina Curatella, FPF APAC Interns
From July 20 to 24, 2026, the Future of Privacy Forum (FPF) participated in the inaugural Singapore Data Festival (SDF), hosted by Singapore’s Personal Data Protection Commission (PDPC) and Infocomm Media Development Authority (IMDA). Succeeding the PDPC’s annual Personal Data Protection Week, the SDF convened around 2,000 data and AI professionals, policymakers, and business leaders from all around the world.
Throughout the week, FPF convened key engagements that brought together stakeholders from industry, government, academia, and the legal sector around top-of-mind issues for the Asia-Pacific (APAC) region, including agentic and physical AI, smart wearable devices, and biometric data. This blog post takes stock of the five cross-cutting threads that emerged from FPF’s events, our invite-only Privacy Leaders’ Luncheon, our closed-door regulators’ roundtable, and contributions to the IAPP Asia Forum.
First, governance attention on AI is shifting decisively toward agentic AI, straining notice-and-consent models and pushing regulators toward objectives like accountability, safety, and meaningful human oversight. Second, AI is reshaping the breach and threat landscape, raising the stakes for security and breach notification. Third, continuous, always-on data streams from wearables and physical AI are testing the limits of existing data protection principles, especially for bystanders and biometric data. Fourth, technical and institutional capacity has become a foundational requirement for credible data protection. Fifth, scalable, interoperable cross-border data transfer mechanisms remain vital to the regional digital economy.
FPF at the Opening Session of the Singapore Data Festival, Monday, July 20, 2026.
Theme 1: Agentic AI is straining notice-and-consent models, pushing regulators towards ensuring accountability and meaningful oversight
In the last couple of years, the focus of global AI governance discourse has expanded from generative AI toward agentic AI systems capable of autonomous multi-step actions. This development has profound implications for the notice-and-consent model at the heart of most data protection regimes. As discussions across the week made clear, the shift is also pushing regulators toward frameworks organized around governance concepts such as bounding risk, retaining visibility over agent activity, and preserving human accountability.
The PDPC’s newly-issued guiding documents illustrate how some APAC regulators are beginning to address and provide clarity on data protection issues arising from the development and deployment of modern AI systems. On July 20, 2026, at the launch of the SDF, the PDPC published its finalized Advisory Guidelines on the Use of Personal Data in Generative AI (Advisory Guidelines). The Advisory Guidelines address how generative AI models may be trained and deployed under Singapore’s Personal Data Protection Act (PDPA).
While the guidance focuses on generative AI, it would also have a bearing on a relevant issue for agentic AI: specifically, the legal bases available for the collection and processing of personal data, and how individuals and organizations should be informed at the outset about the purpose of data collection and processing. In this regard, two points in the Advisory Guidelines are worth noting. First, the Advisory Guidelines clarify that the “Publicly Available Exception” under Singapore’s PDPA is applicable to the collection of data through web-scraping. Second, the Advisory Guidelines require explicit “AI-Specific Notifications” (rather than broad and generic language on “new product development”) where consent is sought specifically from individuals to train and develop AI models.
FPF and CrowdStrike’s “All-Regulators’ Panel on the Risks and Opportunities of Agentic AI,” Wednesday, July 22, 2026.
Yet, as agentic AI systems and generative AI systems with agentic functionalities become more common, regulators are recognizing that these enhanced capabilities can exacerbate data protection issues and complicate issues around responsibility allocation. Recognizing this trend, on Wednesday, July 22, 2026, FPF and CrowdStrike co-organized an “All-Regulators’ Panel on the Risks and Opportunities of Agentic AI,” moderated by Prof. Haksoo Ko (Seoul National University; FPF Senior Fellow; former Chairperson of South Korea’s Personal Information Protection Commission). Despite operating in vastly different legal, regulatory and political contexts, the regulators on the panel converged on the same objectives — achieving transparency, accountability, safety, and trust — even as they differed on the approach.
For instance, Lori Baker (Vice President, Data Protection and Regulatory Compliance, Dubai International Financial Centre (DIFC)) described how the DIFC aims to embed human oversight at every level of agentic AI deployment through internal policy prototyping. She flagged that greater clarity is needed around AI safety so that agentic AI systems can fend off attacks and avoid unintended behavior (such as a robot guard causing physical harm on the basis of a flawed visual inference).
Meanwhile, Jose Sutton Belarmino II (Deputy Privacy Commissioner, National Privacy Commission, Philippines) posited a principles-based approach towards regulating agentic systems, anchored in continuous transparency and explainability. He reasoned that legislative processes often lagged technological development. He also noted the practical difficulty of defining “meaningful” human intervention, arguing that human involvement should begin not simply at deployment, but when a company first decides to adopt an AI system.
Conversely, Alain Herrmann (Commissioner, National Commission for Data Protection of Luxembourg) outlined the European Union’s structured and risk-based approach under the GDPR and the EU AI Act, which categorizes systems by risk and mandates market surveillance. He acknowledged that applying this approach to agentic AI may present practical challenges for organizations, such as where organizations may have to comprehensively map out how an agentic AI system is processing personal data to ensure compliance. During the audience Q&A segment, Commissioner Herrmann also noted that while the EU rules may be more demanding, all EU jurisdictions share the foundational objective of ensuring accountability, safety, and trust in the development and use of agentic AI systems.
Denise Wong (Commissioner, PDPC Singapore; Assistant Chief Executive, IMDA) explained that Singapore pairs “hard-law” obligations under data protection law with iteratively updated “soft-law” guidance, such as IMDA’s Model AI Governance Framework for Agentic AI (launched in January 2026 and updated in May 2026). She emphasized that the combination of binding law and guidance allows Singapore to remain agile as guidelines are updated iteratively based on real industry feedback and use cases.
These regulatory currents were similarly mirrored – from an industry perspective – at FPF’s Privacy Leaders’ Luncheon (which convened senior practitioners from across the region to discuss top-of-mind issues around AI and data protection). Participants repeatedly emphasized visibility as the cornerstone of any internal AI governance program (that is, knowing how AI is being used across an organization, by whom, and for what), as teams contend with “shadow AI” (the use of AI tools within an organization without the organization’s explicit knowledge, approval or oversight) and organizational pressures to adopt AI. On human oversight, most participants concurred that automation should not dilute accountability. Agentic systems remain tools, and human users remain responsible for outcomes. The depth of human scrutiny, however, should be proportionate to the risks of specific contexts and use cases.
Theme 2: AI is changing the breach and threat landscape, raising the stakes for security and notification
The same capabilities driving agentic adoption are also lowering the requirements and cost of cyber threats, even as unintentional exposure grows when employees route personal data through “shadow AI” tools. In this regard, FPF also contributed to discussions at IAPP Asia Forum 2026, where these same pressures — expanding attack surfaces and rising breach volumes — featured across both sessions FPF participated in.
Josh Lee Kok Thong (Managing Director, FPF APAC) joined experts from McDermott Will & Schulte, Meta, and CrowdStrike for a session titled “The API Crisis: Securing Agentic AI in Asia’s Fastest Growing Threat Surface.” The panel explored how Application Programming Interfaces (APIs) have become an exposed control layer and a risky failure point through shadow APIs and inconsistent multi-cloud controls, and what concrete steps can strengthen API governance and secure AI-driven data flows.
FPF’s Josh Lee Kok Thong on the IAPP panel “The API Crisis: Securing Agentic AI in Asia’s Fastest Growing Threat Surface,” Wednesday, July 22, 2026
Concerns around attack surfaces growing faster than governance measures was also a central issue in Bilal Mohamed‘s (FPF Policy Manager for India) IAPP panel on “Navigating India’s Personal Data Breach Regime in the AI Age.” This panel discussion unpacked the breach-related requirements of India’s Digital Personal Data Protection Act, 2023 (DPDPA) against a landscape in which AI is reshaping the scale, speed, and entry points of personal data breaches, making unintentional exposure more likely.
The DPDPA, unlike most data protection regimes with risk thresholds, requires data fiduciaries (equivalent to a “data controller” under the GDPR) to notify the affected individual and India’s Data Protection Board (DPB) of every breach they become aware of, regardless of severity. The panel weighed whether such an all-encompassing duty remains fit-for-purpose as the ubiquitous use of AI potentially increases the number and volume of data breaches. This issue was also thrown into relief by significant developments elsewhere, with the EU’s proposed Digital Omnibus for the GDPR looking to extend the reporting timeline and narrow breach reporting obligations to high-risk incidents only.
In this context, it was also timely that the IMDA and PDPC released an updated Guide to Data Protection Practices for ICT Systems on the first day of SDF. The updated Guide draws on lessons from recent breaches to offer organizations a practical reference for hardening systems against the kind of high-velocity AI-driven incidents envisioned by both panels.
Bilal Mohamed on the IAPP panel “Navigating India’s Personal Data Breach Regime in the AI Age,” Wednesday, July 22, 2026.
Theme 3: Existing data protection principles largely cover biometrics, wearables, and physical AI, but bystander privacy remains unresolved
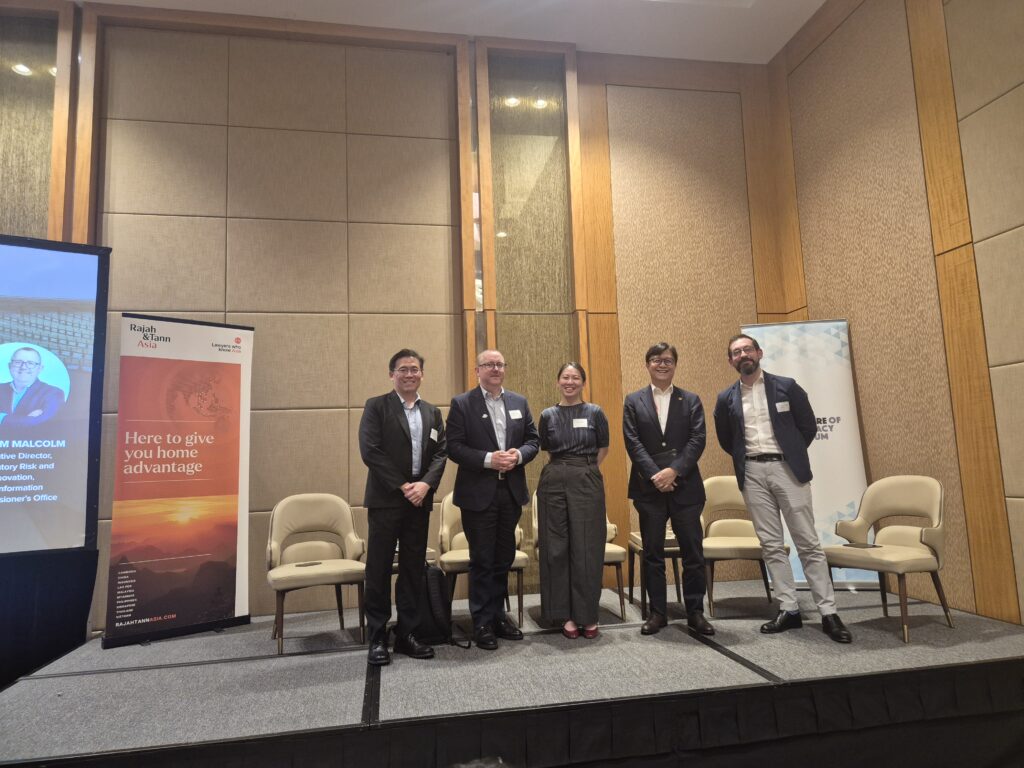
The challenges and complexities of stretching the boundaries of data protection law to cover emerging technologies carried over into discussions around wearable technologies and physical AI. On Tuesday, July 21, 2026, FPF, together with Rajah & Tann (R&T) and the Singapore Academy of Law (SAL), convened an event on “Biometric Data, Wearables and Physical AI: Frontier Legal, Regulatory and Policy Issues.” The discussion, moderated by FPF’s Deputy Director for APAC Dominic Paulger, featured Zee Kin Yeong (Chief Executive, SAL; FPF Global Senior Fellow), Steve Tan (Partner, R&T), Stephy Kwan (APAC Advocacy, Privacy and Data Policy Manager, Meta), and William Malcolm (Executive Director, Regulatory Risk and Innovation, UK Information Commissioner’s Office). The central question of this discussion was: how far can the technology-neutral principles of data protection law (most of them traceable to the Fair Information Practice Principles and the 1980 OECD Guidelines on the Protection of Privacy and Transborder Flows of Personal Data) stretch to cover devices their original drafters may never have imagined?
Speakers laid out how wearables and physical AI raise hard questions about what a system can perceive, infer, and — for embodied AI — physically do. In addition, the mode of data collection is changing from episodic to being continuous and always-on. Coupled with the fact that there may be little to no interaction between the technology and the people around it, this can leave bystanders with little notice that their personal data is being processed.
In this regard, there was a consensus among the panelists that existing principles remain broad enough to reach these technologies, although greater clarity is needed in three areas.
First, on legal bases. Wearables and physical AI demand careful consideration of the legal bases for collecting and processing personal data. In Singapore, for instance, exceptions for publicly available data and personal or domestic use may leave bystanders with little recourse, while jurisdictions without such exceptions face the opposite challenge of giving meaningful effect to bases like consent. Recording-indicator lights, an increasingly common feature on wearable devices, are only meaningful if bystanders both recognize the signal and understand what is being processed.
Second, on identifying controllers. Which players should meaningfully bear obligations and liabilities under data protection law? In particular, should the manufacturer of the device be treated as the controller, or should it be the individual who chose to switch the device on?
Third, on the treatment of biometric data. Definitions and the treatment of biometric data diverge across jurisdictions and further complicate this landscape. For instance, Article 9 of the GDPR classifies biometric data as sensitive. Consequently, controllers are subject to more stringent conditions under which biometric data can be processed. By contrast, Singapore’s PDPA does not classify certain types of data as sensitive, so protections would need to be grounded in broader reasonableness and necessity requirements.
During the panel, there was also a discussion on the pitfalls and promises of biometric technologies. Because real-world biometric systems rely on probabilistic templates, they are vulnerable to degradation and spoofing. This risk is compounded when an erroneous inference is used to trigger a physical action, such as unlocking a door or dispensing medication. Nonetheless, panelists also brought up examples of how wearable devices can be genuinely life-saving, pointing therefore towards the need for nuanced and balanced policymaking in this space.
FPF, Rajah & Tann, and the Singapore Academy of Law’s joint event on “Biometric Data, Wearables and Physical AI: Frontier Legal, Regulatory and Policy Issues,” Tuesday, July 21, 2026.
Theme 4: Technical and institutional capacity is foundational to credible data protection amidst a fast-evolving technological landscape
Underlying all of the discussions above is a more fundamental question: how can regulators in general and data protection authorities (DPAs) in particular keep pace with the relentless advance of technology, while building operational capacity and fulfilling their mandate of enforcing data protection law? On Thursday, July 23, 2026, FPF hosted “Foundations and Frontiers: A Regulators’ Roundtable on Institutional Excellence in the Asia-Pacific,” a closed-door session for experienced and emerging DPAs from across the region. In keeping with the Chatham House Rule, the takeaways below are shared without attribution to individual participants.
One key takeaway is that in building institutional capacity, DPAs can look both to adjacent fields and to adjacent stakeholders. In this regard, the first session of the roundtable addressed how regulators can develop early capabilities, allocate scarce resources, and build technical capacity without disrupting day-to-day operations. For instance, in seeking to build fresh expertise in an emerging DPA, the authority could look to recruit specialized technical skills from adjacent fields like digital forensics and IT. As specialized data protection practitioners are inherently in short supply in any emerging data protection ecosystem, experts from these adjacent fields can allow DPAs to quickly gain technical capabilities and apply regulations credibly. In addition, emerging DPAs can consider fostering robust “communities of practice” by convening DPOs and practitioners across industries to provide the DPA with valuable multi-stakeholder perspectives in refining policies and approaches.
In this context, a live and relevant example might be seen in the form of India’s emerging Data Protection Board (DPB). As the IAPP panel on India’s breach notification regime (see above) highlighted, India’s DPB is in the process of being established. It is therefore interesting to follow how the DPB will leverage expertise from various sectors and domains in India to build its capacity, while addressing what an “AI-native,” digital-by-design approach to data breach management (see Rule 20 of the DPDP Rules) might look like.
Another key takeaway is that innovation and robust data protection are in fact not mutually exclusive, and that the oft-cited trade-off between both can be navigated in several ways. In the final session of the roundtable, discussants cautioned against defaulting to the creation of rigid checklists that appear to offer easy routes to compliance but may not be as robust in dealing with rapid technological change. Instead, regulators can aim for “conditional certainty” (that is, providing companies with confidence to pursue innovation so long as certain pre-requisites are met), such as leveraging controlled environments like regulatory sandboxes to build capacity, and encouraging pre-deployment consultations with the DPA.
Theme 5: Scalable, interoperable cross-border transfer mechanisms remain vital to the regional digital economy
In a region as diverse as the APAC region, it is no surprise that there has been a proliferation of regulatory frameworks governing the transfer of data between jurisdictions. The operative focus is therefore interoperability, and it was notable how transfer tools like the ASEAN Model Contractual Clauses (MCCs) and the Global Cross-Border Privacy Rules (CBPR) system are emerging as some of the APAC region’s most practical transfer tools – including for jurisdictions with emerging DPAs. This could be seen from another session during the FPF-hosted “Foundations and Frontiers: A Regulators’ Roundtable on Institutional Excellence in the Asia-Pacific.” Discussants noted how standardized or model contractual clauses like the ASEAN MCCs could function as flexible and non-binding “plug-and-play” tools across jurisdictions, even in jurisdictions without a formal DPA. The Global CBPR system was also highlighted as a scalable mechanism that, unlike regional instruments such as the ASEAN MCCs, is open to all jurisdictions. Its accountability-agent model effectively places a certified organization under the oversight of two authorities at once, extending a DPA’s practical reach beyond its own borders.
Relevantly, at the start of SDF, FPF also published its latest Issue Brief on “Navigating Cross-Border Data Transfers in the APAC Region: An Analysis of Developments from 2023 to 2026.” The Issue Brief tracks and maps the fragmented landscape for cross-border data transfers across 14 APAC jurisdictions. A key takeaway from the Issue Brief is that there appears to be a growing duality in the APAC region: convergence on shared safeguards and accountability standards, alongside divergence in data-localization and sovereignty-driven measures.
If you want to learn more about FPF APAC and our engagements on the ground, do not hesitate to be in touch at [email protected] for membership inquiries or [email protected] for media inquiries.
Clean-Up on Aisle Three: New Jersey Becomes Third State to Regulate Data-Driven Pricing This Year
Few areas of privacy and technology policy have attracted as much legislative attention this year as data-driven pricing or “surveillance pricing.” On August 4, the Senate Judiciary Committee held a hearing—“Your Data, Their Profit: The Consumer Cost of AI Surveillance Pricing”—highlighting the intense scrutiny on these practices by policymakers. In 2026 alone, FPF tracked the introduction of over 100 bills seeking to regulate some form of data-driven pricing at the state and federal levels. Despite the shared interest, these bills vary significantly in terms of both the entities who would be in scope and the technologies and data uses that would be regulated.
Three states have enacted broad data-driven pricing laws so far this year: Maryland, Connecticut, and New Jersey. These states join New York, which passed the Algorithmic Pricing Disclosure Act last year. This blog post provides an overview of each of these three new laws, covering their key definitions, scope, obligations, and enforcement:
Scope: Maryland’s law applies only to qualifying food retailers and third-party delivery service providers. Connecticut’s prohibition extends more broadly to cover all retail sellers and third-party delivery services, with disclosure requirements for any person doing business in the state. New Jersey’s law sits in-between—prohibiting surveillance pricing by any person but only with respect to “groceries and other foodstuffs.”
Obligations: Maryland prohibits using personal data or dynamic pricing to set higher prices for covered food. Connecticut prohibits surveillance pricing, subject to exceptions, and requires disclosures when personal data is used to increase a price. New Jersey prohibits using surveillance pricing to determine or vary prices and places a one-year moratorium on the new use of electronic shelf labels.
Enforcement: Maryland and Connecticut rely on AG enforcement, while New Jersey permits broader enforcement mechanisms, including a private right of action.
Effective Dates: Maryland (October 1, 2026); Connecticut (February 1, 2027); New Jersey (August 1, 2027)
Maryland
The “Protection from Predatory Pricing Act” (HB 895) was enacted in April and regulates the use of dynamic pricing by food retailers and third-party service providers. The law takes effect on October 1, 2026. The law defines several key terms that establish its scope:
“Food retailer” means a merchant operating a business establishment with a minimum of 15,000 square feet and selling food that is exempt from Maryland’s sales and use tax [§ 11-206(c) of the Maryland tax code].
“Third-party delivery service provider” means a merchant that facilitates, as a consumer service, the delivery of food that is exempt from Maryland’s sales and use tax [§ 11-206(c) of the Maryland tax code]. This does not include a food retailer.
“Dynamic pricing” means “the discriminatory practice of offering or setting a personalized price for a good or service that is specific to a consumer based on the consumer’s personal data[as defined in MODPA], regardless of whether the seller collected or purchased the personal data.”
“Protected class data” means “information about an individual or group of individuals that, alone or in combination, directly or by implication identifies a characteristic that is legally protected from discrimination under the laws of the State or under federal law.”
Under the law, a food retailer or third-party delivery service provider may not:
Engage in dynamic pricing to set a higher price for food that is exempt from Maryland’s sales and use tax (§ 11-206(c) of the Maryland tax code);
Use personal data to set a higher price for food that is exempt from Maryland’s sales and use tax (§ 11-206(c) of the Maryland tax code) for a single consumer;
Use protected class data to “offer, advertise, or sell a consumer good or service to a consumer for whom the protected class data pertains if the use of the protected class data has the effect of withholding or denying from the consumer an accommodation, an advantage, or a privilege accorded to others.”
The law includes a number of tailored exceptions for common pricing practices. Businesses are allowed to use promotional pricing offers, loyalty program benefits, or other temporary discounts or changes to pricing related to retention of existing customers. They are also allowed to set a different price based on objective costs attributable to providing goods or services (e.g., price differences based on shipping or taxes due to the consumer’s physical location); costs or differences in supply or demand associated with providing goods or services in different locations or geographies; or costs associated with the availability or supply of the goods or services. Businesses are also allowed to offer a price to a consumer through a loyalty, membership, or rewards program in which any consumer may voluntarily enroll or consent to participate, offer prices in connection with a subscription-based contract or agreement, and offer prices to a consumer who consents (as defined in Maryland’s comprehensive privacy law) to providing personal data or other information in exchange for obtaining the price. The law also exempts correcting a price resulting from a pricing error or resetting a price following a system or network outage.
The law will be enforced by the Division of Consumer Protection of the Office of the Attorney General, who must give notice of an alleged violation prior to initiating an enforcement action and allow 45 days to cure the violation. The law includes a specific disclaimer providing that nothing should be construed to authorize a private right of action under this law or any other law.
Connecticut
Connecticut passed an omnibus privacy bill (SB 4) earlier this year that included data-driven pricing regulations. These provisions take effect on February 1, 2027.
Connecticut’s law is notably broader in scope than Maryland’s, as it applies to retail beyond food. Connecticut’s pricing law has two key provisions: it bans surveillance pricing by a retail seller or third-party delivery service, subject to exceptions; and it subjects any other person engaged in surveillance pricing to mandatory disclosures.
The law defines “surveillance pricing” as establishing a customized price for a consumer good or service that is specific to a consumer (or group of consumers) based in whole or in part on the consumer’s personal data collected (A) through any technology or technological method, system, or tool [examples given include biometric monitoring, camera, device tracking, or sensor] and (B) by the person establishing the customized price, directly or indirectly. The prohibition on surveillance pricing is narrowly targeted to retail sellers and third-party delivery services.
A “retail seller” is defined as a retailer engaged in making sales, at retail, of “tangible personal property,” which includes “digital goods.” This includes retail food establishments.
A “third-party delivery service” is defined as an entity, outside of the operation of a retail food establishment’s business, that facilitates delivery or online ordering services to customers of a retail food establishment.
The following activities do not constitute “surveillance pricing,” provided that the retail seller or third-party delivery service prominently posts the discount, discounted price, and terms and conditions in language readily understandable by the average consumer:
Establishing a discounted price for purposes such as retaining a customer, reestablishing a customer, attracting a new customer, cross-selling an item, or reengaging a lapsed customer;
Establishing different prices due to justifiable differences in costs incurred in providing the good or service (e.g., due to physical location or delivery distance) or justifiable temporal differences;
Establishing a discounted price based on publicly disclosed uniform terms and conditions available to any consumer, available to all consumers in a broadly defined group (e.g., veterans) based on publicly disclosed discounts and uniform terms and conditions, or through a loyalty, membership, or rewards program that a consumer affirmatively enrolls in; and
Correcting an erroneous price.
The law also imposes a separate disclosure requirement that applies more broadly to “any person” doing business in Connecticut who (1) engages in surveillance pricing for any reason other than to establish a discounted price for a consumer good or service as part of an online transaction, and (2) advertises or promotes online the price, labels a consumer good with the price, or publishes a statement, image, or announcement disclosing the price. Similar to what’s required under New York’s Algorithmic Pricing Disclosure Act, any such person must provide a “readily visible” disclosure: “THIS PRICE WAS INCREASED USING YOUR PERSONAL DATA.” The person must also inform consumers of their rights under Connecticut’s comprehensive privacy law. The disclosure is not required if the price is the “bona fide market price.”
Violations constitute unfair or deceptive trade practices and are enforced exclusively by the Attorney General. The law does not create a private right of action.
New Jersey
New Jersey Governor Mikie Sherrill (D) signed the “Fair Price Protection Act” (FPPA) (A4085/4523) on July 23, making New Jersey the sixth state to pass legislation regulating data-driven pricing, and the third this year. The law generally prohibits the use of “surveillance pricing” in food retail and takes effect on August 1, 2027, with certain provisions taking effect earlier.
The FPPA defines “surveillance pricing” as “an action, including a pricing strategy in which the price of groceries and other foodstuffs is, in whole or in part, determined, adjusted, optimized, or recommended by an algorithm or automated system, based, in whole or in part, on using personal data, including data derived, or inferred from other data, and that results in price variation for individual consumers or groups of consumers.” The law prohibits any “person” (as defined in state’s Consumer Fraud Act) from engaging in surveillance pricing when determining or varying the sale price of “groceries and other foodstuffs,” which includes not only food but also items such as paper products, household cleaning items, health and beauty products, and pet foods and supplies. Maryland’s law, in contrast, applies more narrowly to food exempt from sales tax. As a result, New Jersey’s FPPA likely applies more broadly than Maryland’s PPPA, to more entities, more types of products, and more pricing practices.
The FPPA prohibits surveillance pricing from being used to “determine or var[y] the sale price” of groceries or other foodstuffs. This language is broader than Maryland’s prohibition on using personal data or dynamic pricing to set higher prices, as New Jersey’s prohibition is not limited to price increases.
The FPPA also contains a narrower list of exceptions than Maryland’s law, including:
Price differences resulting from reasonable costs associated with providing groceries and other foodstuffs, as long as the price is not changed more than once in a 24-hour period;
Bona fide discounts for which eligibility conditions are public, conspicuous, and uniformly offered based on criteria, and to which members of a broadly defined group are eligible; and
Bona fide discounts offered as part of a loyalty program provided that consumers voluntarily opt in, members receive benefits pursuant to uniform terms, and the program clearly discloses its benefits, discounts, and data practices.
Any person using personal data to offer different prices on groceries or other foodstuffs pursuant to the exceptions above are prohibited from using this personal data for any other purpose without the consumer’s consent.
In addition to the prohibition on surveillance pricing, the FPPA also places a one year moratorium, beginning February 1, 2027, on the new use of electronic shelf labels in food retail stores. Before and during the moratorium, the Treasury Department’s New Jersey Innovation Authority, in consultation with the Division of Consumer Affairs, is directed to conduct a study on the use of electronic shelf labels, including legislative or regulatory recommendations, which is directed to begin immediately.
The law provides the Division of Consumer Affairs with the authority to adopt rules or regulations to effectuate any provisions, including taking any “anticipatory administrative action” as necessary to carry out their duties. For violations of the law, the state Attorney General may bring civil action on behalf of residents to enjoin violative practices, enforce compliance with the law, obtain actual monetary damages for each negligent or greater violation, or obtain any other restitution or relief deemed appropriate for each violation. Additionally, because violations of the FPPA are considered “unlawful practices” under New Jersey’s Consumer Fraud Act, the law is subject to a private right of action (“PRA”) that includes treble damages. This is the first data-driven pricing law to contain a PRA, and it is unclear how a customer’s “loss” resulting from surveillance pricing would be calculated for the purposes of assessing damages.
Algorithmic Price “Collusion” Also in Focus: The same week the FPPA was enacted, Governor Sherrill also signed the Forbidding the Algorithmic Inflation of Rent (FAIR) Act into law, which makes it an unlawful violation of the New Jersey Antitrust Act for rental property owners or their agents, or other persons, to coordinate the use of an “algorithmic device” in setting rental prices, material lease terms, or occupancy levels. It also prohibits the practice of “parallel pricing coordination,” which includes a tacit or express agreement between individuals to change pricing for residential dwelling units, unless otherwise required by law. The FAIR Act preempts local laws, provides the AG with the authority to adopt rules and enforce the law, and takes effect July 1, 2027. While FPF does not typically track algorithmic rent setting legislation, it is worth noting that this has become a major trend over the past two legislative sessions.
Conclusion
The three laws enacted this year suggest that, while regulating data-driven pricing practices remains a priority for lawmakers, they have not settled on a consistent framework. Maryland, Connecticut, and New Jersey each prohibit some form of data-driven pricing, but they have not coalesced around common scope or definitions. These laws differ in the businesses they cover, the specific practices they proscribe, and their enforcement mechanisms. For example, Maryland and New Jersey primarily regulate pricing in food retail, while Connecticut’s prohibition extends across retail more broadly. Maryland targets the use of personal data or dynamic pricing to charge higher prices, whereas Connecticut’s and New Jersey’s laws apply regardless of whether the resulting price is higher or lower.
Lawmakers will continue to debate the most effective approach to data-driven pricing through the remainder of 2026, as several bills remain pending in still-active state legislatures. For example, California’s AB 2564, which has passed the Assembly, would prohibit retailers (broadly defined) from engaging in surveillance pricing, while preserving several common pricing exceptions. Meanwhile, Michigan’s HB 6098 and HB 6099 have passed the House, and Pennsylvania lawmakers are still considering several competing approaches (HB 1779, HB 2384, and SB 1205).
The recent Senate hearing, which comes after multiple congressional investigations into companies’ surveillance pricing practices, further elevated data-driven pricing as an issue of concern for federal lawmakers, and testimony emphasized how difficult these practices can be for consumers and regulators to identify. As lawmakers look toward 2027, the growing attention to this issue may keep data-driven pricing high on legislative agendas, even as states continue to take different approaches to defining and regulating the practice.
If you are interested in an informational briefing on data-driven pricing laws and legislation, please reach out to us at [email protected].
A New Design Code Takes Root in the Garden State
On August 11, New Jersey became the newest state to enact a design code law aimed at minor online safety after Governor Sherrill signed A4015, the “New Jersey Age-Appropriate Design Code” (NJAADC). The new law is among the broadest in the country, most closely resembling a blend of the design codes enacted in South Carolina and Nebraska. For example, this law has broad applicability thresholds; relies on strong protective default settings; broadly prohibits dark patterns in online services; restricts personalized recommendation practices and certain design features; and mandates mechanisms for minors to report harms in online services. This law takes effect on September 1, 2027 and includes a private right of action (PRA). This blog post covers the NJAADC’s scope, mandatory safeguards, prohibited practices, reporting mechanisms, and enforcement.
Scope & Key Definitions
Applicability: The NJAADC regulates covered online services, defined as any entity providing an online service in the state that is both reasonably likely to be accessed by a child or minor and meets one of the following annual thresholds: (1) gross revenue in excess of $25M, or (2) processes personal data of 25,000 or more consumers or households. This definition includes any person that controls a legal entity that meets this definition and shares common branding with the legal entity. (§ 3)
While design code frameworks generally draw from the California Consumer Privacy Act (CCPA) by applying to entities that collect and control personal data and meet specified revenue or processing thresholds, the NJAADC departs from the CCPA and earlier AADC models by extending coverage beyond for-profit businesses to any legal entity that owns, operates, controls, or provides an online service and meets the statutory thresholds. Nebraska and South Carolina likewise expand scope to potentially cover non-profits and other non-commercial entities. The NJAADC has a lower data processing threshold than all other design codes—requiring processing of just 25,000 consumers or households in the state.
Exemptions: This bill includes entity-level exemptions for government entities (but only “in the ordinary course of its operation”); direct messaging services or products; telecommunications services; broadband internet access services; and email services. The bill also includes data-level exemptions for data subject to GLBA; certain health records, patient identifying information, and research data; protected health information under HIPAA; and information falling under human subjects protections by the FDA. (§§ 3 & 15)
Key Definitions: The NJAADC aligns knowledge standard definitions with other recently enacted design code laws but diverges in its approach to defining age thresholds. Similar to other laws, the NJAADC defines both actual knowledge (the threshold used to determine whether a covered online service provider knew a user was a minor) and “reasonably likely to be accessed by minors” (the standard applied to determine whether a covered online service provider is within the law’s scope). Actual knowledge is defined similarly to Nebraska’s AADC as all information and inferences the covered online service holds relating to an individual’s age—such as self-identified age or any age attributed to the individual for any purpose, including marketing, advertising, or product development. Notably, age classifications used for marketing take precedence over self-declared age. The “reasonably likely to be accessed by minors” standard is defined most comparably to Vermont’s AADC, and relies on three factors—
The service, product, or feature is directed to children, as defined by COPPA and its implementing rules;
The service, product or feature is determined, based on competent and reliable evidence regarding audience composition, to be routinely accessed by an audience that is composed of at least 2% of individuals aged 2-17; or
The covered online service knew or should have known that at least 2% of the audience includes individuals aged 2-17, provided that, in making this assessment, the business shall not collect or process any personal data that is not reasonably necessary to provide an online service, product, or feature. (§ 3)
While other design code laws typically apply protections to a single age category of minors under 18, the NJAADC adopts a two-tiered age threshold, distinguishing “child,” defined as anyone under the age of 13, from “minor,” defined as anyone between 13 and 17. A covered child or minor is one whom the covered online service has actual knowledge to be a child or minor. Although the bill creates separate “children” and “minors” definitions, none of the obligations apply differently between the two age tiers. Accordingly, this divergence likely has little practical impact on how companies implement these requirements compared to other laws as it is currently written, but future amendments could introduce opportunity for substantive divergences if scoped to only one of the two defined age categories. (§ 3)
Mandatory Safeguards
Like many recent design code laws—including those in South Carolina, Nebraska, and Vermont, the NJAADC requires covered online service providers to configure certain default safety settings for covered children and minors. These settings focus on controlling personalized content recommendations, preventing unwanted contact between minors and unknown adults, and adding friction to certain design features. These settings and features can be adjusted by a covered child/minor or their parent. Key mandatory safeguards include:
Algorithmic recommendation systems must have a “prominent and accessible” user interface allowing covered children/minors to indicate content recommendation preferences and access, review, and change personal data used to provide algorithmic recommendations. (§ 10(a) & (b))
For covered online service providers that use algorithmic recommendation systems to prioritize content or contacts between users, the systems may not display the existence of a covered child’s/minor’s account, created or posted media, or allow direct messaging between a covered child/minor and an unknown adult unless the covered child, minor, or their parent “expressly and unambiguously” allows such conduct.
Covered online service providers are prohibited from displaying a covered child’s/minor’s geolocation information or connected users;
Covered online service providers need to disable search engine indexing of covered children’s/minor’s accounts and interaction counts (e.g., comments, reactions, and reshares); and
Covered online service providers need to provide a block option preventing specific users from accessing, interacting with, or communicating with a covered child’s or minor’s account.
Covered online service providers are barred from providing a single setting that makes multiple default settings less protective, or prompting a covered child/minor to disable settings unless it is necessary to provide a service or feature “expressly and unambiguously” requested by the covered child/minor or their parent. (§ 4(a)-(c))
Prohibited Practices
In addition to requiring certain default safeguards, the NJAADC also restricts covered online services from engaging in certain practices related to children’s and minors’ personal data and service design—including through purpose limitations, compulsive design restrictions, limits on data use for algorithmic recommendations, data retention caps, notification restrictions, advertising prohibitions, and dark pattern prohibitions.
Purpose Limitation: A covered online service may not use a covered child’s/minor’s personal data for any purpose beyond that for which it was collected. There is no consent alternative for this. (§ 7(a)(1))
Compulsive Design Limits: The covered online service provider must take reasonable steps to ensure that any use of the covered child’s/minor’s personal data and design of covered design features (e.g., infinite scroll, autoplay) do not result in compulsive use. (§ 12(a))
Algorithmic Recommendation Limits: A covered online service may not use a covered child’s/minor’s personal data for content recommendations unless the prioritization is based on: user settings, a search query, parent-selected settings, a user’s age or age flag, age-appropriate content policies, or a covered child’s/minor’s “express and unambiguous” request to receive certain content. (§ 7(a)(2))
Data Minimization & Retention: The NJAADC includes substantive data minimization requirements, permitting covered online service providers to process or retain only the minimum amount of data necessary to provide the specific features of an online service with which the covered child/minor is “actively and knowingly engaged.” (§ 7 (b))
Notification Curfew: Covered online service providers must disable notifications for covered child/minor notifications by default, and, if enabled, may not send notifications during late night hours (i.e., 10pm-6am) or during the school day when school is in session (i.e., 8am-4pm). (§ 6(a) & (b))
Advertising Restrictions: Covered online service providers may not target covered children/minors with advertisements involving narcotic drugs, tobacco products, gambling, or alcohol. (§ 6(c))
“Dark Patterns” Prohibitions: Similar to other design code laws, such as Nebraska’s and South Carolina’s, covered online service providers would be broadly prohibited from using “dark patterns” in regard to a covered child/minor. While these requirements are usually tied to business data practices in other laws, like Maryland’s AADC and comprehensive privacy laws, the dark patterns prohibition under this bill is framed in context of the online service as a whole. (§ 6(d))
Reporting & Unpublishing Mechanisms
The NJAADC would require covered online service providers to establish two mechanisms for covered children/minors to use for reporting and account deletion. First, covered online service providers must provide a “prominent and accessible” reporting mechanism for covered children, minors, and their parents to report harms experienced on the online service. Second, covered online service providers must establish an “unpublishing” mechanism that allows covered children/minors to quickly delete their account in fewer steps than it took to create it. This unpublishing tool mirrors the nearly identical requirement established in the Connecticut Data Privacy Act (CTDPA) in its 2023 amendments. (§§ 5 & 9)
Enforcement & Rulemaking
The law includes robust enforcement mechanisms and rulemaking. On enforcement, the NJAADC is enforceable in two ways—first, as a violation of the Consumer Fraud Act (whichincludes a PRA). Second, the bill also establishes its own PRA through which lawsuits may be brought by either the Attorney General or a parent on behalf of an injured child or minor. For any negligent or greater violations, a court would be authorized to award:
$5k per violation or treble damages (whichever is greater);
Punitive damages for reckless and knowing violations;
Injunctive relief;
Declaratory relief;
Attorney’s fees; and
Litigation costs. (§ 14(a)-(c))
On rulemaking, the Attorney General’s office has broad authority to promulgate rules necessary to guide implementation of these provisions. Additionally, the Commissioner of Health has narrow rulemaking authority to provide guidance on criteria establishing “compulsive use.” New Jersey is the third state to provide agencies with such authority—there is ongoing rulemaking on this topic under Vermont’s AADC and Colorado already approved regulations for implementing the heightened minor protections within the Colorado Privacy Act (CPA). (§ 13)
Conclusion
New Jersey’s approach to age-appropriate design code frameworks changes the model’s formula from a data protection to safety-by design focus, distinguishing it from the regulatory approach central to earlier models. Early-enacted age-appropriate design codes, like those in California and Maryland, revolved around a duty of loyalty to act in the best interests of children, default privacy settings, child data processing restrictions, and data protection impact assessments (DPIAs) primarily evaluating whether data management practices would result in children being subject to harm. The NJAADC’s emphasis on product and service design, personalization practices, and default safeguards governing minors’ platform interactions—alongside core data protections—reflects a broader regulatory shift within U.S. age-appropriate design code frameworks toward a distinct protective-by-design approach. This shift, similarly observed in South Carolina’s law, merits consideration as an emerging framework in its own right.
As age-appropriate design codes continue to coalesce around this new protective-by-design approach, it remains to be seen whether they will continue to face the same constitutional scrutiny that the earlier privacy-by-design frameworks faced. For example, California’s and Maryland’s laws were quickly subject to constitutional challenges that are still ongoing at the time of writing. South Carolina’s law was also challenged in February 2026, and it could prove to be a bellwether for this new protective-by-design model. As states continue to experiment with legal frameworks centered on regulating platform design, continued state adoption of broad protective-by-design frameworks looks likely to continue into the 2027 legislative session.
CADA: An (E)U-turn on AI regulation
The new EU Cloud and AI Development Act (CADA) proposal marks a genuine shift in the way the bloc regulates AI, as it codifies the “AI first” principle and it is as much an “AI promotion and enabling”-type of legislation as it is a cloud sovereignty one.
The European Commission published the CADA proposal at the beginning of June 2026, as part of a broader EU Tech Sovereignty package. The legislative proposal has two general objectives: to increase the competitiveness and innovation capacity of the EU in the cloud and AI ecosystems; and to increase the resilience and strategic autonomy in cloud and AI technologies of the EU.1 This analysis focuses primarily on how CADA implements the first objective related to competitiveness and innovation. So far, this part of the proposal has received significantly less attention than the way CADA deals with the second objective on strategic autonomy through laying out cloud assurance levels for public procurement, which is set to affect the complex integrations of technology stacks. This, despite the fact that the “AI promotion” part of CADA marks a fundamental shift in the way the EU regulates AI and related technologies. The analysis also looks at where the two objectives intersect: key areas where sovereignty is imbued in the proposal’s AI promotion part.
The CADA proposal is arguably the first piece of comprehensive tech regulation introduced by the EU that provides for positive obligations to enable innovation and competitiveness, including facilitating the development and widespread adoption of AI. In doing so, it attempts to mobilize data for AI training, compute power, infrastructure, including data centers and federated cloud, EU funds, national programmatic action and all-of-government approaches to AI adoption.
In fact, reading Titles II (“Research, Development and Deployment Activities for the Cloud and AI Ecosystem”) and III (“Data Centre Capacities”) of CADA, one can draw comparisons to, and find similarities with “America’s AI Action Plan” published by the White House in 2025 and Japan’s “AI Promotion Act”. Remarkably, neither of Titles II and III of CADA virtually includes any obligation for companies among their provisions. The scarcity of obligations for companies in the AI supply chain and the onus on governments to act are foundational policies connecting the three frameworks.
CADA aims to achieve its competitiveness and innovation capacity objectives through setting up “Cloud and AI Leadership Initiatives”, with obligations for Member States and the Commission, including the creation of “Centers for AI” in each Member State and adoption of National AI Strategies. Among other measures, it pledges compute support for frontier AI priority projects, it creates a framework for the “accelerated deployment of data centers”, including a streamlined local authorization process for designated data center “acceleration zones”, and pushes to make vast amounts of data available for AI training, building up on the loosened provisions proposed in the Digital Omnibus. The proposal also aims to codify verbatim the “AI first” principle that was launched as European policy in a public speech by the President of the Commission, Ursula von der Leyen, in early October 2025, before being included in the Apply AI Strategy of the Commission.
On one hand, all of this seems at odds with the significant first iteration of AI regulation proposed by the EU – the EU AI Act – which regulates AI primarily as a risk, drawing from product safety and fundamental rights legal protections, includes “red lines” for specific uses of AI, and rules for high-risk AI systems and for general purpose AI models. Following the publication of the Draghi report, the AI Act has been criticized for being over-bureaucratic and a potential barrier to AI development, with the Commission itself proposing simplification measures through an AI Omnibus. On the other hand, these AI-enabling measures included in the CADA proposal could be effective and more easily accepted throughout the EU precisely because they are not proposed in a vacuum of AI safety rules.
Below, this blog details (1) what are the markers of an AI-enabling legislation present in the CADA proposal, lays out (2) how it aims to embed the “AI first” principle into EU law, before (3) exploring how the proposal elevates making data available for AI training as a strategic goal at EU level. It then (4) analyzes how sovereignty is imbued in the “AI promotion” part of CADA, before reaching (5) conclusions.
1.Markers of AI-enabling Legislation: AI Leadership Initiatives, Centers for AI, and Streamlined Permitting for Data Centers
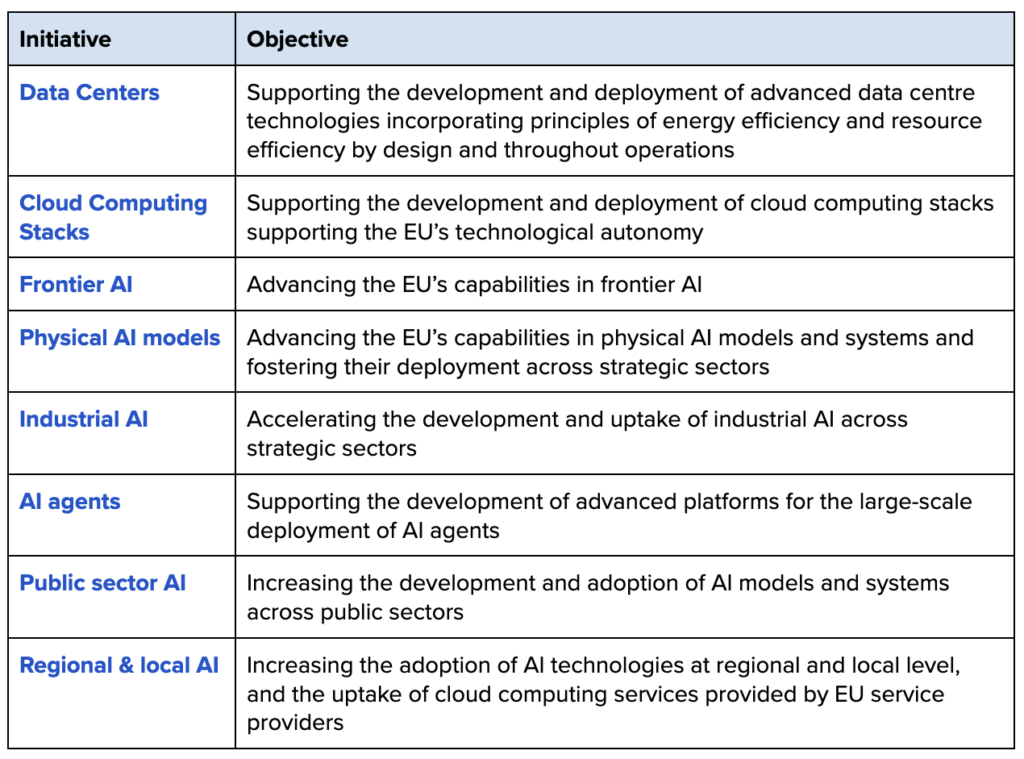
The CADA Proposal introduces “Cloud and AI Leadership Initiatives” as one of its main tenets, whose implementation is placed primarily on the European Commission and the Member States2. While the proposal does not define what the nature of these initiatives is, it establishes detailed operational objectives to be reached by them, from advancing the EU’s capabilities in frontier AI, to supporting the development of advanced platforms for the large-scale deployment of AI agents (see Table 1 below for the full list). It is notable that CADA also proposes legal definitions for both “frontier AI” and “AI agents”, filling thus a gap of the EU AI Act, which omits these two concepts. 3
Table 1. Operational objectives of the Cloud and AI Leadership Initiatives, Article 3(2) CADA
These eight operational objectives are each further dissected into multiple actions under Article 4, and each of them maps to one of the “Grand Challenges” listed in Annex I of the CADA proposal, to a large extent. These “Grand Challenges” are “the most strategic technological and industrial challenges” the Commission estimates that the EU is facing, and the CADA proposal wants to address them through large-scale, cross-sectoral initiatives.4 This is why it is important to read each of the operational objectives listed under Article 3(2) CADA together with the detailed actions under Article 4 and, further, their corresponding “grand challenge” in Annex I.
Take “physical AI models” for example. Annex I establishes that, in order to tackle Grand Challenge 4 – Physical AI, “the focus will be on co-designing software and its underlying hardware architectures and on combining frontier AI techniques with world models (our emphasis – n.) supporting physical reasoning for delivering robust manipulation, navigation, and interaction capabilities with minimal human supervision”. The Annex further notes that potential applications could include autonomous robots, industrial systems and drones operating in dynamic real-world environments. At the same time, Article 3(2)(d) CADA proposal designates “advancing Union’s capabilities in physical AI models and systems and fostering their deployment across the Union’s strategic sectors” as one of the operational objectives of the Cloud and AI Leadership Initiatives. To top it off, Article 4(4) CADA proposal further identifies specific actions to promote physical AI:
accelerate the development of a “European physical AI stack”, supporting model training and system development and deployment;
facilitate access to, and the collection and preparation of specific datasets for physical AI;
support the development, testing and validation in real-world environments of physical AI models and systems.
Thus, “world models” make their way into EU regulation, without being defined and with a focus on accelerating their development, including through making data available for training.
Frontier AI and Agentic AI are both targeted by CADA measures as well, with obligations for Member States and the Commission to “support the development of advanced, resilient and secure platforms for the development, deployment and orchestration of advanced AI agents at scale”, while creating a framework for the Commission to designate “Frontier AI priority projects”, if certain criteria are met – including that the project must be undertaken by a “European digital infrastructure consortium” (Article 8 CADA). Such designation would be important, given that Frontier priority projects would benefit from an obligation of the Member States and the Commission “to ensure” that sufficient computing resources are available for them within the limits of available capacity, per Article 9 CADA proposal.
The “Cloud and AI leadership initiatives” are complemented by more concrete AI-enabling obligations directed at Member States. Significantly, Member States would be under an obligation “to establish national cloud and AI strategies” within a year after the entry into force of CADA, which must include a prescriptive list of provisions. Among them, the national strategies must lay out measures to accelerate the development and adoption of cloud and AI at national, regional and local levels, measures to invest in high intensity computing infrastructure such as quantum computers, and measures to support the deployment of data center capacity, per Article 7(2) of the CADA proposal.
Additionally, Member States would be under an obligation to establish “Centers for AI”, whose objectives are to support the scaling-up of AI use cases in strategic and public sectors, accelerate a broad adoption of AI technologies at regional and local levels, and to leverage relevant infrastructure to accelerate the development and fine-tuning of AI models and systems (Article 5(1) CADA proposal).
The whole Title III of the CADA proposal focuses on data center capacities and has at its core an obligation for Member States to “designate at least one data center acceleration zone within its territory”, with a deadline of six months after the entry into force of CADA. Among other benefits, such acceleration zones would enjoy streamlined permitting procedures.
All of these characteristics squarely place CADA’s Titles II and III5 alongside AI promotion and enabling frameworks, such as Japan’s AI Promotion Act of 2025, or America’s AI Action Plan of 2025. First of all, the three frameworks – even if different in nature, varying between executive policy and adopted laws – virtually lack any significant obligations placed on companies in the AI supply chain and direct specific obligations to governments and public authorities. For instance, both the AI Action Plan and the CADA Proposal promote data center permitting acceleration6, the government as lead AI adopter7, facilitating compute access for start-ups and researchers8, or making data available for AI training9. The CADA Proposal is also similar to Japan’s AI Promotion Act through multiple elements, including the mandatory national planning and strategic cycle10.
2. Codifying the “AI First Principle”
The “AI first principle” is not yet clearly defined, even as it is making its way into EU law. The notion was brought into EU policy parlance by the President of the European Commission, Ursula von der Leyen, in a speech in October 2025 at the Italian Tech Week, where she said that the future “Apply AI” Strategy of the EU is based “on a simple, yet transformative principle: AI first”. She explained that “AI first” means that whenever a company or a public office is facing a new challenge, “the first question must always be: how can AI help?”. Von der Leyen specifically pointed out the transformative role of AI in healthcare, recalling that she is a medical doctor, and marveled at the promise of AI to save lives. She added that the Commission will “promote the same AI first approach across our strategic industries, from robotics to energy”.
Indeed, when the Apply AI Strategy was published weeks later, the document made specific reference to an “AI first policy”, stating that: “the Strategy promotes a shift in how companies and public sector organizations approach problem-solving. By adopting an AI first policy, they are encouraged to integrate AI building on European solutions.” The principle, thus, was also given a sovereignty flavor.
The Strategy went on to include subsections that “outline flagship initiatives to address the main sectoral challenges and support the AI first policy approach”, each dedicated to sectors like healthcare, defense and space, or mobility, among others. At the same time, the webpage of the European Commission which hosts the Strategy describes the document as encouraging “an ‘AI first policy’ where AI is considered as a potential solution whenever organisations make strategic or policy decisions, taking into careful consideration the benefits and the risks of the technology”.
The CADA proposal includes direct references to the “AI first principle” in its provisions, paving the way for it to be codified in EU law. One of the three objectives of the AI Centers that each Member State must establish is to “accelerate the broad adoption of cloud and AI technologies at regional and local levels, notably for SMEs (small and medium enterprises – n.), SMCs (small midcaps – n.) and public sector bodies, in line with the ‘AI first’ principle”, per Article 5(2)(b) of the CADA proposal, indicating thus that the principle is applicable both to the private and public sectors.
Additionally, the national strategies for cloud and AI that each Member State must adopt under Article 7 CADA have to include “key objectives and priorities for cloud and AI adoption, in line with the ‘AI first’ principle”. Recital 32 explains that this provision is about the “AI first principle” as “defined in the Apply AI Strategy, urging organizations to reflect on their business processes, considering the needs of and opportunities offered by AI, while taking into the consideration the potential risks”.
However, as shown above, the Apply AI Strategy refers to an AI first “policy”, not “principle”, which in any case it does not clearly define. Despite this, the animus behind it is clear enough, in the sense of enthusiasm for AI development, adoption and use. The legislative process for the CADA proposal will have opportunities for further clarification. This principle seems to also be the key explaining the push of the European Commission to make more data, including personal data, available for AI development.
3. Making data available for AI training becomes a strategic policy goal at the EU level
Among the many measures pushed by the CADA proposal to promote and enable AI, one stands out as intersectional: making data available for AI training. Recital 2 of the proposal explains the logic behind it by referring to how the EU “single market for data”, as promoted by the Data Act and the Data Union Strategy, “underpins the development of AI”. The CADA proposal has specific provisions that refer to either “personal” or “non-personal data”, which means that when it refers to “data” only, this term includes both categories.
Perhaps the biggest sign that making data available for AI training becomes a strategic policy goal in the EU is the obligation for Member States to include in their compulsory national cloud and AI strategies “measures to ensure the accessibility of high quality data for AI development, notably by preventing data bottlenecks encountered by organisations” (Article 7(2)(h) of the CADA proposal).
Two of the Grand Challenges in Annex I double down on data accessibility for AI training. While Grand Challenge 8, “Public Sector AI”, focuses on “enabling data sharing and frontier model development across national public services”, Grand Challenge 6, “Cooperative European Industrial Models”, focuses on enabling collaboration at European industrial scale to develop industrial AI models by pooling data in a “confidentiality-preserving” way. Both Challenges refer to specific privacy enhancing technologies as enablers of making data available for AI, such as “federated and distributed training approaches”, “secure execution environments”, “encryption-based processing”, “access compartmentalisation”, “anonymisation and pseudonymisation techniques”, “federated learning” or “high-fidelity synthetic data generation”.
Beyond the strategic desiderata, the CADA proposal also includes specific provisions for the operational objectives of the various “cloud and AI Leadership Initiatives” that push for making data available for AI development. As such, the relevant initiative in each case shall:
“boost data availability for AI via open-source middleware platforms underpinning common European data spaces” to support the development of EU cloud computing stacks (Article 4(2)(c) CADA proposal);
“facilitate access to, and the collection and preparation of, specific datasets for physical AI”, to advance physical AI models and systems in the EU (Article 4(4)(b) CADA proposal);
“enable secure large-scale data pooling for collaborative AI training through technologies enhancing privacy and preserving confidentiality”, to accelerate the development and uptake of industrial AI, and to implement Grand Challenge 6 (Article 4(5)(c) CADA proposal);
“promote the sharing and reusing of training data and AI models across the Union’s public services” to increase the development and adoption of AI models and systems across the EU’s public sectors (Article 4(7)(c) CADA proposal); and
“facilitate secure, privacy-enhancing health data reuse for AI models and tools in healthcare”, also with the purpose of increasing AI development and adoption in the public sector (Article 4(7)(d) CADA proposal).
This multi-layered push to make data available for AI training seems to be built upon the measures included in the Digital Omnibus proposed in November 2025 by the European Commission, which, among other things, targets the amendment of the General Data Protection Regulation (GDPR) to loosen the rules for lawfully processing personal data, including sensitive data, for the purpose of AI training and operation. In this sense, the Digital Omnibus proposed an amendment establishing a new lawful ground for processing of personal data on the basis of legitimate interests “in the context of the development and operation of an AI system”, unless national law requires consent. Additionally, a new exception that allows the processing of sensitive data would be added to Article 9(2) GDPR in the context of both the development and operation of an AI system (going thus beyond training). The Digital Omnibus is still in the middle of a lengthy legislative process, with some Member States in the EU Council pushing against exactly these amendments.
4. Sovereignty is the common thread between the AI promotion and the cloud public procurement parts of the CADA proposal
The CADA proposal is the flagship initiative of the EU “Tech Sovereignty package”, making it not surprising that sovereignty is the common thread between the AI-promotion and the cloud public procurement parts of the legislative initiative. This is nonetheless worth mentioning, because as much as the EU is pushing for development and use of AI, the focus is certainly on “European AI”.
For instance, among the operational objectives of the Cloud and AI Leadership Initiatives some are explicitly focused on promoting local AI: “advancing Union’s capabilities in frontier AI” and “advancing Union’s capabilities in physical AI models and systems” (Article 3(2)(c) and (d) CADA proposal). Perhaps the clearest indicator that the measures CADA puts in place are meant to promote European AI are the criteria for designating frontier AI priority projects, which hinge on the projects being undertaken by “a European digital infrastructure consortium […] or another legal entity eligible for funding under Union law and it involves the participation of at least three Member States” (Article 8(b) CADA proposal). Such priority projects would enjoy “sufficient AI computing resources” to be made available by the EU and Member States, pursuant to obligations under Article 9 of the CADA proposal.
Promotion of European AI development is not only emphasized by the provisions above, but also through conditions placed on cloud service providers to reach assurance levels 2 to 4 that prohibit them to use the data generated by using their service “to train or fine-tune any AI system operated by a third country or a legal entity established in a third country”.11
Finally, open source solutions are specifically promotedthrough a duty of means for Member States and the EU more broadly to “encourage” public sector bodies to use open standards and components released under an open source license when building their cloud and AI stack (Article 41 CADA proposal and following, part of Title IV).
5. Conclusion
The CADA proposal with its AI promotion part was published around the same time the AI Omnibus meant to amend the AI Act was reaching its final stages of legislative approval. Once adopted, the AI Omnibus delayed compliance with its core obligations for high-risk AI systems to December 2027, at the earliest, and even into 2028 for some AI components of devices and machinery (high-risk AI systems that are safety components of products under Annex I of the AI Act).
The CADA proposal and the AI Act Omnibus seem to converge towards relaxing the AI regulatory landscape in Europe, relying on different tools: on one hand, creating an “enabling” framework, as described above, and on the other hand postponing the enforceability of the more stringent obligations for high-risk AI systems under the AI Act. Nonetheless, the risk management and AI safety philosophy of the AI Act remain relevant, even if delayed. It is conceivable the AI-promotion provisions of the CADA proposal will be easier to implement in the EU precisely because they build on an AI safety framework.
The shift in how the European Union aims to regulate AI is visible, though, and it is more akin to industrial and economic policy. Surprisingly, it seems to draw inspiration from American and Japanese AI innovation frameworks, with the difference that the EU proposes an AI-promotion framework on top of an AI safety law.
Access to data for AI development is a key layer of this new approach to AI regulation, as is the strong sovereignty impetus percolating throughout the proposal. The interplay between sovereignty requirements and data governance frameworks is a space FPF will be watching closely.
Per Article 6(1) CADA, which also states that, where necessary, “joint undertakings” or other structures capable of achieving the listed objectives can also play a role. ↩︎
Article 2(4) CADA loosely defines “frontier AI” as “AI models or AI systems built upon such models that can perform a wide variety of tasks and that approach, reach or exceed the current state of the art”. In contrast, “AI agent” is defined with more precise terminology in Article 2(5) CADA as meaning “an AI system or a coordinated set of AI systems that can perceive and act upon their environment, with a degree of autonomy, using tools as needed to achieve specific goals and adapt to changing inputs and contexts”. ↩︎
See p. 2 of the Proposal and Article 6(2) CADA. ↩︎
And, partly, even title IV, through the Chapter dedicated to the promotion of open source technology. ↩︎
CADA proposal: Articles 10-14 CADA; America’s AI Action Plan: Pillar II, “Create Streamlined Permitting…”, p. 14 – 15. ↩︎
CADA proposal: Articles 7(2)(a) – (c); 4(7) – (8); 34; America’s AI Action Plan: Pillar I, p. 10 – 11. ↩︎
CADA proposal: Articles 7(2)(e); 8 – 9; America’s AI Action Plan: Pillar I, “Encourage Open-Source and Open-Weight AI”, p. 4 – 5. ↩︎
CADA proposal: Articles 7(2)(h); 4(2)(c), 4(4)(b), 4(7)(d); America’s AI Action Plan: Pillar I, p. 8 – 9. ↩︎
CADA proposal: Article 7; Japan’s AI Promotion Act: Article 18. ↩︎
Annex II, paragraphs 2.1(f); 3.1(f); and 4.1(f), CADA proposal. ↩︎
FPF and Leading Companies Release Risk Assessment Framework and Updated Best Practices for AI in Hiring & Employment
Expert working group updates 2023 report to account for the rise of generative AI; will host a webinar on September 28 to present an overview of best practices and risk framework
WASHINGTON, D.C. – The Future of Privacy Forum (FPF), with Dayforce, LinkedIn, UKG, Workday, and Beamery – leading HR, payroll, and employment software developers – today released Updated Best Practices for AI and Workplace Assessment Technologies. The Updated Best Practices build on Best Practices published in 2023 and address today’s widespread deployment of generative AI and agentic systems that can perform multi-step workflows with varying degrees of autonomy and oversight.
The 2023 Best Practice Framework laid the foundation of responsible AI governance, focusing on non-discrimination, transparency, data security and privacy, and human oversight as the industry was looking into the future. Today, as agents and generative AI work side-by-side with humans in consequential workflows, policymakers and practitioners need to know the full AI value chain and understand a novel risk assessment framework.
Instead of treating employment use cases as categorically either low or high risk, the Best Practices recommend a range of heightened safeguards that can be scaled with respect to an AI system’s overall functionality and intended use. In practice, risk is often dependent on context and configuration. Factors that increase risk include:
Sensitivity of Data and Inferences – Systems that ingest sensitive data or make (or are capable of making) sensitive or unexpected inferences about people should be limited or subject to heightened guardrails.
Degree of Autonomy, Discretion, and Action – Systems that operate more autonomously or independently may require greater protections to ensure transparency, auditability, and meaningful human oversight.
Proximity to Decisions – Systems that directly make decisions or exist in close proximity to human decision-making should be subject to greater protections.
Nature and Significance of Impact – Systems should be evaluated in relationship to the nature or significance of the decision being made, with the most consequential decisions (e.g. termination) requiring the greatest oversight.
FPF and the working group caution that no single risk factor is determinative, and urge organizations to assess where their AI system falls along a spectrum, considering how factors combine to elevate or reduce overall risk, as well as how each dimension may carry associated legal standards and compliance considerations.
“So much has changed around the use of AI in employment and hiring in the last few years,” said Stacey Gray, Senior Director of the FPF Center for Artificial Intelligence. “The unique risks posed by agentic and generative AI systems — such as fabricated content, reduced transparency and auditability, and the capacity to act with much less human oversight — have altered the responsibilities for developers and deployers. Safeguards like red teaming, auditing, and post-deployment monitoring are no longer optional, making this an important moment to update our previous recommendations.”
The working group’s updated best practices assign responsibilities to Developers and Deployers across the risk spectrum, including:
Responsible AI governance programs that govern, map, measure, and manage risk across the system lifecycle and account separately for predictive, generative, and agentic behavior
Non-discrimination practices that direct organizations to comply with applicable anti-discrimination law and to test proactively for unintended bias
Transparency practices that divide disclosure duties between Developers and Deployers
Data security and privacy practices that safeguard personal data alongside newer exposures such as prompt injection and agentic access to connected systems.
Human oversight practices that describe a graduated set of authority levels and require humans to remain accountable for outcomes
FPF and the expert working group will host a webinar in the coming weeks to present their updated best practices and an overview of the risk assessment framework to policymakers, staff, developers, deployers, and other interested parties. The webinar, set for September 28 at 12 pm ET, is free to attend, but registration is required. For more information and to register, click here.
“The increasing use of generative AI in the workforce presents real benefits to job seekers, employees, and employers, but can also introduce new and compounding risks,” said Sheila Jambekar, SVP, Chief Privacy Officer, Associate General Counsel at Dayforce. “Implementing AI governance can be complex, but with this new risk assessment framework from FPF, policymakers and organizations should have a better way to understand and evaluate AI governance requirements and scale their application of these updated best practices accordingly.”
“As AI becomes a more integral part of how we work, organizations need clear, practical guidance for adopting these technologies responsibly,” said Sara Harrington, VP, Legal at LinkedIn. “These updated best practices help organizations deploy AI responsibly while upholding the principles of transparency, privacy, security, and human oversight.”
“Responsible AI creates trusted AI, and trust will be the catalyst for AI adoption,” said Aditya Bharadwaj, Assistant General Counsel, AI & Data Governance, UKG. “UKG has helped organizations around the world run complex workforces in highly regulated environments for nearly 50 years, and AI is the next evolution of that responsibility. When frontline workers trust AI, organizations can move faster and with more confidence to transform how works gets done – unlocking better experiences for employees, stronger outcomes for employers, and a foundation for the next generation of frontline workforce operations.”
“Workday believes responsible AI can expand opportunity for job seekers, employees, and employers, but only when people trust it,” said Barbara Cosgrove, Chief Privacy and Digital Trust Officer at Workday. “Grounded in leading frameworks such as the NIST AI Risk Management Framework and ISO/IEC 42001, these updated best practices offer employers a practical, risk-based approach to managing generative and agentic AI, while building a foundation to collaborate with policymakers on a responsible future of work.”
The Updated Best Practices are intended to serve as a holistic practitioner framework, and draw throughout on the NIST AI Risk Management Framework and related NIST guidance, ISO/IEC 42001 and 42005, relevant provisions of the EU AI Act, and emerging U.S. state frameworks, including those in California, Colorado, and Connecticut. It is designed to help Developers and Deployers meet current obligations under civil rights, employment, and privacy law while preparing for a governance environment that continues to evolve.
For more information about the Future of Privacy Forum, visit www.fpf.org.
# # #
About Future of Privacy Forum (FPF)
FPF is a global non-profit organization that advances principled and pragmatic data protection, AI and digital governance practices. We convene leaders across industry, academia, and the public sector to provide expert analysis, benchmarking, and best practices that support responsible innovation and regulatory compliance. FPF has offices in Washington D.C., Brussels, and Singapore. Follow FPF on X and LinkedIn.
The Center for Artificial Intelligence at the Future of Privacy Forum is dedicated to navigating the complex landscape of AI governance and its intersection with privacy and data protection law. Drawing on expertise from a global Leadership Council comprising industry leaders, academics, civil society, and policymakers, the Center provides sophisticated, practical policy analysis to help organizations align innovation with responsible implementation while meeting evolving regulatory requirements. Learn more about the FPF Center for AI at https://fpf.org/ai.
FPF Statement on the Senior Chatbot Protection Bill
As artificial intelligence chatbots and voice assistants become increasingly integrated into the daily support networks of older adults, baseline consumer protections and transparency measures are essential to ensure these tools foster independence and interpersonal trust rather than introduce new risks. It is encouraging to see Congress recognizing the unique intersections of privacy and data protections, consumer technology, and aging with the introduction of the bipartisan Senior Chatbot Protection Act by Senator Mark Kelly (D-AZ). Building on our ongoing Agetech research, including our consumer survey and guiding questions for policymakers, FPF welcomes efforts to develop clear guardrails to facilitate the advancement of responsible AgeTech – so older adults can benefit from AI-driven independence without sacrificing their privacy or autonomy. – Jordan Wrigley, Senior Technologist
The AI Act Implementation Timeline: What Changes Under the AI Omnibus?
The implementation timeline of the EU AI Act has been significantly modified through the recently adopted AI Omnibus, which pushes compliance with the obligations for high-risk AI systems to December 2027 (Annex III) and August 2028 (Annex I), from the initial date of 2 August 2026. Changes of the AI Act include, among others, the addition of new prohibited practices under Article 5, measures that further allow the processing of special categories of personal data for bias detection and correction in AI systems, and revises post-market monitoring requirements.
Since the AI Act’s entry into force in August 2024, several provisions have already begun to apply: the rules on prohibited AI practices and AI literacy, and the obligations for providers of general-purpose AI models. Others, especially the rules on high-risk AI systems, will take effect over the next several years.
In November 2025, the European Commission presented the AI Omnibus proposal, aiming to reduce administrative burden and provide additional time to comply with certain obligations. Following several months of negotiations, the European Parliament and the Council of the European Union reached a political agreement on the AI Omnibus in May 2026. One of their main priorities was to agree on the revised implementation timelines ahead of the AI Act’s next milestone, envisioned for 2 August 2026.
The European Parliament adopted the agreed text of the AI Omnibus on 16 June 2026, and the Council adopted it on 29 June 2026. The AI Omnibus was published in the Official Journal of the EU on 24 July 2026.
To reflect these developments, we have updated the AI Act Implementation Timeline and incorporated both the original AI Act milestones and the changes introduced by the AI Omnibus.
This accompanying blog outlines several milestones already achieved under the AI Act, such as adopted guidelines and market surveillance authorities (MSAs) appointed thus far, and provides an overview of key changes introduced by the AI Omnibus. Key takeaways include:
While several countries including Italy and Ireland have established MSAs and communicated their Single Points of Contact to the European Commission, several remaining Member States are yet to appoint national competent authorities for the supervision of certain AI systems;
One of the driving factors of the AI Omnibus was the postponement of requirements for high-risk AI systems, most of which have been delayed to 2 December 2027;
The AI Omnibus slightly amends the language of the AI literacy obligation in Article 4 AI Act, so that providers and deployers are no longer required to ensure a sufficient level of AI literacy, but rather have to support the development of AI literacy for staff and other individuals dealing with the operation and use of an AI system;
A new prohibited AI practice is introduced covering AI systems that generate child sexual abuse material (CSAM) and non-consensual intimate material;
The legal basis for processing special category data for bias detection and correction is expanded to providers and deployers of all AI systems and models, rather than applying only to high-risk AI;
The AI Omnibus significantly expands the powers of the AI Office, which will now have exclusive competence over systems built on GPAI models not only when both the system and the model are developed by the same provider, but “also where they are developed by providers that form part of the same undertaking”;
The AI Omnibus follows the competitiveness and innovation logic pursued by the European Commission by ensuring that certain exemptions, including for simplified technical documentation, will apply to SMCs in addition to SMEs and start-ups.
1. AI Act implementation has already begun: an overview of the milestones achieved so far
Although it entered into force as a whole, the application of the AI Act provisions follows a phased timeline, with different obligations becoming applicable at different points over the following years.
The first institutional deadline followed soon after the AI Act’s adoption when, by November 2024, Member States were required to identify the public authorities or bodies responsible for supervising or enforcing the EU law protecting fundamental rights, make the list publicly available, and notify it to the European Commission and other Member States. In practice, this was not a single designation event happening at the same time at EU level. National implementation proceeded at varying speeds, and the European Commission established a consolidated list of appointed fundamental rights agencies, to be updated as Member States provide or revise their information.
The next governance milestone came on 2 August 2025, when Member States were required to designate at least one MSA and at least one notifying authority. The designation and notification of these authorities did not occur simultaneously across the EU, with some Member States experiencing significant delays. The European Commission maintains a list of designated Single Points of Contact which is updated continuously as Member States submit or revise their notifications. At the time of writing, only a limited number of Member States had notified their designated Single Points of Contact. These include Cyprus, Ireland, Italy, Latvia and Lithuania, and notifications from Luxembourg, Slovenia and Spain are published subject to the final adoption of the national designation decision.
The first provisions of the AI Act became applicable on 2 February 2025. These referred to the scope and definitions, the rules on prohibited AI practices, and the AI literacy obligations. The European Commission published Guidelines soon after on prohibited AI practices under Article 5 AI Act (4 February 2025), and on the definition of an AI system(6 February 2025).
Also in February of the same year, the AI Office launched a living repository of AI literacy practices. Important to note is that the repository does not create a presumption of compliance, but rather gives an indication of how the European Commission expects organizations to approach the obligation in practice. The AI Omnibus also introduces some significant changes to the AI literacy obligation, including by foreseeing an increased role of the European Commission and Member States, as further explored in Section 2.2 below.
The next milestone came on 2 August 2025, when the rules on general-purpose AI (GPAI) models, the governance framework, confidentiality obligations, and the provisions on penalties became applicable. The implementation of the GPAI framework extended beyond the envisaged application date. Article 56(9) required that the GPAI Code of Practice be ready by 2 May 2025. Although this deadline was not met, the European Commission published the GPAI Code of Practice on 10 July 2025. Soon after, the Commission also published the Guidelines on the scope of obligations for providers of GPAI models.
On 26 September 2025, the European Commission launched a public consultation on draft guidance and a reporting template on serious AI incidents under Article 73, later than the original deadline established for August 2025. The final guidance has not yet been published and the Commission published a reporting template for serious incidents involving GPAI models with systemic risk on 4 November 2025.
On 22 May 2026, the European Commission published its first review under Article 112(1), assessing whether the lists of prohibited AI practices and high-risk AI systems should be amended. It concluded that no immediate changes to Annex III were necessary and that it was still too early to assess the operation of the prohibited AI practices due to the limited implementation time. However, it identified a potential regulatory gap for AI systems generating child sexual abuse material and non-consensual intimate content, which was later addressed by the AI Omnibus through the introduction of a new prohibited AI practice (see Section 2.1 below).
The Guidelines on Transparency of AI-generated content under Article 50 were published on 20 July 2026. While Article 50 becomes generally applicable on 2 August 2026, the AI Omnibus postpones Article 50(2) (transparency obligations for GPAI models generating synthetic content) to 2 December 2026. These are complemented by a Code of Practice on Transparency of AI-generated content. The European Commission also published draft Guidelines on the classification of high-risk AI systems on 19 May 2026, with stakeholder consultations being open until 23 July 2026.
The implementation of the AI Act also revealed some of the challenges associated with this Regulation. Delays in the development of harmonized European standards and the need for additional implementation guidance became central during the legislative process and negotiations on the AI Omnibus. These developments ultimately shaped the decision to postpone the application of certain obligations for high-risk AI systems.
2. The AI Omnibus changes the timelines initially envisaged in the AI Act beyond high-risk AI
Before diving into the specifics of the changes to the AI Act timeline, it is useful to understand what the AI Omnibus is and why it was adopted. It was originally proposed by the European Commission in November 2025 as part of its broader Digital Omnibus package, aiming to reduce certain administrative burdens and facilitate the implementation of the AI Act, as part of the broader competitiveness push of the European Commission. The current text of the AI Omnibus is the result of the compromise between the European Parliament and the Council of the European Union in the legislative process, reached in May 2026. The agreed text was adopted by the European Parliament on 16 June and by the Council on 29 June.
The AI Omnibus provides for more than the postponement of implementation deadlines. It introduces a number of amendments that apply upon its entry into force, including new provisions on the supervisory and enforcement powers of the AI Office. It amends Article 113 of the AI Act (which regards the entry into force and application) to postpone the application of certain provisions, such as those concerning the requirements for high-risk AI systems, and leaves others subject to the AI Act’s existing application timeline.
The key highlights of the timeline as proposed by the AI Omnibus are the following:
2 August 2026: the AI Act becomes generally applicable.
2 December 2026: the new prohibited AI practice introduced by the AI Omnibus and the transitional transparency obligation for certain existing AI systems under Article 50(2) become applicable.
2 August 2027: providers of GPAI models placed on the market before 2 August 2025 must comply with the AI Act. Member States must ensure that their competent authorities establish at least one AI regulatory sandbox, operational by this date. The European Commission must also publish guidelines on the classification of high-risk AI systems under Article 6 and guidance on the implementation of Articles 8(2), 9(10), and 17(3). The Commission must also adopt delegated acts specifying the high-risk AI systems concerned, the applicable requirements or obligations, the conditions of any limitation, and its scope.
2 December 2027: Chapter III, Sections 1-3 (rules on the classification of high-risk AI systems, the requirements applicable to those systems, and the obligations of providers and other operators) become applicable to high-risk AI systems referred to in Article 6(2) and Annex III (AI systems classified as high-risk under Article 6(2), such as AI systems used in employment, education, law enforcement, migration, access to essential services, and the administration of justice, as listed in Annex III).
2 August 2028: The same Chapter III rules become applicable to high-risk AI systems referred to in Article 6(1) and Annex I (AI systems classified as high-risk under Article 6(1) because they are safety components of products, or are themselves products, covered by the Union harmonization legislation listed in Annex I).
Indeed, perhaps the most impactful change introduced by the AI Omnibus is the postponement of Chapter III, Sections 1-3 AI Act, which set out the rules on the classification of high-risk AI systems, the requirements applicable to those systems, and the obligations of providers and other operators. For the high-risk AI systems referred to in Article 6(2) and Annex III, the Chapter III requirements will apply from 2 December 2027 rather than 2 August 2026. For high-risk AI systems referred to in Article 6(1) and Annex I, the same provisions will apply from 2 August 2028 rather than 2 August 2027.
The AI Omnibus also brings some changes on substance to the AI Act. While not significant changes, they further shape AI law in the EU and are a first concrete expression of the European Commission’s push for “simplification” of regulation as part of its competitiveness agenda. Below, the blog explores some of the key changes in substance:
2.1. New prohibited AI practice focused on AI-generated CSAM and non-consensual intimate material
The AI Omnibus expands the list of prohibited AI practices under Article 5 AI Act by introducing a new prohibition covering AI systems that generate child sexual abuse material (CSAM) and non-consensual intimate material. Unlike the original Article 5 prohibitions, which have applied since 2 February 2025, this new prohibition applies from 2 December 2026. This gives providers and deployers falling within its scope approximately four months from the entry into force of the AI Omnibus to comply with the prohibition.
Given that Article 96 AI Act continues to require the European Commission to develop guidelines on the prohibited AI practices referred to in Article 5, the Guidelines on prohibited AI practices published in February 2025 will likely be updated to reflect the new prohibition introduced by the AI Omnibus. To better understand the prohibited AI practices, FPF’s “Red Lines under the AI Act” blog series breaks down each prohibition, as well as their interplay with existing EU law such as the GDPR and the Digital Services Act, and is available here.
2.2. Changes to the AI literacy obligation
Article 4 AI Act originally stated that “providers and deployers of AI systems shall take measures to ensure, to their best extent, a sufficient level of AI literacy of their staff and other persons dealing with the operation and use of AI systems on their behalf” (emphasis added). The new Article 4(1) of the AI Omnibus has changed slightly the wording of this provision so that providers and deployers of AI systems “shall take measures to support the development of AI literacy…” (emphasis added). The same Article 4(1) also introduces a new sentence explaining that this obligation “does not require providers or deployers to guarantee any specific level of AI literacy of any individual.” In this way, the AI literacy requirement is seemingly presented less as a strict obligation through which providers or deployers shall ensure a sufficient, measurable level of AI literacy, and more as an obligation through which some level of AI literacy should be achieved.
Coupled with the new Article 4(2) of the AI Omnibus, which introduces a role for the Commission and Member States in issuing guidance and practical examples on how the AI literacy obligation should be fulfilled, it remains to be seen how the AI literacy requirement will be implemented in practice.
2.3. Processing of special categories of personal data for bias detection and correction
The AI Omnibus introduces a new Article 4a, which allows providers of high-risk AI systems to exceptionally process special categories of personal data where this is strictly necessary to detect and correct bias. The bias detection provision originally foreseen for high-risk AI systems in Article 10(5)(a) – (f) AI Act remains unchanged by the new Article 4a of the AI Omnibus.
Where a change can be seen is in the expansion of this provision to AI systems not classified as high-risk. Indeed Article 4a introduces a new point (2) allowing “providers and deployers of otherAI systems and models” (emphasis added) to exceptionally process special category data “to the extent that such processing is strictly necessary to ensure bias detection and correction in view of possible biases that are likely to affect the health and safety of persons, have a negative impact on fundamental rights or lead to discrimination” (new Article 4a (2)(a) AI Omnibus). While the applicable safeguards for this processing remain the same as those for high-risk AI systems, the legal basis for processing special category data is expanded to providers and deployers of all AI systems and models, including general-purpose AI models.
Interestingly, the new Article 4a of the AI Omnibus also adds a new sentence which clarifies that “This paragraph does not create any obligation to conduct such bias detection and correction”, leaving bias detection to the discretion of providers and deployers. The new Article 4a applies upon the entry into force of the AI Omnibus, and must continue to be applied alongside the GDPR and other applicable data protection rules.
2.4. New powers for the AI Office
The AI Office sees its supervisory role significantly expanded under the AI Omnibus. Recital 31 of the AI Omnibus states that clarifying the role of the AI Office is necessary in order to strengthen the governance of AI systems, and that it should have exclusive competence over systems built on GPAI models not only when both the system and the model are developed by the same provider, but “also where they are developed by providers that form part of the same undertaking” (emphasis added). The AI Omnibus amends Article 75 AI Act to this effect.
The AI Office will also act as the MSA for AI systems constituting or embedded in Very Large Online Platforms and Very Large Online Services as designated under the Digital Services Act (DSA) (see Recital 32 of the AI Omnibus). The same Recital also explicitly includes the requirement of regulatory cooperation between the AI Office and the European Commission unit responsible for DSA enforcement.
The AI Omnibus also introduces several new Commission guidance obligations. By 1 August 2027, the Commission must publish guidelines on the classification of high-risk AI systems under Article 6 and guidance on the practical implementation of Articles 8(2) (requirements for high-risk AI systems), 9(10) (risk management system) and 17(3) (quality management system). In addition, by 2 September 2027, the Commission must publish guidance on the post-market monitoring plan for high-risk AI systems. The extended timelines provide the Commission with significantly more time to publish and adopt interpretative guidelines to support the implementation of the AI act.
2.5. Sandboxes and other “competitiveness” markers
In view of the European Commission’s overall competitiveness agenda, the AI Omnibus similarly aims to address and facilitate innovation. A core part of this goal is the extension of certain simplified requirements from applying only to SMEs to include small mid-cap enterprises (SMCs). The Commission defines SMCs as having fewer than 750 employees and an annual turnover not exceeding EUR 150 million (see Commission Recommendation 2025/1099 of May 2025). The introduction of a new SMC category and definition is aimed at supporting the transition of enterprises from SME to SMC, recognizing that the latter may continue to face similar regulatory burdens as the former and should therefore continue to benefit from simplified requirements.
In this context, certain AI Act exemptions applicable to SMEs will also apply to SMCs, namely:
Technical documentation for high-risk AI systems – SMCs may also use the simplified template for providing technical documentation under Annex IV AI Act (amended Article 11(1) AI Act);
Quality management systems – SMCs can also benefit from the proportionality requirement in Article 17 AI Act, by which the implementation of quality management systems should be proportionate to the size of the provider’s organization;
Priority to AI regulation sandboxes – alongside startups and SMEs (Recital 24 AI Omnibus, and amendments made to Article 57).
In addition to the role expansion foreseen for the AI Office, as explored above, the AI Omnibus also introduces a requirement for it to establish an AI regulatory sandbox at the Union level for systems based on GPAI models. The reasoning behind this change is a recognition that sandboxes act as regulatory tools to foster clarity and consistency in the governance of AI systems, and to foster innovation (see Recitals 24-26 AI Omnibus).
3. Concluding reflections
The simplification and competitiveness agenda of the European Commission has been so far translated for the AI Act into more generous timelines for compliance, support for sandboxes, easing of compliance bureaucracy for medium-sized enterprises and easing of the AI literacy obligations. It is notable that the amendment of the AI Act was swift – it took only about nine months for the EU legislative machine to convert the proposal into law. On the other hand, the amendments are a targeted intervention, given that the core obligations and legislative philosophy of the AI Act were not touched.
One visible structural shift achieved by the AI Omnibus was the enhancement of supervisory powers of the AI Office, which aligns with the European Commission’s inclination to centralize under its authority supervisory powers within the digital acquis. The supervisory structure of the DSA for VLOPS and VLOSES, as well as that of the Digital Markets Act follow the same trend.
The AI Omnibus does not change the AI Act’s phased implementation, but it provides a larger window for compliance readiness to providers of high-risk AI systems, addressing some of the AI Act’s deadlines and milestones. Beyond the rules for high-risk AI, prohibited practices under Article 5 are already in force and applicable, as are transparency requirements for GPAI model providers (Article 53) and systemic risk rules (Article 51).
As the implementation of the AI Act continues, keeping track of the changes provided by the AI Omnibus and the new guidance will be essential. For requirements regarding AI literacy in particular, ensuing Commission and Member States’ guidance will determine how the obligation will apply in practice.
The updatedFPF AI Act Implementation Timelineprovides an overview of the revised implementation timeline, key AI Omnibus amendments, and the remaining AI Act provisions that continue to apply.