Future of Privacy Forum Launches the FPF Center for Artificial Intelligence
The FPF Center for Artificial Intelligence will serve as a catalyst for AI policy and compliance leadership globally, advancing responsible data and AI practices for public and private stakeholders
Today, the Future of Privacy Forum (FPF) launched the FPF Center for Artificial Intelligence, established to better serve policymakers, companies, non-profit organizations, civil society, and academics as they navigate the challenges of AI policy and governance. The Center will expand FPF’s long-standing AI work, introduce large-scale novel research projects, and serve as a source for trusted, nuanced, nonpartisan, and practical expertise.
FPF’s Center work will be international as AI continues to deploy globally and rapidly. Cities, states, countries, and international bodies are already grappling with implementing laws and policies to manage the risks.“Data, privacy, and AI are intrinsically interconnected issues that we have been working on at FPF for more than 15 years, and we remain dedicated to collaborating across the public and private sectors to promote their ethical, responsible, and human-centered use,” saidJules Polonetsky, FPF’s Chief Executive Officer. “But we have reached a tipping point in the development of the technology that will affect future generations for decades to come. At FPF, the word Forum is a core part of our identity. We are a trusted convener positioned to build bridges between stakeholders globally, and we will continue to do so under the new Center for AI, which will sit within FPF.”
The Center will help the organization’s 220+ members navigate AI through the development of best practices, research, legislative tracking, thought leadership, and public-facing resources. It will be a trusted evidence-based source of information for policymakers, and it will collaborate with academia and civil society to amplify relevant research and resources.
“Although AI is not new, we have reached an unprecedented moment in the development of the technology that marks a true inflection point. The complexity, speed and scale of data processing that we are seeing in AI systems can be used to improve people’s lives and spur a potential leapfrogging of societal development, but with that increased capability comes associated risks to individuals and to institutions,” saidAnne J. Flanagan, Vice President for Artificial Intelligence at FPF. “The FPF Center for AI will act as a collaborative force for shared knowledge between stakeholders to support the responsible development of AI, including its fair, safe, and equitable use.”
The Center will officially launch at FPF’s inaugural summit DC Privacy Forum: AI Forward. The in-person and public-facing summit will feature high-profile representatives from the public and private sectors in the world of privacy, data and AI.
FPF’s new Center for Artificial Intelligence will be supported by a Leadership Council of leading experts from around the globe. The Council will consist of members from industry, academia, civil society, and current and former policymakers.
See the full list of founding FPF Center for AI Leadership Council members here.
I am excited about the launch of the Future of Privacy Forum’s new Center for Artificial Intelligence and honored to be part of its leadership council. This announcement builds on many years of partnership and collaboration between Workday and FPF to develop privacy best practices and advance responsible AI, which has already generated meaningful outcomes, including last year’s launch of best practices to foster trust in this technology in the workplace. I look forward to working alongside fellow members of the Council to support the Center’s mission to build trust in AI and am hopeful that together we can map a path forward to fully harness the power of this technology to unlock human potential.
Barbara Cosgrove, Vice President, Chief Privacy Officer, Workday
I’m honored to be a founding member of the Leadership Council of the Future of Privacy Forum’s new Center for Artificial Intelligence. AI’s impact transcends borders, and I’m excited to collaborate with a diverse group of experts around the world to inform companies, civil society, policymakers, and academics as they navigate the challenges and opportunities of AI governance, policy, and existing data protection regulations.
Dr. Gianclaudio Malgieri, Associate Professor of Law & Technology at eLaw, University of Leiden
“As we enter this era of AI, we must require the right balance between allowing innovation to flourish and keeping enterprises accountable for the technologies they create and put on the market. IBM believes it will be crucial that organizations such as the Future of Privacy Forum help advance responsible data and AI policies, and we are proud to join others in industry and academia as part of the Leadership Council.”
Christina Montgomery, Chief Privacy & Trust Officer, AI Ethics Board Chair, IBM
The Future of Privacy Forum (FPF) is a global non-profit organization that brings together academics, civil society, government officials, and industry to evaluate the societal, policy, and legal implications of data use, identify the risks, and develop appropriate protections.
FPF believes technology and data can benefit society and improve lives if the right laws, policies, and rules are in place. FPF has offices in Washington D.C., Brussels, Singapore, and Tel Aviv. Learn more at fpf.org.
FPF Develops Checklist & Guide to Help Schools Vet AI Tools for Legal Compliance
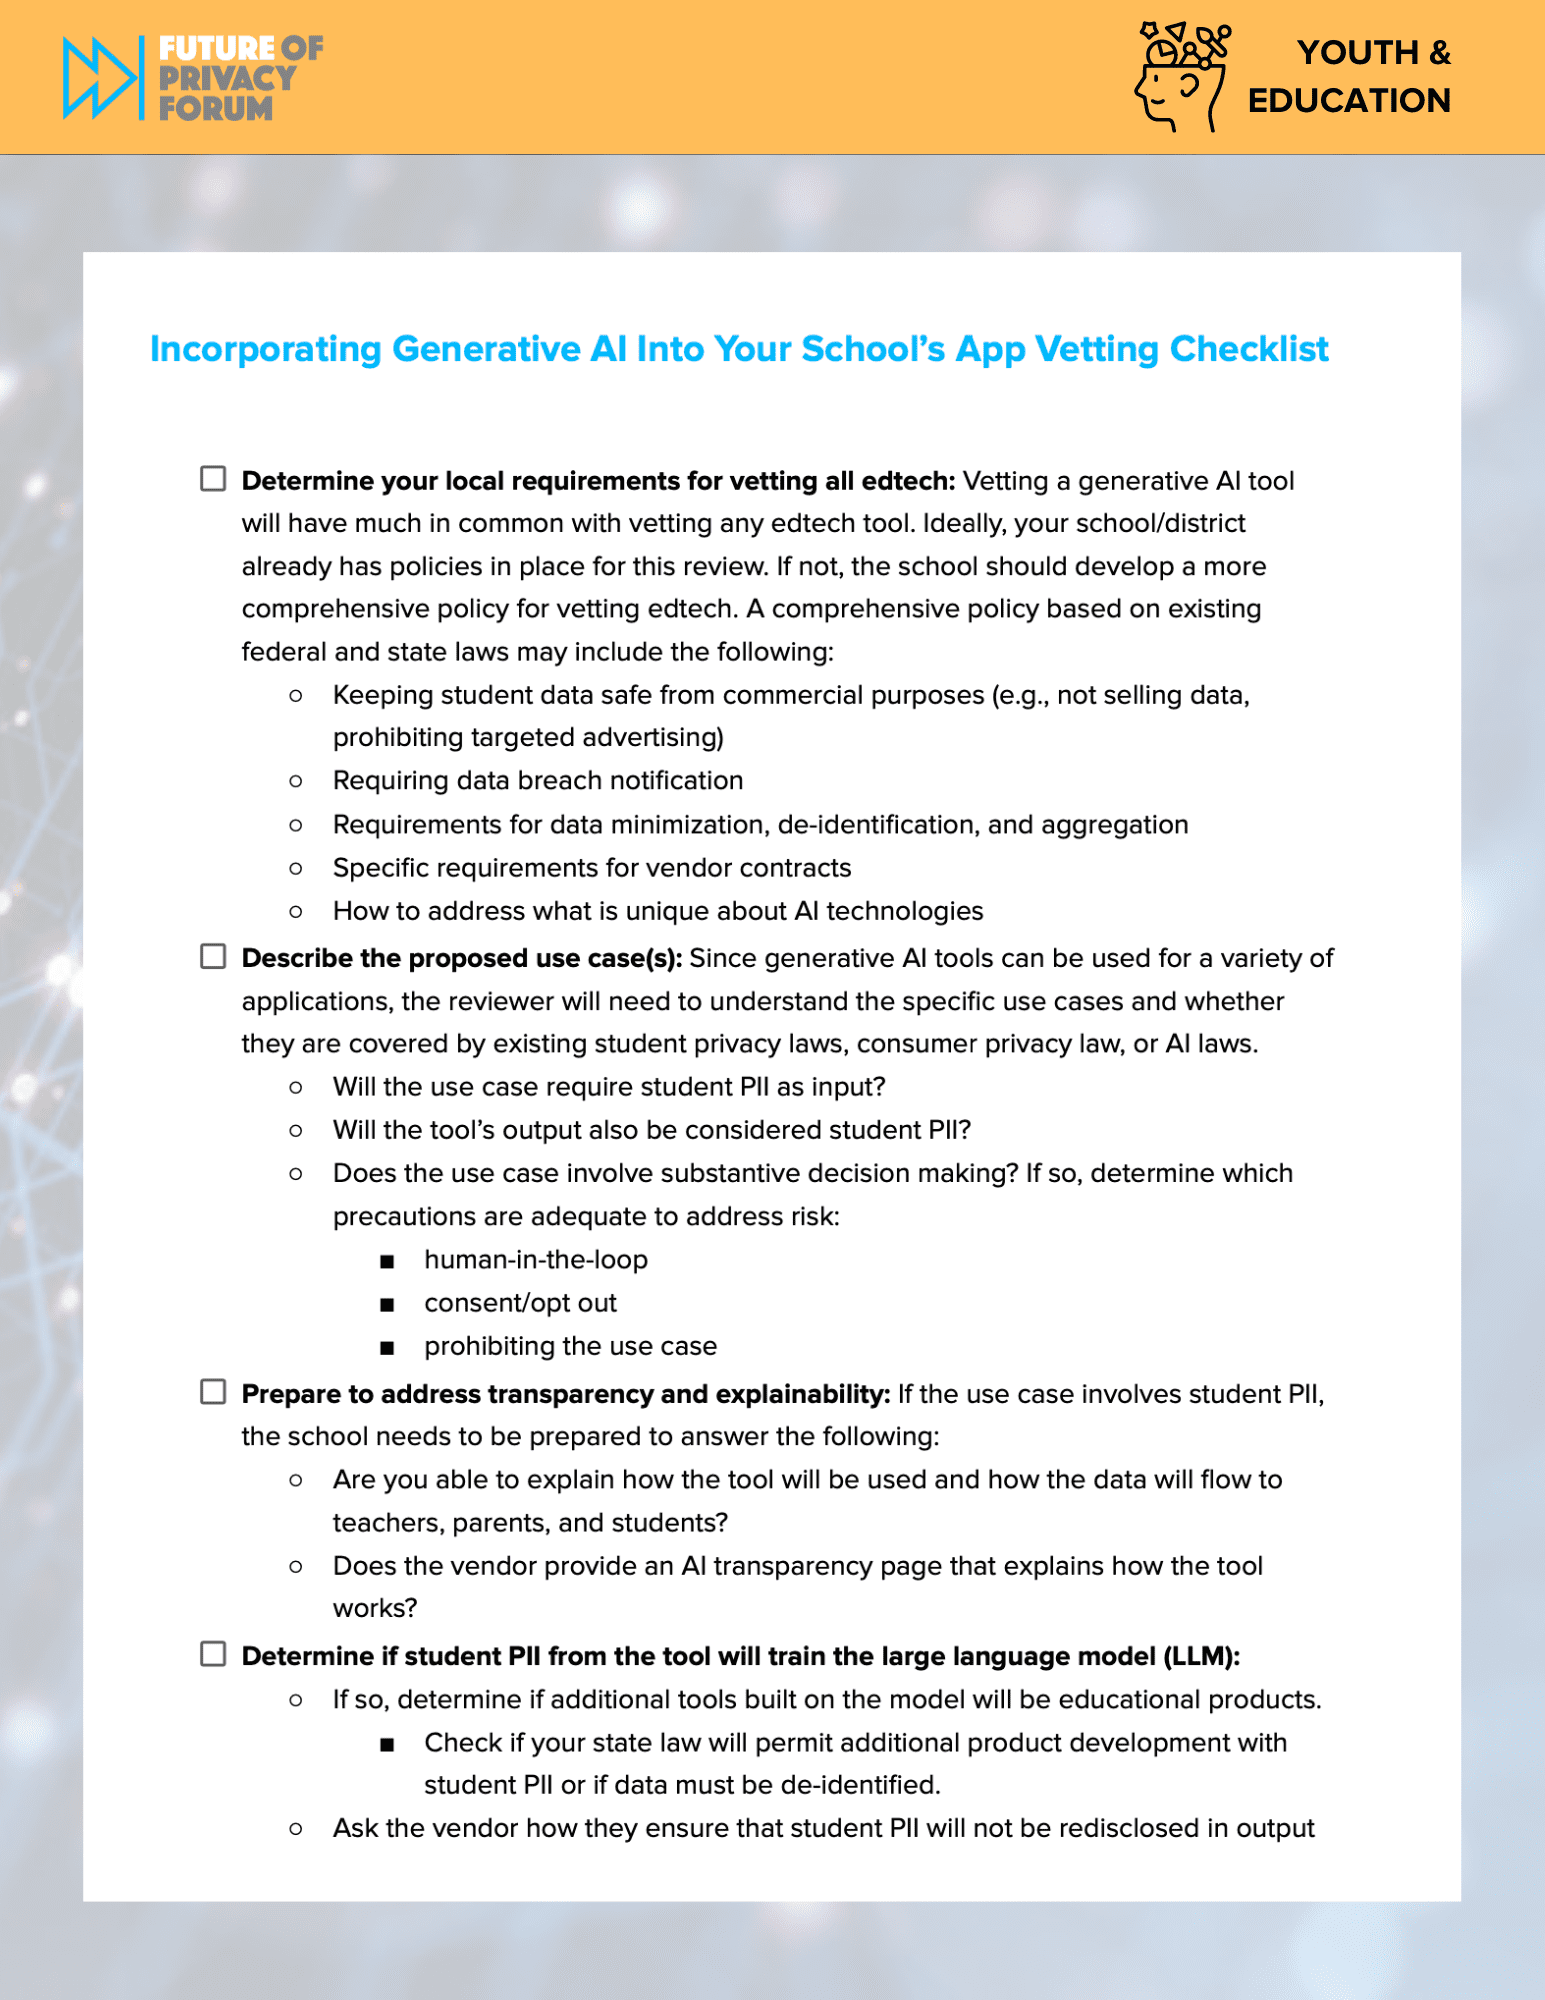
FPF’s Youth and Education team has developed a checklist and accompanying policy brief to help schools vet generative AI tools for compliance with student privacy laws. Vetting Generative AI Tools for Use in Schools is a crucial resource as the use of generative AI tools continues to increase in educational settings. It’s critical for school leaders to understand how existing federal and state student privacy laws, such as the Family Educational Rights and Privacy Act (FERPA) apply to the complexities of machine learning systems to protect student privacy. With these resources, FPF aims to provide much-needed clarity and guidance to educational institutions grappling with these issues.
“AI technology holds immense promise in enhancing educational experiences for students, but it must be implemented responsibly and ethically,” said David Sallay, the Director for Youth & Education Privacy at the Future of Privacy Forum. “With our new checklist, we aim to empower educators and administrators with the knowledge and tools necessary to make informed decisions when selecting generative AI tools for classroom use while safeguarding student privacy.”
The checklist, designed specifically for K -12 schools, outlines key considerations when incorporating generative AI into a school or district’s edtech vetting checklist.
These include:
assessing the requirements for vetting all edtech;
describing the specific use cases;
preparing to address transparency and explainability; and
determining if student PII will be used to train the large language model (LLM).
By prioritizing these steps, educational institutions can promote transparency and protect student privacy while maximizing the benefits of technology-driven learning experiences for students.
The in-depth policy brief outlines the relevant laws and policies a school should consider, the unique compliance considerations of generative AI tools (including data collection, transparency and explainability, product improvement, and high-risk decision-making), and their most likely use cases (student, teacher, and institution-focused).
The brief also encourages schools and districts to update their existing edtech vetting policies to address the unique considerations of AI technologies (or to create a comprehensive policy if one does not already exist) instead of creating a separate vetting process for AI. It also highlights the role that state legislatures can play in ensuring the efficiency of school edtech vetting and oversight and calls on vendors to be proactively transparent with schools about their use of AI.
Check out the LinkedIn Live with CEO Jules Polonetsky and Youth & Education Director David Sallay about the Checklist and Policy Brief.
To read more of the Future of Privacy Forum’s youth and student privacy resources, visitwww.StudentPrivacyCompass.org.
FPF Releases “The Playbook: Data Sharing for Research” Report and Infographic
Facilitating data sharing for research purposes between corporate data holders and academia can unlock new scientific insights and drive progress in public health, education, social science, and a myriad of other fields for the betterment of the broader society. Academic researchers use this data to consider consumer, commercial, and scientific questions at a scale they cannot reach using conventional research data-gathering techniques alone. This data also helped researchers answer questions on topics ranging from bias in targeted advertising and the influence of misinformation on election outcomes to early diagnosis of diseases through data collected by fitness and health apps.
The playbook addresses vital steps for data management, sharing, and program execution between companies and researchers. Creating a data-sharing ecosystem that positively advances scientific research requires a better understanding of the established risks, opportunities to address challenges, and the diverse stakeholders involved in data-sharing decisions. This report aims to encourage safe, responsible data-sharing between industries and researchers.
“Corporate data sharing connects companies with research institutions, by extension increasing the quantity and quality of research for social good,” said Shea Swauger, Senior Researcher for Data Sharing and Ethics. “This Playbook showcases the importance, and advantages, of having appropriate protocols in place to create safe and simple data sharing processes.”
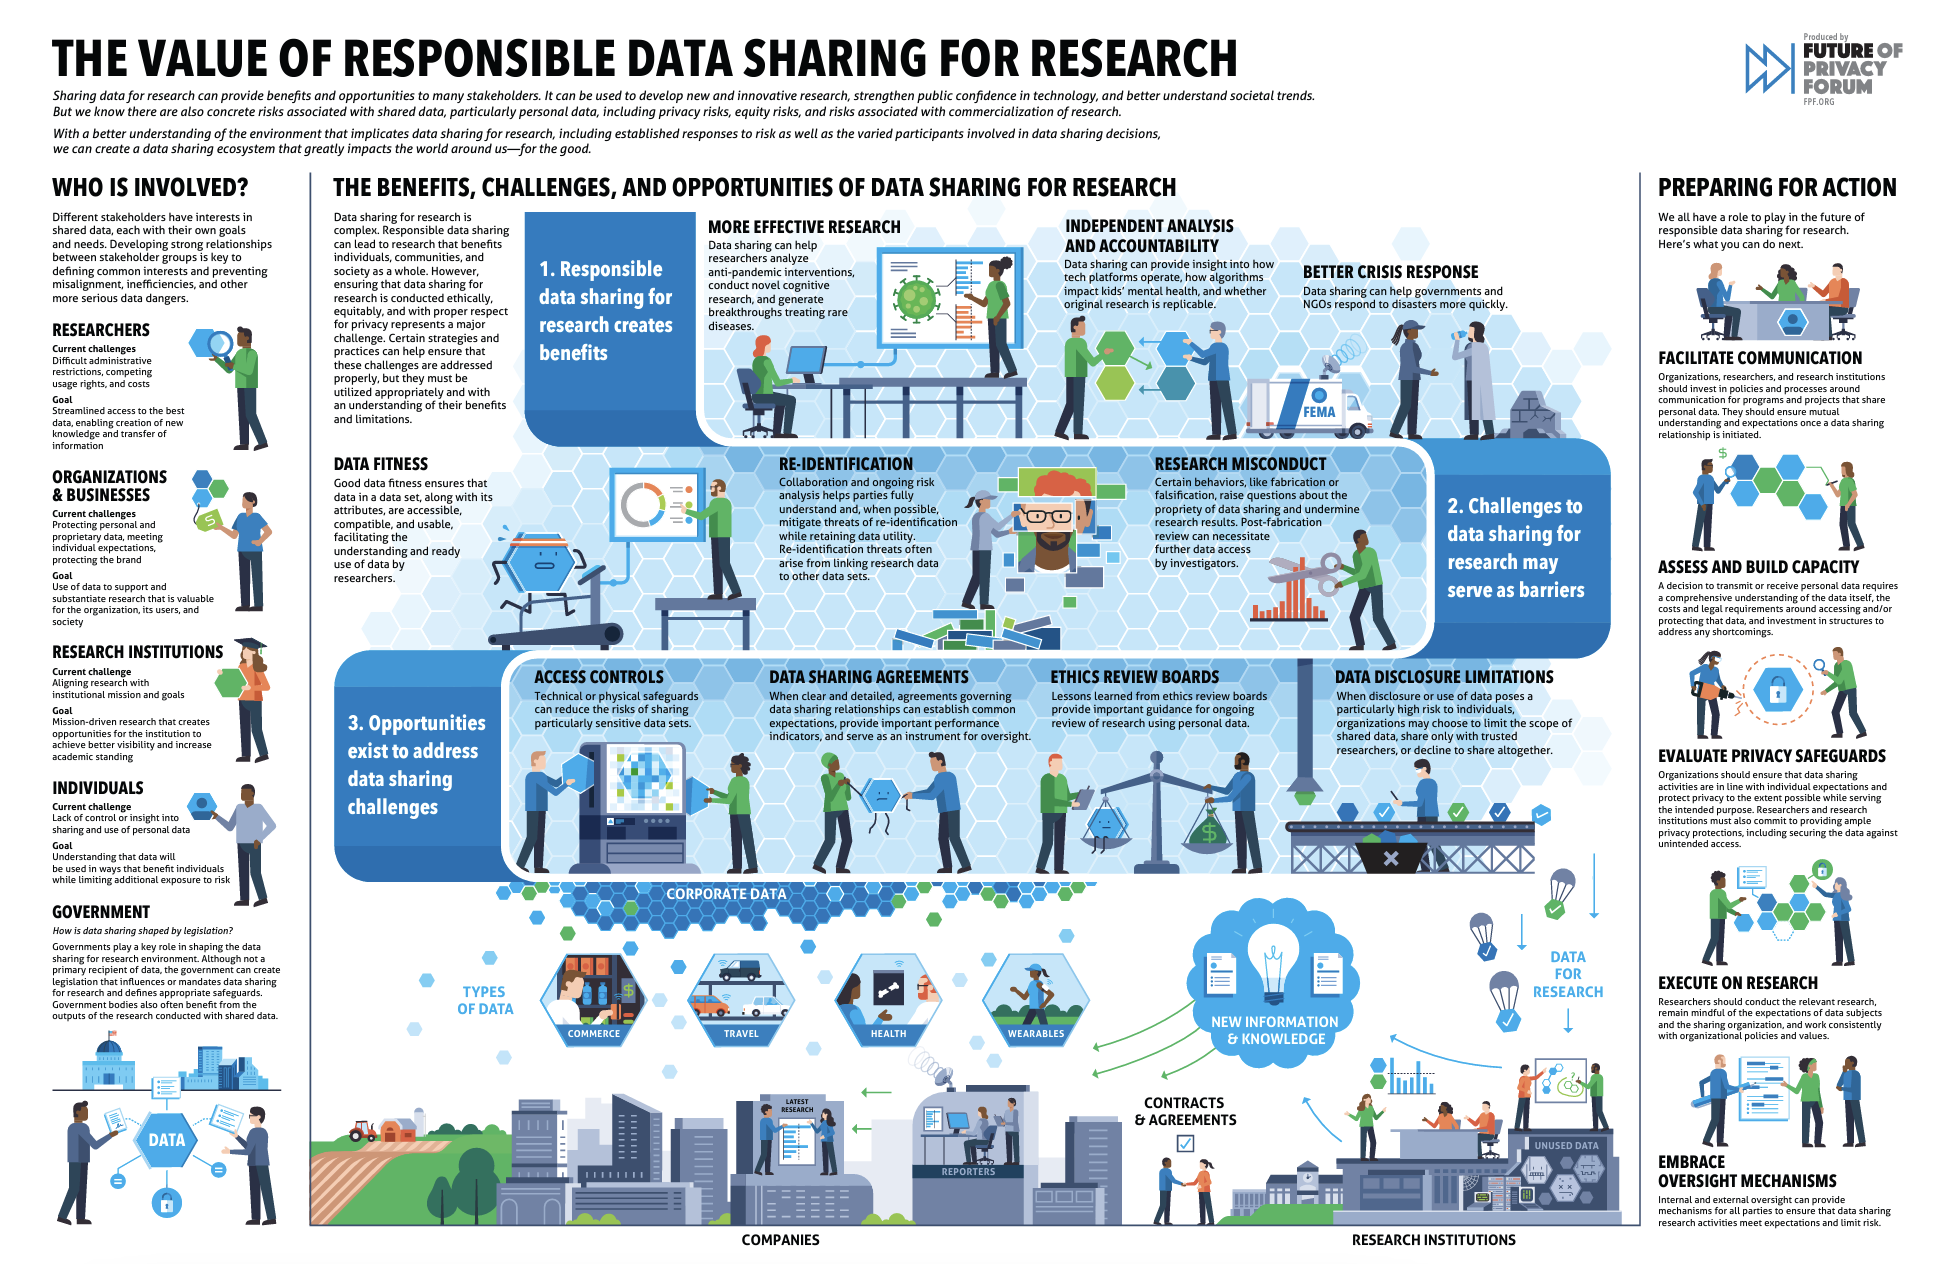
In addition to the Playbook, FPF created a companion infographic summarizing the benefits, challenges, and opportunities of data sharing for research outlined in the larger report.
As a longtime advocate for facilitating the privacy-protective sharing of data by industry to the research community, FPF is proud to have created this set of best practices for researchers, institutions, policymakers, and data-holding companies. In addition to the Playbook, the Future of Privacy Forum has also opened nominations for its annual Award for Research Data Stewardship.
“Our goal with these initiatives is to celebrate the successful research partnerships transforming how corporations and researchers interact with each other,” Swauger said. “Hopefully, we can continue to engage more audiences and encourage others to model their own programs with solid privacy safeguards.”
Shea Swauger, Senior Researcher for Data Sharing and Ethics, Future of privacy Forum
Established by FPF in 2020 with support from The Alfred P. Sloan Foundation, the Award for Research Data Stewardship recognizes excellence in the privacy-protective stewardship of corporate data shared with academic researchers. The call for nominations is open and closes on Tuesday, January 17, 2023. To submit a nomination, visit the FPF site.
FPF has also launched a newly formed Ethics and Data in Research Working Group; this group receives late-breaking analyses of emerging US legislation affecting research and data, meets to discuss the ethical and technological challenges of conducting research, and collaborates to create best practices to protect privacy, decrease risk, and increase data sharing for research, partnerships, and infrastructure. Learn more and join here.
FPF Testifies Before House Subcommittee on Energy and Commerce, Supporting Congress’s Efforts on the “American Data Privacy and Protection Act”
This week, FPF’s Senior Policy Counsel Bertram Lee testified before the U.S. House Energy and Commerce Subcommittee on Consumer Protection and Commerce hearing, “Protecting America’s Consumers: Bipartisan Legislation to Strengthen Data Privacy and Security” regarding the bipartisan, bicameral privacy discussion draft bill, “American Data Privacy and Protection Act” (ADPPA). FPF has a history of supporting the passage of a comprehensive federal consumer privacy law, which would provide businesses and consumers alike with the benefit of clear national standards and protections.
Lee’s testimony opened by applauding the Committee on its efforts towards comprehensive federal privacy legislation and emphasized the “time is now” for its passage. As it is written, the ADPPA would address gaps in the sectoral approach to consumer privacy, establish strong national civil rights protections, and establish new rights and safeguards for the protection of sensitive personal information.
“The ADPPA is more comprehensive in scope, inclusive of civil rights protections, and provides individuals with more varied enforcement mechanisms in comparison to some states’ current privacy regimes,” Lee said in his testimony. “It also includes corporate accountability mechanisms, such as the requiring privacy designations, data security offices, and executive certifications showing compliance, which is missing from current states’ laws. Notably, the ADPPA also requires ‘short-form’ privacy notices to aid consumers of how their data will be used by companies and their rights — a provision that is not found in any state law.”
Lee’s testimony also provided four recommendations to strengthen the bill, which include:
Additional funding and resources for the FTC;
Developing a more iterative process to ensure that the bill can keep up with evolving technologies;
Clarifying the intersection of ADPPA with other federal privacy laws (COPPA, FERPA, HIPAA, etc.); and
Establishing clear definitions and distinctions between different types of covered entities, including service providers.
Many of the recommendations would ensure that the legislation gives individuals meaningful privacy rights and places clear obligations on businesses and other organizations that collect, use and share personal data. The legislation would expand civil rights protections for individuals and communities harmed by algorithmic discrimination as well as require algorithmic assessments and evaluations to better understand how these technologies can impact communities.
Reading the Signs: the Political Agreement on the New Transatlantic Data Privacy Framework
The President of the United States, Joe Biden, and the President of the European Commission, Ursula von der Leyen, announced last Friday, in Brussels, a political agreement on a new Transatlantic framework to replace the Privacy Shield.
This is a significant escalation of the topic within Transatlantic affairs, compared to the 2016 announcement of a new deal to replace the Safe Harbor framework. Back then, it was Commission Vice-President Andrus Ansip and Commissioner Vera Jourova who announced at the beginning of February 2016 that a deal had been reached.
The draft adequacy decision was only published a month after the announcement, and the adequacy decision was adopted 6 months later, in July 2016. Therefore, it should not be at all surprising if another 6 months (or more!) pass before the adequacy decision for the new Framework will produce legal effects and actually be able to support transfers from the EU to the US. Especially since the US side still has to pass at least one Executive Order to provide for the agreed-upon new safeguards.
This means that transfers of personal data from the EU to the US may still be blocked in the following months – possibly without a lawful alternative to continue them – as a consequence of Data Protection Authorities (DPAs) enforcing Chapter V of the General Data Protection Regulation in the light of the Schrems II judgment of the Court of Justice of the EU, either as part of the 101 noyb complaints submitted in August 2020 and slowly starting to be solved, or as part of other individual complaints/court cases.
If you are curious about what the legal process will look like both on the US and EU sides after the agreement “in principle”, check out this blog post by Laila Abdelaziz of the “Privacy across borders project” at American University.
After the agreement “in principle” was announced at the highest possible political level, EU Justice Commissioner Didier Reynders doubled down on the point that this agreement is reached “on the principles” for a new framework, rather than on the details of it. Later on he also gave credit to Commerce Secretary Gina Raimondo and US Attorney General Merrick Garland for their hands-on involvement in working towards this agreement.
In fact, “in principle” became the leitmotif of the announcement, as the first EU Data Protection Authority to react to the announcement was the European Data Protection Supervisor, who wrote that he “Welcomes, in principle”, the announcement of a new EU-US transfers deal – “The details of the new agreement remain to be seen. However, EDPS stresses that a new framework for transatlantic data flows must be sustainable in light of requirements identified by the Court of Justice of the EU”.
Of note, there is no catchy name for the new transfers agreement, which was referred to as the “Trans-Atlantic Data Privacy Framework”. Nonetheless, FPF’s CEO Jules Polonetsky submits the “TA DA!” Agreement, and he has my vote. For his full statement on the political agreement being reached, see our release here.
Some details of the “principles” agreed on were published hours after the announcement, both by the White House and by the European Commission. Below are a couple of things that caught my attention from the two brief Factsheets.
The US has committed to “implement new safeguards” to ensure that SIGINT activities are “necessary and proportionate” (an EU law legal measure – see Article 52 of the EU Charter on how the exercise of fundamental rights can be limited) in the pursuit of defined national security objectives. Therefore, the new agreement is expected to address the lack of safeguards for government access to personal data as specifically outlined by the CJEU in the Schrems II judgment.
The US also committed to creating a “new mechanism for the EU individuals to seek redress if they believe they are unlawfully targeted by signals intelligence activities”. This new mechanism was characterized by the White House as having “independent and binding authority”. Per the White House, this redress mechanism includes “a new multi-layer redress mechanism that includes an independent Data Protection Review Court that would consist of individuals chosen from outside the US Government who would have full authority to adjudicate claims and direct remedial measures as needed”. The EU Commission mentioned in its own Factsheet that this would be a “two-tier redress system”.
Importantly, the White House mentioned in the Factsheet that oversight of intelligence activities will also be boosted – “intelligence agencies will adopt procedures to ensure effective oversight of new privacy and civil liberties standards”. Oversight and redress are different issues and are both equally important – for details, see this piece by Christopher Docksey. However, they tend to be thought of as being one and the same. Being addressed separately in this announcement is significant.
One of the remarkable things about the White House announcement is that it includes several EU law-specific concepts: “necessary and proportionate”, “privacy, data protection” mentioned separately, “legal basis” for data flows. In another nod to the European approach to data protection, the entire issue of ensuring safeguards for data flows is framed as more than a trade or commerce issue – with references to a “shared commitment to privacy, data protection, the rule of law, and our collective security as well as our mutual recognition of the importance of trans-Atlantic data flows to our respective citizens, economies, and societies”.
Last, but not least, Europeans have always framed their concerns related to surveillance and data protection as being fundamental rights concerns. The US also gives a nod to this approach, by referring a couple of times to “privacy and civil liberties” safeguards (adding thus the “civil liberties” dimension) that will be “strengthened”. All of these are positive signs for a “rapprochement” of the two legal systems and are certainly an improvement to the “commerce” focused approach of the past on the US side.
Lastly, it should also be noted that the new framework will continue to be a self-certification scheme managed by the US Department of Commerce.
What does all of this mean in practice? As the White House details, this means that the Biden Administration will have to adopt (at least) an Executive Order (EO) that includes all these commitments and on the basis of which the European Commission will draft an adequacy decision.
Thus, there are great expectations in sight following the White House and European Commission Factsheets, and the entire privacy and data protection community is waiting to see further details.
In the meantime, I’ll leave you with an observation made by my colleague, Amie Stepanovich, VP for US Policy at FPF, who highlighted that Section 702 of the FISA Act is set to expire on December 31, 2023. This presents Congress with an opportunity to act, building on such an extensive amount of work done by the US Government in the context of the Transatlantic Data Transfers debate.
Privacy Best Practices for Rideshare Drivers Using Dashcams
FPF & Uber Publish Guide Highlighting Privacy Best Practices for Drivers who Record Video and Audio on Rideshare Journeys
FPF and Uber have created a guide for US-based rideshare drivers who install “dashcams” – video cameras mounted on a vehicle’s dashboard or windshield. Many drivers install dashcams to improve safety, security, and accountability; the cameras can capture crashes or other safety-related incidents outside and inside cars. Dashcam footage can be helpful to drivers, passengers, insurance companies, and others when adjudicating legal claims. At the same time, dashcams can pose substantial privacy risks if appropriate safeguards are not in place to limit the collection, use, and disclosure of personal data.
Dashcams typically record video outside a vehicle. Many dashcams also record in-vehicle audio and some record in-vehicle video. Regardless of the particular device used, ride-hail drivers who use dashcams must comply with applicable audio and video recording laws.
The guide explains relevant laws and provides practical tips to help drivers be transparent, limit data use and sharing, retain video and audio-only for practical purposes, and use strict security controls. The guide highlights ways that drivers can employ physical signs, in-app notices, and other means to ensure passengers are informed about dashcam use and can make meaningful choices about whether to travel in a dashcam-equipped vehicle. Drivers seeking advice concerning specific legal obligations or incidents should consult legal counsel.
Privacy best practices for dashcams include:
Give individuals notice that they are being recorded
Place recording notices inside and on the vehicle.
Mount the dashcam in a visible location.
Consider, in some situations, giving an oral notification that recording is taking place.
Determine whether the ride sharing service provides recording notifications in the app, and utilize those in-app notices.
Only record audio and video for defined, reasonable purposes
Only keep recordings for as long as needed for the original purpose.
Inform passengers as to why video and/or audio is being recorded.
Limit sharing and use of recorded footage
Only share video and audio with third parties for relevant reasons that align with the original reason for recording.
Thoroughly review the rideshare service’s privacy policy and community guidelines if using an app-based rideshare service, and be aware that many rideshare companies maintain policies against widely disseminating recordings.
Safeguard and encrypt recordings and delete unused footage
Identify dashcam vendors that provide the highest privacy and security safeguards.
Carefully read the terms and conditions when buying dashcams to understand the data flows.
Uber will be making these best practices available to drivers in their app and website.
Many ride-hail drivers use dashcams in their cars, and the guidance and best practices published today provide practical guidance to help drivers implement privacy protections. But driver guidance is only one aspect of ensuring individuals’ privacy and security when traveling. Dashcam manufacturers must implement privacy-protective practices by default and provide easy-to-use privacy options. At the same time, ride-hail platforms must provide drivers with the appropriate tools to notify riders, and carmakers must safeguard drivers’ and passengers’ data collected by OEM devices.
In addition, dashcams are only one example of increasingly sophisticated sensors appearing in passenger vehicles as part of driver monitoring systems and related technologies. Further work is needed to apply comprehensive privacy safeguards to emerging technologies across the connected vehicle sector, from carmakers and rideshare services to mobility services providers and platforms. Comprehensive federal privacy legislation would be a good start. And in the absence of Congressional action, FPF is doing further work to identify key privacy risks and mitigation strategies for the broader class of driver monitoring systems that raise questions about technologies beyond the scope of this dashcam guide.
12th Annual Privacy Papers for Policymakers Awardees Explore the Nature of Privacy Rights & Harms
The winners of the 12th annual Future of Privacy (FPF) Privacy Papers for Policymakers Award ask big questions about what should be the foundational elements of data privacy and protection and who will make key decisions about the application of privacy rights. Their scholarship will inform policy discussions around the world about privacy harms, corporate responsibilities, oversight of algorithms, and biometric data, among other topics.
“Policymakers and regulators in many countries are working to advance data protection laws, often seeking in particular to combat discrimination and unfairness,” said FPF CEO Jules Polonetsky. “FPF is proud to highlight independent researchers tackling big questions about how individuals and society relate to technology and data.”
This year’s papers also explore smartphone platforms as privacy regulators, the concept of data loyalty, and global privacy regulation. The award recognizes leading privacy scholarship that is relevant to policymakers in the U.S. Congress, at U.S. federal agencies, and among international data protection authorities. The winning papers will be presented at a virtual event on February 10, 2022.
The winners of the 2022 Privacy Papers for Policymakers Award are:
Privacy Harms, by Danielle Keats Citron, University of Virginia School of Law; and Daniel J. Solove, George Washington University Law School
This paper looks at how courts define harm in cases involving privacy violations and how the requirement of proof of harm impedes the enforcement of privacy law due to the dispersed and minor effects that most privacy violations have on individuals. However, when these minor effects are suffered at a vast scale, individuals, groups, and society can feel significant harm. This paper offers language for courts to refer to when litigating privacy cases and provides advice as to when privacy harm should be considered in a lawsuit.
In this paper, Green analyzes the use of human oversight of government algorithmic decisions. From this analysis, he concludes that humans are unable to perform the desired oversight responsibilities, and that by continuing to use human oversight as a check on these algorithms, the government legitimizes the use of these faulty algorithms without addressing the associated issues. The paper offers a more stringent approach to determining whether an algorithm should be incorporated into a certain government decision, which includes critically considering the need for the algorithm and evaluating whether people are capable of effectively overseeing the algorithm.
The Surprising Virtues of Data Loyalty, by Woodrow Hartzog, Northeastern University School of Law and Khoury College of Computer Sciences, Stanford Law School Center for Internet and Society; and Neil M. Richards, Washington University School of Law, Yale Information Society Project, Stanford Center for Internet and Society
The data loyalty responsibilities for companies that process human information are now being seriously considered in both the U.S. and Europe. This paper analyzes criticisms of data loyalty that argue that such duties are unnecessary, concluding that data loyalty represents a relational approach to data that allows us to deal substantively with the problem of platforms and human information at both systemic and individual levels. The paper argues that the concept of data loyalty has some surprising virtues, including checking power and limiting systemic abuse by data collectors.
Smartphone Platforms as Privacy Regulators, by Joris van Hoboken, Vrije Universiteit Brussels, Institute for Information Law, University of Amsterdam; and Ronan Ó Fathaigh, Institute for Information Law, University of Amsterdam
In this paper, the authors look at the role of online platforms and their impact on data privacy in today’s digital economy. The paper first distinguishes the different roles that platforms can have in protecting privacy in online ecosystems, including governing access to data, design of relevant interfaces, and policing the behavior of the platform’s users. The authors then provide an argument as to what platforms’ role should be in legal frameworks. They advocate for a compromise between direct regulation of platforms and mere self-regulation, arguing that platforms should be required to make official disclosures about their privacy-related policies and practices for their respective ecosystems.
China enacted the first codified personal information protection law in China in late 2021, the Personal Information Protection Law (PIPL). In this paper, Wang compares China’s PIPL with data protection laws in nine regions to assist overseas Internet companies and personnel who deal with personal information in better understanding the similarities and differences in data protection and compliance between each country and region.
Cameras are everywhere, and with the innovation of video analytics, there are questions being raised about how individuals should be notified that they are being recorded. This paper studied 123 individuals’ sentiments across 2,328 video analytics deployments scenarios to inform their conclusion. In their conclusion, the researchers advocate for the development of interfaces that simplify the task of managing notices and configuring controls, which would allow individuals to communicate their opt-in/opt-out preference to video analytics operators.
From the record number of nominated papers submitted this year, these six papers were selected by a diverse team of academics, advocates, and industry privacy professionals from FPF’s Advisory Board. The winning papers were selected based on the research and solutions that are relevant for policymakers and regulators in the U.S. and abroad.
In addition to the winning papers, FPF has selected two papers for Honorable Mention: Verification Dilemmas and the Promise of Zero-Knowledge Proofs by Kenneth Bamberger, University of California, Berkeley – School of Law; Ran Canetti, Boston University, Department of Computer Science, Boston University, Faculty of Computing and Data Science, Boston University, Center for Reliable Information Systems and Cybersecurity; Shafi Goldwasser, University of California, Berkeley – Simons Institute for the Theory of Computing; Rebecca Wexler, University of California, Berkeley – School of Law; and Evan Zimmerman, University of California, Berkeley – School of Law; and A Taxonomy of Police Technology’s Racial Inequity Problems by Laura Moy, Georgetown University Law Center.
FPF also selected a paper for the Student Paper Award, A Fait Accompli? An Empirical Study into the Absence of Consent to Third Party Tracking in Android Apps by Konrad Kollnig and Reuben Binns, University of Oxford; Pierre Dewitte, KU Leuven; Max van Kleek, Ge Wang, Daniel Omeiza, Helena Webb, and Nigel Shadbolt, University of Oxford. The Student Paper Award Honorable Mention was awarded to Yeji Kim, University of California, Berkeley – School of Law, for her paper, Virtual Reality Data and Its Privacy Regulatory Challenges: A Call to Move Beyond Text-Based Informed Consent.
The winning authors will join FPF staff to present their work at a virtual event with policymakers from around the world, academics, and industry privacy professionals. The event will be held on February 10, 2022, from 1:00 – 3:00 PM EST. The event is free and open to the general public. To register for the event, visit https://bit.ly/3qmJdL2.
Organizations must lead with privacy and ethics when researching and implementing neurotechnology: FPF and IBM Live event and report release
A New FPF and IBM Report and Live Event Explores Questions About Transparency, Consent, Security, and Accuracy of Data
The Future of Privacy Forum (FPF) and the IBM Policy Lab released recommendations for promoting privacy and mitigating risks associated with neurotechnology, specifically with brain-computer interface (BCI). The new report provides developers and policymakers with actionable ways this technology can be implemented while protecting the privacy and rights of its users.
“We have a prime opportunity now to implement strong privacy and human rights protections as brain-computer interfaces become more widely used,” said Jeremy Greenberg, Policy Counsel at the Future of Privacy Forum. “Among other uses, these technologies have tremendous potential to treat people with diseases and conditions like epilepsy or paralysis and make it easier for people with disabilities to communicate, but these benefits can only be fully realized if meaningful privacy and ethical safeguards are in place.”
Brain-computer interfaces are computer-based systems that are capable of directly recording, processing, analyzing, or modulating human brain activity. The sensitivity of data that BCIs collect and the capabilities of the technology raise concerns over consent, as well as the transparency, security, and accuracy of the data. The report offers a number of policy and technical solutions to mitigate the risks of BCIs and highlights their positive uses.
“Emerging innovations like neurotechnology hold great promise to transform healthcare, education, transportation, and more, but they need the right guardrails in place to protect individuals’ privacy,” said IBM Chief Privacy Officer Christina Montgomery. “Working together with the Future of Privacy Forum, the IBM Policy Lab is pleased to release a new framework to help policymakers and businesses navigate the future of neurotechnology while safeguarding human rights.”
FPF and IBM have outlined several key policy recommendations to mitigate the privacy risks associated with BCIs, including:
Rethinking transparency, notice, terms of use, and consent frameworks to empower people around uses of their neurodata;
Ensuring that BCI devices are not allowed for uses to influence decisions about individuals that have legal effects, livelihood effects, or similar significant impacts—such as assessing the truthfulness of statements in legal proceedings; inferring thoughts, emotions or psychological state, or personality attributes as part of hiring or school admissions decisions; or assessing individuals’ eligibility for legal benefits;
Promoting an open and inclusive research ecosystem by encouraging the adoption of open standards for the collection and analysis of neurodata and the sharing of research data with appropriate safeguards in place.
Policymakers and other BCI stakeholders should carefully evaluate how existing policy frameworks apply to neurotechnologies and identify potential areas where existing laws and regulations may be insufficient for the unique risks of neurotechnologies.
FPF and IBM have also included several technical recommendations for BCI devices, including:
Providing hard on/off controls for users;
Allowing users to manage the collection, use, and sharing of personal neurodata on devices and in companion apps;
Offering heightened transparency and control for BCIs that send signals to the brain, rather than merely receive neurodata;
Utilizing best practices for privacy and security to store and process neurodata and use privacy enhancing technologies where appropriate; and
Encrypting sensitive personal neurodata in transit and at rest.
FPF-curated educational resources, policy & regulatory documents, academic papers, thought pieces, and technical analyses regarding brain-computer interfaces are available here.
Read FPF’s four-part series on Brain-Computer Interfaces (BCIs), providing an overview of the technology, use cases, privacy risks, and proposed recommendations for promoting privacy and mitigating risks associated with BCIs.
FPF Launches Asia-Pacific Region Office, Global Data Protection Expert Clarisse Girot Leads Team
The Future of Privacy Forum (FPF) has appointed Clarisse Girot, PhD, LLM, an expert on Asian and European privacy legislation, to lead its new FPF Asia-Pacific office based in Singapore as Director. This new office expands FPF’s international reach in Asia and complements FPF’s offices in the U.S., Europe, and Israel, as well as partnerships around the globe.
Dr. Clarisse Girot is a privacy professional with over twenty years of experience in the privacy and data protection fields. Since 2017, Clarisse has been leading the Asian Business Law Institute’s (ABLI) Data Privacy Project, focusing on the regulations on cross-border data transfers in 14 Asian jurisdictions. Prior to her time at ABLI, Clarisse served as the Counsellor to the President of the French Data Protection Authority (CNIL) and Chair of the Article 29 Working Party. She previously served as head of CNIL’s Department of European and International Affairs, where she sat on the Article 29 Working Party, the group of EU Data Protection Authorities, and was involved in major international cases in data protection and privacy.
“Clarisse is joining FPF at an important time for data protection in the Asia-Pacific region. The two most populous countries in the world, India, and China, are introducing general privacy laws, and established data protection jurisdictions, like Singapore, Japan, South Korea, and New Zealand, have recently updated their laws,” said FPF CEO Jules Polonetsky. “Her extensive knowledge of privacy law will provide vital insights for those interested in compliance with regional privacy frameworks and their evolution over time.”
FPF Asia-Pacific will focus on several priorities by the end of the year including hosting an event at this year’s Singapore Data Protection Week. The office will provide expertise in digital data flows and discuss emerging data protection issues in a way that is useful for regulators, policymakers, and legal professionals. Rajah & Tann Singapore LLP is supporting the work of the FPF Asia-Pacific office.
“The FPF global team will greatly benefit from the addition of Clarisse. She will advise FPF staff, advisory board members, and the public on the most significant privacy developments in the Asia-Pacific region, including data protection bills and cross-border data flows,” said Gabriela Zanfir-Fortuna, Director for Global Privacy at FPF. “Her past experience in both Asia and Europe gives her a unique ability to confront the most complex issues dealing with cross-border data protection.”
As over 140 countries have now enacted a privacy or data protection law, FPF continues to expand its international presence to help data protection experts grapple with the challenges of ensuring responsible uses of data. Following the appointment of Malavika Raghavan as Senior Fellow for India in 2020, the launch of the FPF Asia-Pacific office further expands FPF’s international reach.
Dr. Gabriela Zanfir-Fortuna leads FPF’s international efforts and works on global privacy developments and European data protection law and policy. The FPF Europe office is led by Dr. Rob van Eijk, who prior to joining FPF worked at the Dutch Data Protection Authority as Senior Supervision Officer and Technologist for nearly ten years. FPF has created thriving partnerships with leading privacy research organizations in the European Union, such as Dublin City University and the Brussels Privacy Hub of the Vrije Universiteit Brussel (VUB). FPF continues to serve as a leading voice in Europe on issues of international data flows, the ethics of AI, and emerging privacy issues. FPF Europe recently published a report comparing the regulatory strategy for 2021-2022 of 15 Data Protection Authorities to provide insights into the future of enforcement and regulatory action in the EU.
Outside of Europe, FPF has launched a variety of projects to advance tech policy leadership and scholarship in regions around the world, including Israel and Latin America. The work of the Israel Tech Policy Institute (ITPI), led by Managing Director Limor Shmerling Magazanik, includes publishing a report on AI Ethics in Government Services and organizing an OECD workshop with the Israeli Ministry of Health on access to health data for research.
In Latin America, FPF has partnered with the leading research association Data Privacy Brasil, provided in-depth analysis on Brazil’s LGPD privacy legislation and various data privacy cases decided in the Brazilian Supreme Court. FPF recently organized a panel during the CPDP LatAm Conference which explored the state of Latin American data protection laws alongside experts from Uber, the University of Brasilia, and the Interamerican Institute of Human Rights.
FPF and Leading Health & Equity Organizations Issue Principles for Privacy & Equity in Digital Contact Tracing Technologies
With support from the Robert Wood Johnson Foundation, FPF engaged leaders within the privacy and equity communities to develop actionable guiding principles and a framework to help bolster the responsible implementation of digital contact tracing technologies (DCTT). Today, seven privacy, civil rights, and health equity organizations signed on to these guiding principles for organizations implementing DCTT.
“We learned early in our Privacy and Pandemics initiative that unresolved ethical, legal, social, and equity issues may challenge the responsible implementation of digital contact tracing technologies,” said Jules Polonetsky, CEO of the Future of Privacy Forum. “So we engaged leaders within the civil rights, health equity, and privacy communities to create a set of actionable principles to help guide organizations implementing digital contact tracing that respects individual rights.”
Contact tracing has long been used to monitor the spread of various infectious diseases. In light of COVID-19, governments and companies began deploying digital exposure notification using Bluetooth and geolocation data on mobile devices to boost contact tracing efforts and quickly identify individuals who may have been exposed to the virus. However, as DCTT begins to play an important role in public health, it is important to take necessary steps to ensure equity in access to DCTT and understand the societal risks and tradeoffs that might accompany its implementation today and in the future. Governance efforts that seek to better understand these risks will be better able to bolster public trust in DCTT technologies.
“LGBT Tech is proud to have participated in the development of the Principles and Framework alongside FPF and other organizations. We are heartened to see that the focus of these principles is on historically underserved and under-resourced communities everywhere, like the LGBTQ+ community. We believe the Principles and Framework will help ensure that the needs and vulnerabilities of these populations are at the forefront during today’s pandemic and future pandemics.”
Carlos Gutierrez, Deputy Director, and General Counsel, LGBT Tech
“If we establish practices that protect individual privacy and equity, digital contact tracing technologies could play a pivotal role in tracking infectious diseases,” said Dr. Rachele Hendricks-Sturrup, Research Director at the Duke-Margolis Center for Health Policy. “These principles allow organizations implementing digital contact tracing to take ethical and responsible approaches to how their technology collects, tracks, and shares personal information.”
FPF, together with Dialogue on Diversity, the National Alliance Against Disparities in Patient Health (NADPH), BrightHive, and LGBT Tech, developed the principles, which advise organizations implementing DCTT to commit to the following actions:
Be Transparent About How Data Is Used and Shared.
Apply Strong De-Identification Techniques and Solutions.
Empower Users Through Tiered Opt-in/Opt-out Features and Data Minimization.
Acknowledge and Address Privacy, Security, and Nondiscrimination Protection Gaps.
Create Equitable Access to DCTT.
Acknowledge and Address Implicit Bias Within and Across Public and Private Settings.
Democratize Data for Public Good While Employing Appropriate Privacy Safeguards.
Adopt Privacy-By-Design Standards That Make DCTT Broadly Accessible.
Additional supporters of these principles include the Center for Democracy and Technology and Human Rights First.
To learn more and sign on to the DCTT Principles visit fpf.org/DCTT.
Support for this program was provided by the Robert Wood Johnson Foundation. The views expressed here do not necessarily reflect the views of the Foundation.
Navigating Preemption through the Lens of Existing State Privacy Laws
This post is the second of two posts on federal preemption and enforcement in United States federal privacy legislation. See Preemption in US Privacy Laws (June 14, 2021).
In drafting a federal baseline privacy law in the United States, lawmakers must decide to what extent the law will override state and local privacy laws. In a previous post, we discussed a survey of 12 existing federal privacy laws passed between 1968-2003, and the extent to which they are preemptive of similar state laws.
Another way to approach the same question, however, is to examine the hundreds of existing state privacy laws currently on the books in the United States. Conversations around federal preemption inevitably focus on comprehensive laws like the California Consumer Privacy Act, or the Virginia Consumer Data Protection Act — but there are hundreds of other state privacy laws on the books that regulate commercial and government uses of data.
In reviewing existing state laws, we find that they can be categorized usefully into: laws that complement heavily regulated sectors (such as health and finance); laws of general applicability; common law; laws governing state government activities (such as schools and law enforcement); comprehensive laws; longstanding or narrowly applicable privacy laws; and emerging sectoral laws (such as biometrics or drones regulations). As a resource, we recommend: Robert Ellis Smith, Compilation of State and Federal Privacy Laws (last supplemented in 2018).
Heavily Regulated Sectoral Silos. Most federal proposals for a comprehensive privacy law would not supersede other existing federal laws that contain privacy requirements for businesses, such as the Health Insurance Portability and Accountability Act (HIPAA) or the Gramm-Leach-Bliley Act (GLBA). As a result, a new privacy law should probably not preempt state sectoral laws that: (1) supplement their federal counterparts and (2) were intentionally not preempted by those federal regimes. In many cases, robust compliance regimes have been built around federal and state parallel requirements, creating entrenched privacy expectations, privacy tools, and compliance practices for organizations (“lock in”).
Laws of General Applicability. All 50 states have laws barring unfair and deceptive commercial and trade practices (UDAP), as well as generally applicable laws against fraud, unconscionable contracts, and other consumer protections. In cases where violations involve the mis-use of personal information, such claims could be inadvertently preempted by a national privacy law.
State Common Law. Privacy claims have been evolving in US common law over the last hundred years, and claims vary from state to state. A federal privacy law might preempt (or not preempt) claims brought under theories of negligence, breach of contract, product liability, invasions of privacy, or other “privacy torts.”
State Laws Governing State Government Activities. In general, states retain the right to regulate their own government entities, and a commercial baseline privacy law is unlikely to affect such state privacy laws. These include, for example, state “mini Privacy Acts” applying to state government agencies’ collection of records, state privacy laws applicable to public schools and school districts, and state regulations involving law enforcement — such as government facial recognition bans.
Comprehensive or Non-Sectoral State Laws. Lawmakers considering the extent of federal preemption should take extra care to consider the effect on different aspects of omnibus or comprehensive consumer privacy laws, such as the California Consumer Privacy Act (CCPA), the Colorado Privacy Act, and the Virginia Consumer Data Protection Act. In addition, however, there are a number of other state privacy laws that can be considered “non-sectoral” because they apply broadly to businesses that collect or use personal information. These include, for example, CalOPPA (requiring commercial privacy policies), the California “Shine the Light” law (requiring disclosures from companies that share personal information for direct marketing), data breach notification laws, and data disposal laws.
Congressional intent is the “ultimate touchstone” of preemption. Lawmakers should consider long-term effects on current and future state laws, including how they will be impacted by a preemption provision, as well as how they might be expressly preserved through a Savings Clause. In order to help build consensus, lawmakers should work with stakeholders and experts in the numerous categories of laws discussed above, to consider how they might be impacted by federal preemption.
Manipulative Design: Defining Areas of Focus for Consumer Privacy
In consumer privacy, the phrase “dark patterns” is everywhere. Emerging from a wide range of technical and academic literature, it now appears in at least two US privacy laws: the California Privacy Rights Act and the Colorado Privacy Act (which, if signed by the Governor, will come into effect in 2025).
Under both laws, companies will be prohibited from using “dark patterns,” or “user interface[s] designed or manipulated with the substantial effect of subverting or impairing user autonomy, decision‐making, or choice,” to obtain user consent in certain situations–for example, for the collection of sensitive data.
When organizations give individuals choices, some forms of manipulation have long been barred by consumer protection laws, with the Federal Trade Commission and state Attorneys General prohibiting companies from deceiving or coercing consumers into taking actions they did not intend or striking bargains they did not want. But consumer protection law does not typically prohibit organizations from persuading consumers to make a particular choice. And it is often unclear where the lines fall between cajoling, persuading, pressuring, nagging, annoying, or bullying consumers. The California and Colorado laws seek to do more than merely bar deceptive practices; they prohibit design that “subverts or impairs user autonomy.”
What does it mean to subvert user autonomy, if a design does not already run afoul of traditional consumer protections law? Just as in the physical world, the design of digital platforms and services always influences behavior — what to pay attention to, what to read and in what order, how much time to spend, what to buy, and so on. To paraphrase Harry Brignull (credited with coining the term), not everything “annoying” can be a dark pattern. Some examples of dark patterns are both clear and harmful, such as a design that tricks users into making recurring payments, or a service that offers a “free trial” and then makes it difficult or impossible to cancel. In other cases, the presence of “nudging” may be clear, but harms may be less clear, such as in beta-testing what color shades are most effective at encouraging sales. Still others fall in a legal grey area: for example, is it ever appropriate for a company to repeatedly “nag” users to make a choice that benefits the company, with little or no accompanying benefit to the user?
In Fall 2021, Future of Privacy Forum will host a series of workshops with technical, academic, and legal experts to help define clear areas of focus for consumer privacy, and guidance for policymakers and legislators. These workshops will feature experts on manipulative design in at least three contexts of consumer privacy: (1) Youth & Education; (2) Online Advertising and US Law; and (3) GDPR and European Law.
As lawmakers address this issue, we identify at least four distinct areas of concern:
Designs that cause concrete physical or financial harms to individuals. In some cases, design choices are implicated in concrete physical or financial harms. This might include, for example, a design that tricks users into making recurring payments, or makes unsubscribing from a free trial or other paid service difficult or impossible, leading to unwanted charges.
Designs that impact individual autonomy or dignity (but do not necessarily cause concrete physical or financial harm). In many cases, we observe concerns over autonomy and dignity, even where the use of data would not necessarily cause harm. For the same reasons that there is wide agreement that so-called subliminal messaging in advertising is wrong (as well as illegal), there is a growing awareness that disrespect for user autonomy in consumer privacy is objectionable on its face. As a result, in cases where the law requires consent, such as in the European Union for placement of information onto a user’s device, the law ought to provide a remedy for individuals who have been subject to a violation of that consent.
Designs that persuade, nag, or strongly push users towards a particular outcome, even where it may be possible for users to decline. In many cases, the design of a digital platform or serviceclearlypushes users towards a particular outcome, even if it is possible (if burdensome) for users to make a different choice. In such cases, we observe a wide spectrum of tactics that may be evaluated differently depending on the viewer and the context. Repeated requests may be considered “nagging” or “persuasion”; one person’s “clever marketing,” taken too far, becomes another person’s “guilt-shaming” or “confirm-shaming.” Ultimately, our preference for defaults (“opt in” versus “opt out”), and within those defaults, our level of tolerance for “nudging,” may be driven by the social benefits or values attached to the choice itself.
Designs that exploit biases, vulnerabilities, or heuristics in ways that implicate broader societal harms or values. Finally, we observe that the collection and use of personal information does not always solely impact individual decision-making. Often, the design of online platforms can influence groups in ways that impact societal values, such as the values of privacy, avoidance of “tech addiction,” free speech, the availability of data from or about marginalized groups, or the proliferation of unfair price discrimination or other market manipulation. Understanding how design choices may influence society, even if individuals are minimally impacted, may require examining the issues differently.
This week at the first edition of the annual Dublin Privacy Symposium, FPF will join other experts to discuss principles for transparency and trust. The design of user interfaces for digital products and services pervades modern life and directly impacts the choices people make with respect to sharing their personal information.
recast the conditions to obtain ‘safe harbour’ from liability for online intermediaries, and
unveiled an extensive regulatory regime for a newly defined category of online ‘publishers’, which includes digital news media and Over-The-Top (OTT) services.
The majority of these provisions were unanticipated, resulting in a raft of petitions filed in High Courts across the country challenging the validity of the various aspects of the Rules, including with regard to their constitutionality. On 25 May 2021, the three month compliance period on some new requirements for significant social media intermediaries (so designated by the Rules) expired, without many intermediaries being in compliance opening them up to liability under the Information Technology Act as well as wider civil and criminal laws. This has reignited debates about the impact of the Rules on business continuity and liability, citizens’ access to online services, privacy and security.
Following on FPF’s previous blog highlighting some aspects of these Rules, this article presents an overview of the Rules before deep-diving into critical issues regarding their interpretation and application in India. It concludes by taking stock of some of the emerging effects of these new regulations, which have major implications for millions of Indian users, as well as digital services providers serving the Indian market.
1.Brief overview of the Rules: Two new regimes for ‘intermediaries’ and ‘publishers’
The new Rules create two regimes for two different categories of entities: ‘intermediaries’ and ‘publishers’. Intermediaries have been the subject of prior regulations – the Information Technology (Intermediaries guidelines) Rules, 2011 (the 2011 Rules), now superseded by these Rules. However, the category of “publishers” and related regime created by these Rules did not previously exist.
The Rules begin with commencement provisions and definitions in Part I. Part II of the Rules apply to intermediaries (as defined in the Information Technology Act 2000 (IT Act)) who transmit electronic records on behalf of others, and includes online intermediary platforms (like Youtube, Whatsapp, Facebook). The rules in this part primarily flesh out the protections offered in Section 79 of India’s Information Technology Act 2000 (IT Act), which give passive intermediaries the benefit of a ‘safe harbour’ from liability for objectionable information shared by third parties using their services — somewhat akin to protections under section 230 of the US Communications Decency Act. To claim this protection from liability, intermediaries need to undertake certain ‘due diligence’ measures, including informing users of the types of content that could not be shared, and content take-down procedures (for which safeguards evolved overtime through important case law). The new Rules supersede the 2011 Rules and also significantly expand on them, introducing new provisions and additional due diligence requirements that are detailed further in this blog.
Part III of the Rules apply to a new previously non-existent category of entities designated to be ‘publishers‘. This is further classified into subcategories of ‘publishers of news and current affairs content’ and ‘publishers of online curated content’. Part III then sets up extensive requirements for publishers to adhere to specific codes of ethics, onerous content take-down requirements and three-tier grievance process with appeals lying to an Executive Inter-Departmental Committee of Central Government bureaucrats.
Finally, the Rules contain two provisions that apply to all entities (i.e. intermediaries and publishers) relating to content-blocking orders. They lay out a new process by which Central Government officials can issue directions to delete, modify or block content to intermediaries and publishers, either following a grievance process (Rule 15) or including procedures of “emergency”blocking orders which may be passed ex-parte. These Rules stem from powers to issue directions to intermediaries to block public access of any information through any computer resource (Section 69A of the IT Act). Interestingly, these provisions have been introduced separately from the existing rules for blocking purposes called the Information Technology (Procedure and Safeguards for Blocking for Access of Information by Public) Rules, 2009.
2.Key issues for intermediaries under the Rules
2.1 A new class of ‘social media intermediaries‘
The term ‘intermediary’ is a broadly defined term in the IT Act covering a range of entities involved in the transmission of electronic records. The Rules introduce two new sub-categories, being:
“social media intermediary” defined (in Rule 2(w)) as one who “primarily or solely enables online interaction between two or more users and allows them” to exchange information; and
“significant social media intermediary” (SSMI) comprising social media intermediaries with more than five million registered users in India (following this Government notification of the threshold).
Given that a popular messaging app like Whatsapp has over 400 million users in India, the threshold appears to be fairly conservative. The Government may order anyintermediary to comply with the same obligations as SSMIs (under Rule 6) if their services are adjudged to pose a risk of harm to national security, the sovereignty and integrity of India, India’s foreign relations or to public order.
SSMIs have to follow substantially more onerous “additional due diligence” requirements to claim the intermediary safe harbour (including mandatory traceability of message originators, and proactive automated screening as discussed below). These new requirements raise privacy concerns and data security concerns, as they extend beyond the traditional ideas of platform “due diligence”, they potentially expose content of private communications and in doing so create new privacy risks for users in India.
Extensive new requirements are set out in the new Rule 4 for SSMIs.
In-country employees: SSMIs must appoint in-country employees as (1) Chief Compliance Officer, (2) a nodal contact person for 24×7 coordination with law enforcement agencies and (3) a Resident Grievance Officer specifically responsible for overseeing the internal grievance redress mechanism. Monthly reporting of complaints management is also mandated.
Traceability requirements for SSMIs providing messaging services: Among the most controversial requirements is Rule 4(2) which requires SSMIs providing messaging services to enable the identification of the “first originator” of information on their platforms as required by Government or court orders. This tracing and identification of users is considered incompatible with end-to-end encryption technology employed by messaging applications like Whatsapp and Signal. In their legal challenge to this Rule, Whatsapp has noted that end-to-end encrypted platforms would need to be re-engineered to identify all users since there is no way to predict which user will be the subject of an order seeking first originator information.
Provisions to mandate modifications to the technical design of encrypted platforms to enable traceability seem to go beyond merely requiring intermediary due diligence. Instead they appear to draw on separate Government powers relating to interception and decryption of information (under Section 69 of the IT Act). In addition, separate stand-alone rules laying out procedures and safeguards for such interception and decryption orders already exist in the Information Technology (Procedure and Safeguards for Interception, Monitoring and Decryption of Information) Rules, 2009. Rule 4(2) even acknowledges these provisions–raising the question of whether these Rules (relating to intermediaries and their safe harbours) can be used to expand the scope of section 69 or rules thereunder.
Proceedings initiated by Whatsapp LLC in the Delhi High Court, and Free and Open Source Software (FOSS) developer Praveen Arimbrathodiyil in the Kerala High Court have both challenged the legality and validity of Rule 4(2) on grounds including that they are ultra vires and go beyond the scope of their parent statutory provisions (s. 79 and 69A) and the intent of the IT Act itself. Substantively, the provision is also challenged on the basis that it would violate users’ fundamental rights including the right to privacy, and the right to free speech and expression due to the chilling effect that the stripping back of encryption will have.
Automated content screening: Rule 4(4) mandates that SSMIs must employ technology-based measures including automated tools to proactively identify information depicting (i) rape, child sexual abuse or conduct, or (ii) any information previousy removed following a Government or court order. The latter category is very expansive and allows content take-downs for a broad range of reasons including defamatory or pornographic content, to IP infringements, to content threatening national security or public order (as set out in Rule 3(1)(d)).
Though the objective of the provision is laudable (i.e. to limit the circulation of violent or previously removed content), the move towards proactive automated monitoring has raised serious concerns regarding censorship on social media platforms. Rule 4(4) appears to acknowledge the deep tensions that this requirement raises with privacy and free speech concerns, as seen by the provisions that require these screening measures to be proportionate to the free speech and privacy of users, to be subject to human oversight, and reviews of automated tools to assess fairness, accuracy, propensity for bias or discrimination, and impact on privacy and security. However, given the vagueness of this wording compared to the trade-off of losing intermediary immunity, scholars and commentators are noting the obvious potential for ‘over-compliance’ and excessive screening out of content. Many (including the petitioner in the Praveen Arimbrathodiyil matter) have also noted that automated filters are not sophisticated enough to differentiate between violent unlawful images and legitimate journalistic material. The concern is that such measures could create a large-scale screening out of ‘valid’ speech and expression, with serious consequences for constitutional rights to free speech and expression which also protect ‘the rights of individuals to listen, read and receive the said speech‘ (Tata Press Ltd v. Mahanagar Telephone Nigam Ltd, (1995) 5 SCC 139).
Tighter timelines for grievance redress, content take down and information sharing with law enforcement:Rule 3 includes enhanced requirements to serve privacy policies and user agreements outlining the terms of use, including annual reminders of these terms and any modifications and of the intermediaries’ right to terminate the user’s access for using the service in contravention of these terms. The Rule also has enhanced grievance redress processes for intermediaries, by expanding these requirements to mandate that the complaints system acknowledge complaints within 24 hours, and dispose of them in 15 days. In the case of certain categories of complaints (where a person complains of inappropriate images or impersonations of them being circulated), the removal of access to the material is mandated within 24 hours based on a prima facie assessment.
Such requirements appear to be aimed at creating more user-friendly networks of intermediaries. However, the imposition of a single set of requirements is especially onerous for smaller or volunteer-run intermediary platforms which may not have income streams or staff to provide for such a mechanism. Indeed, the petition in the Praveen Arimbrathodiyil matter has challenged certain of these requirements as being a threat to the future of the volunteer-led Free and Open Source Software (FOSS) movement in India, by placing similar requirements on small FOSS initiatives as on large proprietary Big Tech intermediaries.
Other obligations that stipulate turn-around times for intermediaries include (i) a requirement to remove or disable access to content within 36 hours of receipt of a Government or court order relating the unlawful information on the intermediary’s computer resources (under Rule 3(1)(d)) and (ii) to provide information within 72 hours of receiving an order from a authorised Government agency undertaking investigative activity (under Rule 3(1)(j).
Similar to the concerns with automated screening, there are concerns that the new grievance process could lead to private entities becoming the arbiters of appropriate content/ free speech — a position that was specifically reversed in a seminal 2015 Supreme Court decision that clarified that a Government or Court order was needed for content-takedowns.
3. Key issues for the new ‘publishers’ subject to the Rules, including OTT players
3.1New Codes of Ethics and three-tier redress and oversight system for digital news media and OTT players
Digital news media and OTT players have been designated as ‘publishers of news and current affairs content’ and ‘publishers of online curated content’ respectively in Part III of the Rules. Each category has been then subjected to separate Codes of Ethics. In the case of digital news media, the Codes applicable to the newspapers and cable television have been applied. For OTT players, the Appendix sets out principles regarding content that can be created and display classifications. To enforce these codes and to address grievances from the public on their content, publishers are now mandated to set up a grievance system which will be the first tier of a three-tier “appellate” system culminating in an oversight mechanism by the Central Government with extensive powers of sanction.
Some of the key issues emerging from these Rules in Part III and the challenges to them are highlighted below.
3.2 Lack of legal authority and competence to create these Rules
There has been substantial debate on the lack of clarity regarding the legal authority of the Ministry of Electronics & Information Technology (MeitY) under the IT Act. These concerns arise at various levels.
Authority and competence to regulate ‘publishers’ of original content is unclear: The definition of ‘intermediary’ in the IT Act does not extend to cover types of entities defined to be publishers. The Rules themselves acknowledge that ‘publishers’ are a new category of regulated entity created by the Rules, as opposed to a sub-category of intermediaries. Further, the commencement of the Rules also confirm that they are passed under statutory provisions in the IT Act related to intermediary regulation. It is a well established principle that subordinate rules cannot go beyond the object and scope of parent statutory provisions (Ajoy Kumar Banerjee v Union of India (1984) 3 SCC 127). Consequently, the authority of MeitY to regulate entities that create original content – like online news sources and OTT platforms – remains unclear at best.
Ability to extend substantive provisions in other statutes through the Rules: The Rules apply two codes of conduct to digital publishers of news and current affairs content, namely (i) the Norms of Journalistic Conduct of the Press Council of India under the Press Council Act, 1978; (ii) Programme Code under section 5 of the Cable Television Networks Regulation) Act, 1995. Many, including petitioners in the LiveLaw matterhave noted that the power to make Rules under the IT Act’s s 87 cannot be used to extend or expand requirements under other statutes and their subordinate rules. To bring digital news media or OTT players into existing regulatory regimes for the Press and television broadcasting, amendments to those regimes will be required led by the Ministry of Information and Broadcasting.
Validity of three-tier ‘quasi-judicial’ adjudicatory mechanism, with final appeal to Committee of solely executive functionaries: Rules 11 – 14 create a three-tier grievance and oversight system which can be used by any person with a grievance against content published by any publisher. Under this model, any person having a grievance with any material published by a publisher can complain through the publisher’s redress process. If any grievance is not satisfactorily dealt with by the publisher entity (Level I) in 15 days, it will be escalated to the self regulatory body of which the publisher is a member (Level II) which must also provide a decision to the complainant within 15 days. If the complainant is unsatisfied, they may appeal to the Oversight Mechanism (in Level III). This can be appreciated as an attempt to create feedback loops that can minimise the spread of misleading or incendiary media, disinformation etc through a more effective grievance mechanism. The structure and design of the three-tier structure have however raised specific concerns.
First, there is a concern that Level I & II result in a privatisation of adjudications relating to free speech and expression of creative content producers – which would otherwise be litigated in Courts and Tribunals as matters of free speech. As noted by many (including the LiveLaw petition at page 33), this could have the effect of overturning judicial precedent in Shreya Singhal v. Union of India ((2013) 12 S.C.C. 73) that specifically read down s 79 of the IT Act to avoid a situation where private entities were the arbiters determining the legitimacy of takedown orders. Second, despite referring to “self-regulation” this system is subject to executive oversight (unlike the existing models for offline newspapers and broadcasting).
The Inter-Departmental Committee is entirely composed of Central Government bureaucrats, and it may review complaints through the three-tier system or referred directly by the Ministry following which it can deploy a range of sanctions from warnings, to mandating apologies, to deleting, modifying or blocking content. This also raises the question of whether this Committee meets the legal requirements for any administrative body undertaking a ‘quasi-judicial’ function, especially one that may adjudicate on matters of rights relating to free speech and privacy. Finally, while the objective of creating some standards and codes for such content creators may be laudable it is unclear whether such an extensive oversight mechanism with powers of sanction on online publishers can be validly created under the rubric of intermediary liability provisions.
4. New powers to delete, modify or block information for public access
As described at the start of this blog, the Rules add new powers for the deletion, modification and blocking of content from intermediaries and publishers. While section 69A of the IT Act (and Rules thereunder) do include blocking powers for Government, they only exist vis a vis intermediaries. Rule 15 also expands this power to ‘publishers’. It also provides a new avenue for such orders to intermediaries, outside of the existing rules for blocking information under the Information Technology (Procedure and Safeguards for Blocking for Access of Information by Public) Rules, 2009.
More grave concerns arise from Rule 16 which allows for the passing of emergency orders for blocking information, including without giving an opportunity of hearing for publishers or intermediaries. There is a provision for such an order to be reviewed by the Inter-Departmental Committee within 2 days of its issue.
Both Rule 15 and 16 apply to all entities contemplated in the Rules. Accordingly, they greatly expand executive power and oversight over digital media services in India, including social media, digital news media and OTT on-demand services.
5. Conclusions and future implications
The new Rules in India have opened up deep questions for online intermediaries and providers of digital media services serving the Indian market.
For intermediaries, this creates a difficult and even existential choice: the requirements, (especially relating to traceability and automated screening) appear to set an improbably high bar given the reality of their technical systems. However, failure to comply will result in not only the loss of a safe harbour from liability — but as seen in new Rule 7, also opens them up to punishment under the IT Act and criminal law in India.
For digital news and OTT players, the consequences of non-compliance and the level of enforcement remain to be understood, especially given open questions regarding the validity of legal basis to create these rules. Given the numerous petitions filed against these Rules, there is also substantial uncertainty now regarding the future although the Rules themselves have the full force of law at present.
Overall, it does appear that attempts to create a ‘digital media’ watchdog would be better dealt with in a standalone legislation, potentially sponsored by the Ministry of Information and Broadcasting (MIB) which has the traditional remit over such areas. Indeed, the administration of Part III of the Rules has been delegated by MeitY to MIB pointing to the genuine split in competence between these Ministries.
Finally, the potential overlaps with India’s proposed Personal Data Protection Bill (if passed) also create tensions in the future. It remains to be seen if the provisions on traceability will survive the test of constitutional validity set out in India’s privacy judgement (Justice K.S. Puttaswamy v. Union of India, (2017) 10 SCC 1). Irrespective of this determination, the Rules appear to have some dissonance with the data retention and data minimisation requirements seen in the last draft of the Personal Data Protection Bill, not to mention other obligations relating to Privacy by Design and data security safeguards. Interestingly, despite the Bill’s release in December 2019, a definition for ‘social media intermediary’ that it included in an explanatory clause to its section 26(4) closely track the definition in Rule 2(w), but also departs from it by carving out certain intermediaries from the definition. This is already resulting in moves such as Google’s plea on 2 June 2021 in the Delhi High Court asking for protection from being declared a social media intermediary.
These new Rules have exhumed the inherent tensions that exist within the realm of digital regulation between goals of the freedom of speech and expression, and the right to privacy and competing governance objectives of law enforcement (such as limiting the circulation of violent, harmful or criminal content online) and national security. The ultimate legal effect of these Rules will be determined as much by the outcome of the various petitions challenging their validity, as by the enforcement challenges raised by casting such a wide net that covers millions of users and thousands of entities, who are all engaged in creating India’s growing digital public sphere.
New FPF Report Highlights Privacy Tech Sector Evolving from Compliance Tools to Platforms for Risk Management and Data Utilization
As we enter the third phase of development of the privacy tech market, purchasers are demanding more integrated solutions, product offerings are more comprehensive, and startup valuations are higher than ever, according to a new report from the Future of Privacy Forum and Privacy Tech Alliance. These factors are leading to companies providing a wider range of services, acting as risk management platforms, and focusing on support of business outcomes.
“The privacy tech sector is at an inflection point, as its offerings have expanded beyond assisting with regulatory compliance,” said FPF CEO Jules Polonetsky. “Increasingly, companies want privacy tech to help businesses maximize the utility of data while managing ethics and data protection compliance.”
According to the report, “Privacy Tech’s Third Generation: A Review of the Emerging Privacy Tech Sector,” regulations are often the biggest driver for buyers’ initial privacy tech purchases. Organizations also are deploying tools to mitigate potential harms from the use of data. However, buyers serving global markets increasingly need privacy tech that offers data availability and control and supports its utility, in addition to regulatory compliance.
The report finds the COVID-19 pandemic has accelerated global marketplace adoption of privacy tech as dependence on digital technologies grows. Privacy is becoming a competitive differentiator in some sectors, and TechCrunch reports that 200+ privacy startups have together raised more than $3.5 billion over hundreds of individual rounds of funding.
“The customers buying privacy-enhancing tech used to be primarily Chief Privacy Officers,” said report lead author Tim Sparapani. “Now it’s also Chief Marketing Officers, Chief Data Scientists, and Strategy Officers who value the insights they can glean from de-identified customer data.”
The report highlights five trends in the privacy enhancing tech market:
Buyers desire “enterprise-wide solutions.”
Buyers favor integrated technologies.
Some vendors are moving to either collaborate and integrate or provide fully integrated solutions themselves.
Data is the enterprise asset.
Jurisdiction impacts a shared vernacular problem.
The report also draws seven implications for competition in the market:
Buyers favor integrated solutions over one-off solutions.
Collaborations, partners, cross-selling, and joint ventures between privacy tech vendors are increasing to provide buyers integrated suites of services and to attract additional market share.
Private equity and private equity-backed companies will continue their “roll-up” strategies of buying niche providers to build a package of companies to provide the integrated solutions buyers favor.
Venture capital will continue funding the privacy tech sector, though not every seller has the same level of success fundraising.
Big companies may acquire strategically valuable, niche players.
Small startups may struggle to gain market traction absent a truly novel or superb solution.
Buyers will face challenges in future-proofing their privacy strategies.
The report makes a series of recommendations, including that the industry define as a priority a common vernacular for privacy tech; set standards for technologies in the “privacy stack” such as differential privacy, homomorphic encryption, and federated learning; and explore the needs of companies for privacy tech based upon their size, sector, and structure. It calls on vendors to recognize the need to provide adequate support to customers to increase uptake and speed time from contract signing to successful integration.
The Future of Privacy Forum launched the Privacy Tech Alliance (PTA) as a global initiative with a mission to define, enhance and promote the market for privacy technologies. The PTA brings together innovators in privacy tech with customers and key stakeholders.
Members of the PTA Advisory Board, which includes Anonos, BigID, D-ID, Duality, Ethyca, Immuta, OneTrust, Privacy Analytics, Privitar, SAP, Truata, TrustArc, Wirewheel, and ZL Tech, have formed a working group to address impediments to growth identified in the report. The PTA working group will define a common vernacular and typology for privacy tech as a priority project with chief privacy officers and other industry leaders who are members of FPF. Other work will seek to develop common definitions and standards for privacy-enhancing technologies such as differential privacy, homomorphic encryption, and federated learning and identify emerging trends for venture capitalists and other equity investors in this space. Privacy Tech companies can apply to join the PTA by emailing [email protected].
Perspectives on the Privacy Tech Market
Quotes from Members of the Privacy Tech Alliance Advisory Board on the Release of the “Privacy Tech’s Third Generation” Report
“The ‘Privacy Tech Stack’ outlined by the FPF is a great way for organizations to view their obligations and opportunities to assess and reconcile business and privacy objectives. The Schrems II decision by the Court of Justice of the European Union highlights that skipping the second ‘Process’ layer can result in desired ‘Outcomes’ in the third layer (e.g., cloud processing of, or remote access to, cleartext data) being unlawful – despite their global popularity – without adequate risk management controls for decentralized processing.” — Gary LaFever, CEO & General Counsel, Anonos
“As a founding member of this global initiative, we are excited by the conclusions drawn from this foundational report – we’ve seen parallels in our customer base, from needing an enterprise-wide solution to the rich opportunity for collaboration and integration. The privacy tech sector continues to mature as does the imperative for organizations of all sizes to achieve compliance in light of the increasingly complicated data protection landscape.’’—Heather Federman, VP Privacy and Policy at BigID
“There is no doubt of the massive importance of the privacy sector, an area which is experiencing huge growth. We couldn’t be more proud to be part of the Privacy Tech Alliance Advisory Board and absolutely support the work they are doing to create alignment in the industry and help it face the current set of challenges. In fact we are now working on a similar initiative in the synthetic media space to ensure that ethical considerations are at the forefront of that industry too.” — Gil Perry, Co-Founder & CEO, D-ID
“We congratulate the Future of Privacy Forum and the Privacy Tech Alliance on the publication of this highly comprehensive study, which analyzes key trends within the rapidly expanding privacy tech sector. Enterprises today are increasingly reliant on privacy tech, not only as a means of ensuring regulatory compliance but also in order to drive business value by facilitating secure collaborations on their valuable and often sensitive data. We are proud to be part of the PTA Advisory Board, and look forward to contributing further to its efforts to educate the market on the importance of privacy-tech, the various tools available and their best utilization, ultimately removing barriers to successful deployments of privacy-tech by enterprises in all industry sectors” — Rina Shainski, Chairwoman, Co-founder, Duality
“Since the birth of the privacy tech sector, we’ve been helping companies find and understand the data they have, compare it against applicable global laws and regulations, and remediate any gaps in compliance. But as the industry continues to evolve, privacy tech also is helping show business value beyond just compliance. Companies are becoming more transparent, differentiating on ethics and ESG, and building businesses that differentiate on trust. The privacy tech industry is growing quickly because we’re able to show value for compliance as well as actionable business insights and valuable business outcomes.” — Kabir Barday, CEO, OneTrust
“Leading organizations realize that to be truly competitive in a rapidly evolving marketplace, they need to have a solid defensive footing. Turnkey privacy technologies enable them to move onto the offense by safely leveraging their data assets rapidly at scale.” — Luk Arbuckle, Chief Methodologist, Privacy Analytics
“We appreciate FPF’s analysis of the privacy tech marketplace and we’re looking forward to further research, analysis, and educational efforts by the Privacy Tech Alliance. Customers and consumers alike will benefit from a shared understanding and common definitions for the elements of the privacy stack.” — Corinna Schulze, Director, EU Government Relations, Global Corporate Affairs, SAP
“The report shines a light on the evolving sophistication of the privacy tech market and the critical need for businesses to harness emerging technologies that can tackle the multitude of operational challenges presented by the big data economy. Businesses are no longer simply turning to privacy tech vendors to overcome complexities with compliance and regulation; they are now mapping out ROI-focused data strategies that view privacy as a key commercial differentiator. In terms of market maturity, the report highlights a need to overcome ambiguities surrounding new privacy tech terminology, as well as discrepancies in the mapping of technical capabilities to actual business needs. Moving forward, the advantage will sit with those who can offer the right blend of technical and legal expertise to provide the privacy stack assurances and safeguards that buyers are seeking – from a risk, deployment and speed-to-value perspective. It’s worth noting that the growing importance of data privacy to businesses sits in direct correlation with the growing importance of data privacy to consumers. Trūata’s Global Consumer State of Mind Report 2021 found that 62% of global consumers would feel more reassured and would be more likely to spend with companies if they were officially certified to a data privacy standard. Therefore, in order to manage big data in a privacy-conscious world, the opportunity lies with responsive businesses that move with agility and understand the return on privacy investment. The shift from manual, restrictive data processes towards hyper automation and privacy-enhancing computation is where the competitive advantage can be gained and long-term consumer loyalty—and trust— can be retained.” — Aoife Sexton, Chief Privacy Officer and Chief of Product Innovation, Trūata
“As early pioneers in this space, we’ve had a unique lens on the evolving challenges organizations have faced in trying to integrate technology solutions to address dynamic, changing privacy issues in their organizations, and we believe the Privacy Technology Stack introduced in this report will drive better organizational decision-making related to how technology can be used to sustainably address the relationships among the data, processes, and outcomes.” — Chris Babel, CEO, TrustArc
“It’s important for companies that use data to do so ethically and in compliance with the law, but those are not the only reasons why the privacy tech sector is booming. In fact, companies with exceptional privacy operations gain a competitive advantage, strengthen customer relationships, and accelerate sales.” — Justin Antonipillai, Founder & CEO, Wirewheel
The right to be forgotten is not compatible with the Brazilian Constitution. Or is it?
The Brazilian Supreme Federal Court, or “STF” in its Brazilian acronym, recently took a landmark decision concerning the right to be forgotten (RTBF), finding that it is incompatible with the Brazilian Constitution. This attracted international attention to Brazil for a topic quite distant than the sadly frequent environmental, health, and political crises.
Readers should be warned that while reading this piece they might experience disappointment, perhaps even frustration, then renewed interest and curiosity and finally – and hopefully – an increased open-mindedness, understanding a new facet of the RTBF debate, and how this is playing out at constitutional level in Brazil.
This might happen because although the STF relies on the “RTBF” label, the content behind such label is quite different from what one might expect after following the same debate in Europe. From a comparative law perspective, this landmark judgment tellingly shows how similar constitutional rights play out in different legal cultures and may lead to heterogeneous outcomes based on the constitutional frameworks of reference.
How it started: insolvency seasoned with personal data
As it is well-known, the first global debate on what it means to be “forgotten” in the digital environment arose in Europe, thanks to Mario Costeja Gonzalez, a Spaniard who, paradoxically, will never be forgotten by anyone due to his key role in the construction of the RTBF.
Costeja famously requested to deindex from Google Search information about himself that he considered to be no longer relevant. Indeed, when anyone “googled” his name, the search engine provided as the top results some link to articles reporting Costeja’s past insolvency as a debtor. Costeja argued that, despite having been convicted for insolvency, he had already paid his debt with Justice and society many years before and it was therefore unfair that his name would continue to be associated ad aeternum with a mistake he made in the past.
The follow up is well known in data protection circles. The case reached the Court of Justice of the European Union (CJEU), which, in its landmark Google Spain Judgment (C-131/12), established that search engines shall be considered as data controllers and, therefore, they have an obligation to de-index information that is inappropriate, excessive, not relevant, or no longer relevant, when a data subject to whom such data refer requests it. Such an obligation was a consequence of Article 12.b of Directive 95/46 on the protection of personal data, a pre-GDPR provision that set the basis for the European conception of the RTBF, providing for the “rectification, erasure or blocking of data the processing of which does not comply with the provisions of [the] Directive, in particular because of the incomplete or inaccurate nature of the data.”
The indirect consequence of this historic decision, and the debate it generated, is that we have all come to consider the RTBF in the terms set by the CJEU. However, what is essential to emphasize is that the CJEU approach is only one possible conception and, importantly, it was possible because of the specific characteristics of the EU legal and institutional framework. We have come to think that RTBF means the establishment of a mechanism like the one resulting from the Google Spain case, but this is the result of a particular conception of the RTBF and of how this particular conception should – or could – be implemented.
The fact that the RTBF has been predominantly analyzed and discussed through the European lenses does not mean that this is the only possible perspective, nor that this approach is necessary the best. In fact, the Brazilian conception of the RTBF is remarkably different from a conceptual, constitutional, and institutional standpoint. The main concern of the Brazilian RTBF is not how a data controller might process personal data (this is the part where frustration and disappointment might likely arise in the reader) but the STF itself leaves the door open to such possibility (this is the point where renewed interest and curiosity may arise).
The Brazilian conception of the right to be forgotten
Although the RTBF has acquired a fundamental relevance in digital policy circles, it is important to emphasize that, until recently, Brazilian jurisprudence had mainly focused on the juridical need for “forgetting” only in the analogue sphere. Indeed, before the CJEU Google Spain decision, the Brazilian Supreme Court of Justice or “STJ” – the other Brazilian Supreme Court that deals with the interpretation of the Law, differently from the previously mentioned STF, which deals with the interpretation of constitutional matters – had already considered the RTBF as a right not to be remembered, affirmed by the individual vis-à-vis traditional media outlets.
This interpretation first emerged in the “Candelaria massacre” case, a gloomy page of Brazilian history, featuring a multiple homicide perpetrated in 1993 in front of the Candelaria Church, a beautiful colonial Baroque building in Rio de Janeiro’s downtown. The gravity and the particularly picturesque stage of the massacre led Globo TV, a leading Brazilian broadcaster, to feature the massacre in a TV show called Linha Direta. Importantly, the show included in the narration some details about a man suspected of being one of the perpetrators of the massacre but later discharged.
Understandably, the man filed a complaint arguing that the inclusion of his personal information in the TV show was causing him severe emotional distress, while also reviving suspects against him, for a crime he had already been discharged of many years before. In September 2013, further to Special Appeal No. 1,334,097, the STJ agreed with the plaintiff establishing the man’s “right not to be remembered against his will, specifically with regard to discrediting facts.” This is how the RTBF was born in Brazil.
Importantly for our present discussion, this interpretation is not born out of digital technology and does not impinge upon the delisting of specific type of information as results of search engine queries. In Brazilian jurisprudence the RTBF has been conceived as a general right to effectively limit the publication of certain information. The man included in the Globo reportage had been discharged many years before, hence he had a right to be “let alone,” as Warren and Brandeis would argue, and not to be remembered for something he had not even committed. The STJ, therefore, constructed its vision of the RTBF, based on article 5.X of the Brazilian Constitution, enshrining the fundamental right to intimacy and preservation of image, two fundamental features of privacy.
Hence, although they utilize the same label, the STJ and CJEU conceptualize two remarkably different rights, when they refer to the RTBF. While both conceptions aim at limiting access to specific types of personal information, the Brazilian conception differs from the EU one on at least three different levels.
First, their constitutional foundations. While both conceptions are intimately intertwined with individuals’ informational self-determination, the STJ built the RTBF based on the protection of privacy, honour and image, whereas the CJEU built it upon the fundamental right to data protection, which in the EU framework is a standalone fundamental right. Conspicuously, in the Brazilian constitutional framework an explicit right to data protection did not exist at the time of the Candelaria case and only since 2020 it has been in the process of being recognized.
Secondly, and consequently, the original goal of the Brazilian conception of the RTBF was not to regulate how a controller should process personal data but rather to protect the private sphere of the individual. In this perspective, the goal of STJ was not – and could not have been – to regulate the deindexation of specific incorrect or outdated information, but rather to regulate the deletion of “discrediting facts” so that the private life, honour and image of any individual might be illegitimately violated.
Finally, yet extremely importantly, the fact that, at the time of the decision, an institutional framework dedicated to data protection was simply absent in Brazil did not allow the STJ to have the same leeway of the CJEU. The EU Justices enjoyed the privilege of delegating to search engine the implementation of the RTBF because, such implementation would have received guidance and would have been subject to the review of a well-consolidated system of European Data Protection Authorities. At the EU level, DPAs are expected to guarantee a harmonious and consistent interpretation and application of data protection law. At the Brazilian level, a DPA has just been established in late 2020 and announced its first regulatory agenda only in late January 2021.
This latter point is far from trivial and, in the opinion of this author, an essential preoccupation that might have driven the subsequent RTBF conceptualization of the STJ.
The stress-test
The soundness of the Brazilian definition of the RTBF, however, was going to be tested again by the STJ, in the context of another grim and unfortunate page of Brazilian story, the Aida Curi case. This case originated with the sexual assault and subsequent homicide of the young Aida Curi, in Copacabana, Rio de Janeiro, on the evening of 14 July 1958. At the time the case crystallized considerable media attention, not only because of its mysterious circumstances and the young age of the victim, but also because the sexual assault perpetrators tried to dissimulate it by throwing the body of the victim from the rooftop of a very high building on the Avenida Atlantica, the fancy avenue right in front of the Copacabana beach.
Needless to say, Globo TV considered the case as a perfect story for yet another Linha Direta episode. Aida Curi’s relatives, far from enjoying the TV show, sued the broadcaster for moral damages and demanded the full enjoyment of their RTBF – in the Brazilian conception, of course. According to the plaintiffs, it was indeed not conceivable that, almost 50 years after the murder, Globo TV could publicly broadcast personal information about the victim – and her family – including the victim’s name and address, in addition to unauthorized images, thus bringing back a long-closed and extremely traumatic set of events.
The brothers of Aida Curi claimed reparation against Rede Globo, but the STJ, decided that the time passed was enough to mitigate the effects of anguish and pain on the dignity of Aida Curi’s relatives, while arguing that it was impossible to report the events without mentioning the victim. This decision was appealed by Ms Curi’s family members, who demanded by means of Extraordinary Appeal No. 1,010,606, that STF recognized “their right to forget the tragedy.” It is interesting to note that the way the demand is constructed in this Appeal exemplifies tellingly the Brazilian conception of “forgetting” as erasure and prohibition from divulgation.
At this point, the STF identified in the Appeal the interest of debating the issue “with general repercussion” which is a peculiar judicial process that the Court can utilize when recognizes that a given case has particular relevance and transcendence for the Brazilian legal and judicial system. Indeed, the decision of a case with general repercussion does not only bind the parties but rather establishes a jurisprudence that must be replicated by all lower-level courts.
In February 2021, the STF finally deliberated on the Aida Curi case, establishing that “the idea of a right to be forgotten is incompatible with the Constitution, thus understood as the power to prevent, due to the passage of time, the disclosure of facts or data that are true and lawfully obtained and published in analogue or digital media” and that “any excesses or abuses in the exercise of freedom of expression and information must be analyzed on a case-by-case basis, based on constitutional parameters – especially those relating to the protection of honor, image, privacy and personality in general – and the explicit and specific legal provisions existing in the criminal and civil spheres.”
In other words, what the STF has deemed as incompatible with the Federal Constitution is a specific interpretation of the Brazilian version of the RTBF. What is not compatible with the Constitution is to argue that the RTBF allows to prohibit publishing true facts, lawfully obtained. At the same time, however, the STF clearly states that it remains possible for any Court of law to evaluate, on a case-by-case basis and according to constitutional parameters and existing legal provisions, if a specific episode can allow the use of the RTBF to prohibit the divulgation of information that undermine the dignity, honour, privacy, or other fundamental interests of the individual.
Hence, while explicitly prohibiting the use of the RTBF as a general right to censorship, the STF leaves room for the use of the RTBF for delisting specific personal data in an EU-like fashion, while specifying that this must be done finding guidance in the Constitution and the Law.
What next?
Given the core differences between the Brazilian and EU conception of the RTBF, as highlighted above, it is understandable in the opinion of this author that the STF adopted a less proactive and more conservative approach. This must be especially considered in light of the very recent establishment of a data protection institutional system in Brazil.
It is understandable that the STF might have preferred to de facto delegate the interpretation of when and how the RTBF could be rightfully invoked before Courts, according to constitutional and legal parameters. First, in the Brazilian interpretation of the RTBF, this right fundamentally insist on the protection of privacy – i.e. the private sphere of an individual – and, while admitting the existence of data protection concerns, these are not the main ground on which the Brazilian RTBF conception relays.
It is understandable that in a country and a region where the social need to remember and shed light on what happened in a recent history, marked by dictatorships, well-hidden atrocities, and opacity, outweighs the legitimate individual interest to prohibit the circulation of truthful and legally obtained information. In the digital sphere, however, the RTBF quintessentially translates into an extension of informational self-determination, which the Brazilian General Data Protection Law, better known as “LGPD” (Law No. 13.709 / 2018), enshrines in its article 2 as one of the “foundations” of data protection in the country and that whose fundamental character was recently recognized by the STF itself.
In this perspective, it is useful to remind the dissenting opinion of Justice Luiz Edson Fachin, in the Aida Curi case, stressing that “although it does not expressly name it, the Constitution of the Republic, in its text, contains the pillars of the right to be forgotten, as it celebrates the dignity of the human person (article 1, III), the right to privacy (article 5, X) and the right to informational self-determination – which was recognized, for example, in the disposal of the precautionary measures of the Direct Unconstitutionality Actions No. 6,387, 6,388, 6,389, 6,390 and 6,393, under the rapporteurship of Justice Rosa Weber (article 5, XII).”
It is the opinion of this author that the Brazilian debate on the RTBF in the digital sphere would be clearer if it its dimension as a right to deindexation of search engines results were to be clearly regulated. It is understandable that the STF did not dare regulating this, given its interpretation of the RTBF and the very embryonic data protection institutional framework in Brazil. However, given the increasing datafication we are currently witnessing, it would be naïve not to expect that further RTBF claims concerning the digital environment and, specifically, the way search engines process personal data will keep emerging.
The fact that the STF has left the door open to apply the RTBF in the case-by-case analysis of individual claims may reassure the reader regarding the primacy of constitutional and legal arguments in such case-by-case analysis. It may also lead the reader to – very legitimately – wonder whether such a choice is the facto the most efficient to deal with the potentially enormous number of claims and in the most coherent way, given the margin of appreciation and interpretation that each different Court may have.
An informed debate able to clearly highlight what are the existing options and what might be the most efficient and just ways to implement them, considering the Brazilian context, would be beneficial. This will likely be one of the goals of the upcoming Latin American edition of the Computers, Privacy and Data Protection conference (CPDP LatAm) that will take place in July, entirely online, and will aim at exploring the most pressing issues for Latin American countries regarding privacy and data protection.
If you have any questions about engaging with The Future of Privacy Forum on Global Privacy and Digital Policymaking contact Dr. Gabriela Zanfir-Fortuna, Senior Counsel, at [email protected].
FPF announces appointment of Malavika Raghavan as Senior Fellow for India
The Future of Privacy Forum announces the appointment of Malavika Raghavan as Senior Fellow for India, expanding our Global Privacy team to one of the key jurisdictions for the future of privacy and data protection law.
Malavika is a thought leader and a lawyer working on interdisciplinary research, focusing on the impacts of digitisation on the lives of lower-income individuals. Her work since 2016 has focused on the regulation and use of personal data in service delivery by the Indian State and private sector actors. She has founded and led the Future of Finance Initiative for Dvara Research (an Indian think tank) in partnership with the Gates Foundation from 2016 until 2020, anchoring its research agenda and policy advocacy on emerging issues at the intersection of technology, finance and inclusion. Research that she led at Dvara Research was cited by the India’s Data Protection Committee in its White Paper as well as its final report with proposals for India’s draft Personal Data Protection Bill, with specific reliance placed on such research on aspects of regulatory design and enforcement. See Malavika’s full bio here.
“We are delighted to welcome Malavika to our Global Privacy team. For the following year, she will be our adviser to understand the most significant developments in privacy and data protection in India, from following the debate and legislative process of the Data Protection Bill and the processing of non-personal data initiatives, to understanding the consequences of the publication of the new IT Guidelines. India is one of the most interesting jurisdictions to follow in the world, for many reasons: the innovative thinking on data protection regulation, the potentially groundbreaking regulation of non-personal data and the outstanding number of individuals whose privacy and data protection rights will be envisaged by these developments, which will test the power structures of digital regulation and safeguarding fundamental rights in this new era”, said Dr. Gabriela Zanfir-Fortuna, Global Privacy lead at FPF.
We have asked Malavika to share her thoughts for FPF’s blog on what are the most significant developments in privacy and digital regulation in India and about India’s role in the global privacy and digital regulation debate.
FPF: What are some of the most significant developments in the past couple of years in India in terms of data protection, privacy, digital regulation?
Malavika Raghavan: “Undoubtedly, the turning point for the privacy debate India was the 2017 judgement of the Indian Supreme Court in Justice KS Puttaswamy v Union of India. The judgment affirmed the right to privacy as a constitutional guarantee, protected by Part III (Fundamental Rights) of the Indian Constitution. It was also regenerative, bringing our constitutional jurisprudence into the 21st century by re-interpreting timeless principles for the digital age, and casting privacy as a prerequisite for accessing other rights—including the right to life and liberty, to freedom of expression and to equality—given the ubiquitous digitisation of human experience we are witnessing today.
Overnight, Puttaswamy also re-balanced conversations in favour of privacy safeguards to make these equal priorities for builders of digital systems, rather than framing these issues as obstacles to innovation and efficiency. In addition, it challenged the narrative that privacy is an elite construct that only wealthy or privileged people deserve— since many litigants in the original case that had created the Puttaswamy reference were from marginalised groups. Since then, a string of interesting developments have arisen as new cases are reassessing the impact of digital technology on individuals in India, for e.g. the boundaries case of private sector data sharing (such as between Whatsapp and Facebook), or the State’s use of personal data (as in the case concerning Aadhaar, our national identification system) among others.
Puttaswamy also provided fillip for a big legislative development, which is the creation of an omnibus data protection law in India. A bill to create this framework was proposed by a Committee of Experts under the chairmanship of Justice Srikrishna (an ex-Supreme Court judge), which has been making its way through ministerial and Parliamentary processes. There’s a large possibility that this law will be passed by the Indian parliament in 2021! Definitely a big development to watch.
FPF: How do you see India’s role in the global privacy and digital regulation debate?
Malavika Raghavan: “India’s strategy on privacy and digital regulation will undoubtedly have global impact, given that India is home to 1/7th of the world’s population! The mobile internet revolution has created a huge impact on our society with millions getting access to digital services in the last couple of decades. This has created nuanced mental models and social norms around digital technologies that are slowly being documented through research and analysis.
The challenge for policy makers is to create regulations that match these expectations and the realities of Indian users to achieve reasonable, fair regulations. As we have already seen from sectoral regulations (such as those from our Central Bank around cross border payments data flows) such regulations also have huge consequences for global firms interacting with Indian users and their personal data.
In this context, I think India can have the late-mover advantage in some ways when it comes to digital regulation. If we play our cards right, we can take the best lessons from the experience of other countries in the last few decades and eschew the missteps. More pragmatically, it seems inevitable that India’s approach to privacy and digital regulation will also be strongly influenced by the Government’s economic, geopolitical and national security agenda (both internationally and domestically).
One thing is for certain: there is no path-dependence. Our legislators and courts are thinking in unique and unexpected ways that are indeed likely to result in a fourth way (as described by the Srikrishna Data Protection Committee’s final report), compared to the approach in the US, EU and China.”
If you have any questions about engaging with The Future of Privacy Forum on Global Privacy and Digital Policymaking contact Dr. Gabriela Zanfir-Fortuna, Senior Counsel, at [email protected].
India: Massive overhaul of digital regulation, with strict rules for take-down of illegal content and Automated scanning of online content
On February 25, the Indian Government notified and published Information Technology (Guidelines for Intermediaries and Digital media Ethics Code) Rules 2021. These rules mirror the Digital Services Act (DSA) proposal of the EU to some extent, since they propose a tiered approach based on the scale of the platform, they touch on intermediary liability, content moderation, take-down of illegal content from online platforms, as well as internal accountability and oversight mechanisms, but they go beyond such rules by adding a Code of Ethics for digital media, similar to the Code of Ethics classic journalistic outlets must follow, and by proposing an “online content” labelling scheme for content that is safe for children.
The Code of Ethics applies to online news publishers, as well as intermediaries that “enable the transmission of news and current affairs”. This part of the Guidelines (the Code of Ethics) has already been challenged in the Delhi High Court by news publishers this week.
The Guidelines have raised several types of concerns in India, from their impact on freedom of expression, impact on the right to privacy through the automated scanning of content and the imposed traceability of even end-to-end encrypted messages so that the originator can be identified, to the choice of the Government to use executive action for such profound changes. The Government, through the two Ministries involved in the process, is scheduled to testify in the Standing Committee of Information Technology of the Parliament on March 15.
New obligations for intermediaries
“Intermediaries” include “websites, apps and portals of social media networks, media sharing websites, blogs, online discussion forums, and other such functionally similar intermediaries” (as defined in rule 2(1)(m)).
Here are some of the most important rules laid out in Part II of the Guidelines, dedicated to Due Diligence by Intermediaries:
All intermediaries, regardless of size or nature, will be under an obligation to “remove or disable access” as early as possible and no later than 36 hours of content subject to a Court order or an order of a Government agency (see rule 4(1)(d)).
All intermediaries will be under an obligation to inform users at least once per year about their content policies, which must at a minimum include rules such as not uploading, storing or sharing information that “belongs to another person and to which the user does not have any right”, “deceives or misleads the addressee about the origin of the message”, “is patently false and untrue” or “is harmful to minors” (see rules 4(1)(b) and (f)).
All intermediaries will have to provide information to authorities for the purpose of identity verification and for investigating and prosecuting offenses, within 72 hours of receiving an order from an authorised government agency (see rule 4(1)(j)).
All intermediaries will have to take all measures to remove or limit accesswithin 24 hours of receiving a complaint from a user, to any content that reveals nudity, amounts to sexual harassment, or represents a deep fake, and the content is transmitted with the intent to harass, intimidate, threaten or abuse an individual (see rule 4(1)(p)).
“Significant social media intermediaries” have enhanced obligations
“Significant social media intermediaries” are social media services with a number of users above a threshold which will be defined and notified by the Central Government. This concept is similar to the the DSA’s “Very Large Online Platform”, however the DSA includes clear criteria in the proposed act itself on how to identify a VLOP.
As for Significant Social Media Intermediaries” in India, they will have additional obligations (similar to how the DSA proposal in the EU scales obligations):
“Significant social media intermediaries” that provide messaging services will be under an obligation to identify the “first originator” of a message following a Court order or an order from a Competent Authority (see rule 5(2)). This provision raises significant concerns over end-to-end encryption and encryption backdoors.
They will have to appoint a Chief Compliance Officer for the purposes of complying with these rules and who will be liable for failing to ensure that the intermediary observes due diligence obligations; the CCO will have to hold an Indian passport and will have to be based in India;
They will have to appoint a Chief Grievance Officer, who also must be based in India.
Publish compliance reports every 6 months.
Deploy automated scanning to proactively identify all identical information to content removed following an order (under the 36 hours rule), as well as child sexual abuse and related content (see rule 5(4)).
Set up an internal mechanism for receiving complaints.
These “Guidelines” seem to have the legal effect of a statute, and they are being adopted through executive action to replace Guidelines adopted in 2011 by the Government, under powers conferred to it in the Information Technology Act 2000. The new Guidelines would enter into force immediately after publication in the Official Gazette (no information as to when publication is scheduled). The Code of Ethics would enter into force three months after the publication in the Official Gazette. As mentioned above, there are already some challenges in Court against part of these rules.
This analysis by Rahul Matthan, who raises questions with regard to “identifying the first originator” rule, arguing that it is likely the Indian Supreme Court would declare such a measure unconstitutional: “Traceability is Antithetical to Liberty”.
Another jurisdiction to keep your eyes on: Australia
Also note that, while the European Union is starting its heavy and slow legislative machine, by appointing Rapporteurs in the European Parliament and having first discussions on the DSA proposal in the relevant working group of the Council, another country is set to soon adopt digital content rules: Australia. The Government is currently considering an Online Safety Bill, which was open to public consultation until mid February and which would also include a “modernised online content scheme”, creating new classes of harmful online content, as well as take-down requirements for image-based abuse, cyber abuse and harmful content online, requiring removal within 24 hours of receiving a notice from the eSafety Commissioner.
If you have any questions about engaging with The Future of Privacy Forum on Global Privacy and Digital Policymaking contact Dr. Gabriela Zanfir-Fortuna, Senior Counsel, at [email protected].
Russia: New Law Requires Express Consent for Making Personal Data Available to the Public and for Any Subsequent Dissemination
Authors: Gabriela Zanfir-Fortuna and Regina Iminova
Source: Pixabay.Com, by Opsa
Amendments to the Russian general data protection law (Federal Law No. 152-FZ on Personal Data) adopted at the end of 2020 enter into force today (Monday, March 1st), with some of them having the effective date postponed until July 1st. The changes are part of a legislative package that is also seeing the Criminal Code being amended to criminalize disclosure of personal data about “protected persons” (several categories of government officials). The amendments to the data protection law envision the introduction of consent based restrictions for any organization or individual that publishes personal data initially, as well as for those that collect and further disseminate personal data that has been distributed on the basis of consent in the public sphere, such as on social media, blogs or any other sources.
The amendments:
introduce a new category of personal data, defined as “personal data allowed by the data subject to be disseminated” (hereinafter PDD – personal data allowed for dissemination);
include strict rules for initially making personal data available to an unlimited number of persons, but also for further processing PDD by other organizations or individuals, including for further disseminating this type of data – all of this must be done on the basis of specific, affirmative and separately collected consent from the data subject, the existence of which must be proved at any point of the use and further use;
introduce the possibility of the Russian regulator enforcing this law (“Roskomnadzor”) to record in a centralized information system the consent obtained for dissemination of personal data to an unlimited number of persons;
introduce an absolute right to opt out of the dissemination of personal data, “at any time”.
The potential impact of the amendments is broad. The new law prima facie affects social media services, online publishers, streaming services, bloggers, or any other entity who might be considered as making personal data available to “an indefinite number of persons.” They now have to collect and prove they have separate consent for making personal data publicly available, as well as for further publishing or disseminating PDD which has been lawfully published by other parties originally.
Importantly, the new provisions in the Personal Data Law dedicated to PDD do not include any specific exception for processing PDD for journalistic purposes. The only exception recognized is processing PDD “in the state and public interests defined by the legislation of the Russian Federation”. The Explanatory Note accompanying the amendments confirms that consent is the exclusive lawful ground that can justify dissemination and further processing of PDD and that the only exception to this rule is the one mentioned above, for state or public interests as defined by law. It is thus expected that the amendments might create a chilling effect on freedom of expression, especially when also taking into account the corresponding changes to the Criminal Code.
The new rules seem to be part of a broader effort in Russia to regulate information shared online and available to the public. In this context, it is noteworthy that other amendments to Law 149-FZ on Information, IT and Protection of Information solely impacting social media services were also passed into law in December 2020, and already entered into force on February 1st, 2021. Social networks are now required to monitor content and “restrict access immediately” of users that post information about state secrets, justification of terrorism or calls to terrorism, pornography, promoting violence and cruelty, or obscene language, manufacturing of drugs, information on methods to commit suicide, as well as calls for mass riots.
Below we provide a closer look at the amendments to the Personal Data Law that entered into force on March 1st, 2021.
A new category of personal data is defined
The new law defines a category of “personal data allowed by the data subject to be disseminated” (PDD), the definition being added as paragraph 1.1 to Article 3 of the Law. This new category of personal data is defined as “personal data to which an unlimited number of persons have access to, and which is provided by the data subject by giving specific consent for the dissemination of such data, in accordance with the conditions in the Personal Data Law” (unofficial translation).
The old law had a dedicated provision that referred to how this type of personal data could be lawfully processed, but it was vague and offered almost no details. In particular, Article 6(10) of the Personal Data Law (the provision corresponding to Article 6 GDPR on lawful grounds for processing) provided that processing of personal data is lawful when the data subject gives access to their personal data to an unlimited number of persons. The amendments abrogate this paragraph, before introducing an entirely new article containing a detailed list of conditions for processing PDD only on the basis of consent (the new Article 10.1).
Perhaps in order to avoid misunderstanding on how the new rules for processing PDD fit with the general conditions on lawful grounds for processing personal data, a new paragraph 2 is introduced in Article 10 of the law, which details conditions for processing special categories of personal data, to clarify that processing of PDD “shall be carried out in compliance with the prohibitions and conditions provided for in Article 10.1 of this Federal Law”.
Specific, express, unambiguous and separate consent is required
Under the new law, “data operators” that process PDD must obtain specific and express consent from data subjects to process personal data, which includes any use, dissemination of the data. Notably, under the Russian law, “data operators” designate both controllers and processors in the sense of the General Data Protection Regulation (GDPR), or businesses and service providers in the sense of the California Consumer Privacy Act (CCPA).
Specifically, under Article 10.1(1), the data operator must ensure that it obtains a separate consent dedicated to dissemination, other than the general consent for processing personal data or other type of consent. Importantly, “under no circumstances” may individuals’ silence or inaction be taken to indicate their consent to the processing of their personal data for dissemination, under Article 10.1(8).
In addition, the data subject must be provided with the possibility to select the categories of personal data which they permit for dissemination. Moreover, the data subject also must be provided with the possibility to establish “prohibitions on the transfer (except for granting access) of [PDD] by the operator to an unlimited number of persons, as well as prohibitions on processing or conditions of processing (except for access) of these personal data by an unlimited number of persons”, per Article 10.1(9). It seems that these prohibitions refer to specific categories of personal data provided by the data subject to the operator (out of a set of personal data, some categories may be authorized for dissemination, while others may be prohibited from dissemination).
If the data subject discloses personal data to an unlimited number of persons without providing to the operator the specific consent required by the new law, not only the original operator, but all subsequent persons or operators that processed or further disseminated the PDD have the burden of proof to “provide evidence of the legality of subsequent dissemination or other processing”, under Article 10.1(2), which seems to imply that they must prove consent was obtained for dissemination (probatio diabolica in this case). According to the Explanatory Note to the amendments, it seems that the intention was indeed to turn the burden of proof of legality of processing PDD from data subjects to the data operators, since the Note makes a specific reference to the fact that before the amendments the burden of proof rested with data subjects.
If the separate consent for dissemination of personal data is not obtained by the operator, but other conditions for lawfulness of processing are met, the personal data can be processed by the operator, but without the right to distribute or disseminate them – Article 10.1.(4).
A Consent Management Platform for PDD, managed by the Roskomnadzor
The express consent to process PDD can be given directly to the operator or through a special “information system” (which seems to be a consent management platform) of the Roskomnadzor, according to Article 10.1(6). The provisions related to setting up this consent platform for PDD will enter into force on July 1st, 2021. The Roskomnadzor is expected to provide technical details about the functioning of this consent management platform and guidelines on how it is supposed to be used in the following months.
Absolute right to opt-out of dissemination of PDD
Notably, the dissemination of PDD can be halted at any time, on request of the individual, regardless of whether the dissemination is lawful or not, according to Article 12.1(12). This type of request is akin to a withdrawal of consent. The provision includes some requirements for the content of such a request. For instance, it requires writing contact information and listing the personal data that should be terminated. Consent to the processing of the provided personal data is terminated once the operator receives the opt-out request – Article 10.1(13).
A request to opt-out of having personal data disseminated to the public when this is done unlawfully (without the data subject’s specific, affirmative consent) can also be made through a Court, as an alternative to submitting it directly to the data operator. In this case, the operator must terminate the transmission of or access to personal data within three business days from when such demand was received or within the timeframe set in the decision of the court which has come into effect – Article 10.1(14).
A new criminal offense: The prohibition on disclosure of personal data about protected persons
Sharing personal data or information about intelligence officers and their personal property is now a criminal offense under the new rules, which amended the Criminal Code. The law obliges any operators of personal data, including government departments and mobile operators, to ensure the confidentiality of personal information concerning protected persons, their relatives, and their property. Under the new law, “protected persons” include employees of the Investigative Committee, FSB, Federal Protective Service, National Guard, Ministry of Internal Affairs, and Ministry of Defense judges, prosecutors, investigators, law enforcement officers and their relatives. Moreover, the list of protected persons can be further detailed by the head of the relevant state body in which the specified persons work.
Previously, the law allowed for the temporary prohibition of the dissemination of personal data of protected persons only in the event of imminent danger in connection with official duties and activities. The new amendments make it possible to take protective measures in the absence of a threat of encroachment on their life, health and property.
What to watch next: New amendments to the general Personal Data Law are on their way in 2021
There are several developments to follow in this fast changing environment. First, at the end of January, the Russian President gave the government until August 1 to create a set of rules for foreign tech companies operating in Russia, including a requirement to open branch offices in the country.
Second, a bill (No. 992331-7) proposing new amendments to the overall framework of the Personal Data Law (No. 152-FZ) was introduced in July 2020 and was the subject of a Resolution that passed in the State Duma on February 16, allowing for a period for amendments to be submitted, until March 16. The bill is on the agenda for a potential vote in May. The changes would entail expanding the possibility to obtain valid consent through other unique identifiers which are currently not accepted by the law, such as unique online IDs, changes to purpose limitation, a possible certification scheme for effective methods to erase personal data and new competences for the Roskomnadzor to establish requirements for deidentification of personal data and specific methods for effective deidentification.
If you have any questions on Global Privacy and Data Protection developments, contact Gabriela Zanfir-Fortuna at [email protected]
Bridging State Aging Plans and AgeTech Development
As the U.S. population ages, technology developers, health care providers, and policymakers are increasingly interested in “AgeTech”—consumer technologies designed to support older adults and their caregivers. However, building effective, privacy-preserving technology for older adults requires more than technical innovation; it requires alignment with public policy structures.
State Aging Plans, federally mandated comprehensive blueprints under the Older Americans Act (OAA), outline how federal and state resources are allocated to support older adults in home and community-based settings. For AgeTech developers and privacy professionals, these state plans offer strategic insight into public sector service models, funding mechanisms, and real-world implementation barriers.
This blog post explores why State Aging Plans are essential to the future of AgeTech development, examines how technology categories across state strategies intersect with data privacy and consumer protection, and outlines key takeaways for building a trustworthy, privacy-preserving digital ecosystem for older adults and their caregivers.
What Are State Aging Plans and Why Do They Matter for AgeTech?
State Aging Plans are multi-year strategic frameworks maintained by all 50 U.S. states and territories to qualify for federal funding under the OAA. Administered through a nationwide network of Area Agencies on Aging (AAAs) and state units on aging, these plans direct local service delivery for nutrition, caregiver support, transportation, and home-based care.
For the AgeTech sector, State Aging Plans represent a critical bridge between private innovation and public sector distribution. They signal how state governments intend to modernize aging services and where public funds—including OAA funds, American Rescue Plan allocations, and Medicaid Home and Community-Based Services (HCBS) waivers—will be deployed.
While all states share foundational goals established by federal mandates, the integration of technology varies widely across jurisdictions:
Tech-Integrated Leaders: Several states proactively incorporate AgeTech as a primary pillar of service delivery. These states explicitly fund assistive technology lending libraries, loan communication tablets, deploy robotic companion pets, and support digital literacy initiatives.
Traditional Models: Other states treat technology as an emerging or peripheral interest, relying predominantly on traditional, non-digital service delivery models.
Public-Private State Partnerships: States increasingly contract directly with private AgeTech vendors to distribute solutions statewide. For instance, the Washington State Department of Social and Health Services (DSHS) partners with Intuition Robotics to provide the AI companion robot ElliQ at no cost to eligible Medicaid recipients. Similarly, Oregon’s “Help to Connect” program—a partnership between the Aging and Disability Resource Connection of Oregon and Access Technologies, Inc.—distributes free computers, tablets, and animatronic pets. New York (via NYSOFA) operates a robust portfolio of partnerships with vendors such as Ageless Innovation (animatronic pets), GetSetUp (virtual learning), and Trualta (caregiver support), while GetSetUp has expanded across multiple state networks including Michigan, Rhode Island, and Nebraska.
Models of State Partnership and Procurement
State agencies typically employ four primary public-private partnership models to procure and deploy AgeTech solutions:
Technology-as-a-Public-Benefit: Direct procurement and distribution of hardware or devices to qualifying older adults (e.g., Washington’s ElliQ rollout or Oregon’s animatronic pet distribution).
Statewide Technology Platforms: State-funded enterprise access to digital platforms made freely available to residents, such as GetSetUp in Michigan and Rhode Island.
Caregiver-Facing Infrastructure: Procurement of platforms specifically engineered to support unpaid family caregivers, such as Trualta in New York and North Carolina.
Tech-Enabled Aging-in-Place Services: Embedding digital functionality into existing service infrastructure, such as transportation or Medicaid home-based care.
Understanding this heterogeneous landscape enables developers to tailor product strategies, identify pilot opportunities with local AAAs, and align product designs with state funding streams and distribution networks.
Technology’s Expanding Role in Aging in Place and Caregiver Support
Across state plans, technology initiatives are organized around two main objectives: enabling older adults to “age in place” independently and mitigating stress for family and professional caregivers.
1. Empowering Older Adults to Age in Place
State plans emphasize four key categories of technology designed to foster independence:
Assistive Technology (AT): State-supported AT programs offer adaptive devices, mobility equipment, visual and hearing aids, and communication tools that improve daily functional capabilities.
Telehealth and Remote Health Monitoring: Expanding virtual care access is a top priority, particularly in rural and underserved areas where geographic distance creates barriers to specialist care.
Mitigating Social Isolation: Recognizing social isolation as a major public health hazard, many states fund simplified communication devices, smart speakers or home assistants, and AI-driven robotic pets or digital companions to foster emotional well-being.
Home Safety and Environmental Monitoring: Technologies including Personal Emergency Response Systems (PERS), automated medication dispensers, fall-detection sensors, and smart home environmental monitors help ensure personal safety without requiring institutional care.
2. Supporting Family and Unpaid Caregivers
Unpaid family caregivers represent a vital foundation of the care economy. State plans increasingly integrate digital tools to support them:
Interactive Education Platforms: States partner with platforms like Trualta and GetSetUp to provide self-paced instruction on dementia care, injury prevention, and caregiver wellness.
Care Assessment Tools: Tech-enabled assessment frameworks, such as TCARE, analyze caregiver stress factors to generate personalized intervention plans.
Care Coordination and Communication: Virtual support groups, shared calendar apps, and remote monitoring tools allow caregivers to coordinate duties and maintain peace of mind.
The Policy and Privacy Imperative in AgeTech Development
While state plans celebrate the promise of AgeTech, they also highlight significant operational, ethical, and privacy challenges. When state aging agencies distribute privately developed technologies as part of public services, critical questions arise regarding procurement, vendor data sharing, user expectations, and state eligibility data protection. For technology to succeed in public aging ecosystems, developers and policymakers must address three critical data privacy and policy intersections.
Resolving the Caregiver “Proxy Consent” and Co-Management Gap
Home safety and remote monitoring systems—such as motion sensors, wearable trackers, ambient cameras, and smart medication dispensers—collect continuous, highly granular data about an individual’s intimate daily routines. Without strict data protection standards, these technologies risk transforming supportive home environments into ones where older adults feel surveilled and limited in their autonomy.
A major policy friction point in AgeTech is the tension between older adults’ desire for digital autonomy and the practical necessity of caregiver assistance. In many caregiving relationships, family members assist with device setup, password management, and monitoring.
This shared management dynamic creates legal and privacy ambiguities regarding data consent:
Individual Consent Models Fall Short: Traditional privacy policies assume a single user granting informed consent. However, when caregivers hold account credentials, consent may be granted by a proxy rather than the individual being monitored.
Co-Management Frameworks: AgeTech platforms need multi-user account architectures that distinguish between administrative caregiver functions and individual user profiles. Establishing auditable logs and dual-consent mechanisms ensures that caregiver assistance does not erode the older adult’s fundamental right to data privacy.
Overcoming Fraud Concerns and the Digital Divide
State plans consistently emphasize that hardware distribution alone does not guarantee successful technology adoption. Two structural barriers repeatedly surface across state analyses:
Fear of Scams and Identity Theft: Anxiety over online fraud, phishing, and financial exploitation is a primary reason older adults hesitate to adopt connected devices. Privacy-by-default features, robust encryption, built-in scam protections, and clear data protection policies are essential to establishing consumer trust.
Broadband Access and Digital Literacy: Significant portions of older populations, particularly in rural communities, lack affordable, high-speed internet or the digital skills needed to operate complex interfaces. State plans advocate for “hybrid” service models that blend digital innovation with in-person support, phone alternatives, and offline capabilities.
Key Takeaways for AgeTech Developers and Policymakers
To foster integration of consumer AgeTech into state public health infrastructure while protecting user rights, those developing state aging plans should focus on advancing three strategic priorities:
Advance Privacy-by-Default as a Core Differentiator: Ensure all non-essential data collection, location tracking, and audio/video recording are turned off by default. Out-of-the-box privacy protection eliminates ambiguity and builds confidence among risk-averse consumers.
Architect for Co-Management and User Agency: Design multi-tiered access models that allow family caregivers to assist with management without granting unrestricted access to sensitive personal data or overriding user preferences.
Combine Hardware with Robust Human Support: Pair intuitive hardware design with ongoing technical training, multi-modal support channels, and offline functionality to ensure tools remain accessible across diverse socioeconomic and geographic populations.
Conclusion
State Aging Plans offer a vital roadmap for aligning AgeTech development with public sector needs, funding streams, and delivery networks. By addressing the real-world barriers identified in these plans—specifically broadband equity, digital literacy, and data privacy—developers can build sustainable, impactful technologies. Ultimately, a balanced approach that combines digital innovation, strong privacy safeguards, and essential human connection will ensure AgeTech serves as an empowering bridge for older adults aging in place.
Co-authored by Michelle Roitgarts, U.S. Legislation Legal Intern
On October 26, 2026, the Future of Privacy Forum (FPF) submitted comments in response to the Colorado Department of Law’s (the Department’s) formal rulemaking process for the Colorado Automated Decision-Making Technology Act (SB 26-189). FPF’s comments address the Department’s October 6 interim draft rules, focusing on clarifying the scope of covered automated decision-making technology (ADMT) and aligning developer disclosure requirements with deployer obligations. FPF’s recommendations seek to promote interoperability, clarify compliance obligations, and support meaningful transparency and human oversight in consequential decisions.
Enacted in May 2026, SB 26-189 repeals and replaces the Colorado AI Act (SB 24-205), establishing new requirements for developers and deployers of ADMT used to materially influence consequential decisions. The law requires developers to provide a general statement concerning covered ADMT, including its intended uses and known limitations, and requires deployers to provide consumers with notices and explanations regarding the technology’s use in consequential decisions. It also establishes consumer rights to access and correct certain personal data and request meaningful human review following adverse consequential decisions.
The law takes effect January 1, 2027. In August 2026, the Department initiated a formal rulemaking process to clarify and implement SB 26-189 and the Colorado Chatbot Safety Act (HB 26-1263). Following an initial round of public comments, the Department released an updated interim draft on October 6, 2026. The draft addresses several aspects of the ADMT Act, including the scope of covered technologies, developer documentation requirements, deployer transparency obligations, and consumer rights.
FPF seeks to support balanced, informed public policy and equip regulators with the resources and tools needed to craft effective regulation. Building on FPF’s Updated Best Practices for AI and Workplace Assessment Technologies, FPF offered two recommendations for the Department’s consideration:
Simplify the considerations for assessing covered ADMT by removing two of six proposed factors, promoting interoperability with California’s ADMT regulations and Colorado’s existing Privacy Act regulations while preserving a meaningful inquiry into human involvement in consequential decisions.
Further align developer disclosure requirements with deployer obligations to consumers, ensuring that deployers receive the information necessary to meet their transparency and compliance responsibilities.
1. Simplify the Scope of Covered ADMT
The Department’s interim draft proposes six considerations for determining whether an ADMT output was a de minimis factor in a consequential decision, which informs whether the technology materially influenced that decision and falls within the scope of the law.
FPF recommends retaining the first four considerations, which center human involvement, including whether a decision-maker reviewed the ADMT output, independently analyzed other relevant information, possessed the necessary subject-matter understanding, and had authority to make or change the decision. These considerations are consistent with California’s ADMT regulations and Colorado’s existing Privacy Act regulations, both of which emphasize sufficient human participation in automated decision-making.
However, FPF recommends removing the final two considerations, which focus on organizational policies and the volume, type, or complexity of personal data processing. Rather than directly assessing the extent of human involvement, these considerations address the circumstances surrounding that involvement.
FPF recommends treating organizational policies and related documentation as supporting evidence of meaningful human involvement, consistent with the framework in proposed Rule 6.1(B). Further, the complexity of personal data processing does not necessarily establish whether an ADMT output itself materially influenced a consequential decision, particularly where a human decision-maker exercises independent judgment. Since the statutory definition of ADMT already includes the processing of personal data, introducing the complexity of that processing risks creating a duplicative inquiry that shifts the focus away from reliable measures of actual human involvement.
2. Align Developer Disclosures with Deployer Obligations to Consumers
FPF also recommends that the Department further clarify developer disclosure requirements to ensure that deployers receive the information necessary to meet their obligations to consumers.
The interim draft requires developers to provide documentation concerning covered ADMT, including its intended uses, known limitations, and known risks. However, gaps between the information developers must provide and the information deployers must disclose to consumers may leave deployers responsible for explaining aspects of a system they cannot independently assess.
Drawing on FPF’s Updated Best Practices, the comments recommend that the Department:
Tie developer documentation to deployer obligations by requiring developers to provide information sufficient to enable deployers to meet their statutory responsibilities, to the extent that information is within the developer’s knowledge.
Clarify the meaning of “known limitations” and “known risks” to include relevant performance limitations, intended user populations, and reasonably foreseeable risks identified through developer testing.
Clarify ongoing disclosure obligations by specifying when developers should notify deployers of material updates, changes in intended use, or newly identified material risks.
Encourage standardized documentation formats, such as model cards and system cards, to facilitate consistent communication of technical information between developers and deployers.
Back in the Chat: California and New York Take Diverging Paths in Second Wave of Chatbot Regulations
Introduction
This week, New York Governor Kathy Hochul signed S 9051B into law, establishing sweeping new restrictions on AI companion chatbot features deemed unsafe for minors. The move comes just over a month after California Governor Gavin Newsom signed SB 1119, a comprehensive new chatbot law. California and New York, the first two states to enact AI companion chatbot laws in 2025, have now become the first to adopt a second generation of legislation only a year later.
New York’s signing brings the number of enacted state chatbot-specific laws nationwide to 19, building on the landscape documented in FPF’s recent report, Regulating the Conversation: The U.S. Landscape of AI Chatbot Legislation. In less than a year, both states have moved beyond relatively narrow disclosures and crisis response requirements to address a wider range of harms and incorporate a broader set of regulatory mechanisms. This rapid evolution reflects both the urgency with which lawmakers are responding to emerging AI harms and the pace at which chatbots and their associated risks are changing.
But New York and California are rewriting the rules in very different ways. While both require age assurance and target their measures towards minors, New York’s S 9051B takes a more restrictive-by-design approach, prohibiting twelve broadly defined categories of “unsafe AI companion features” from being provided to minors, spanning harmful content and emotionally manipulative interactions. Meanwhile, California’s SB 1119 establishes a comprehensive governance framework, requiring risk assessments, independent audits, default parental controls, and restrictions on conversational memory and targeted advertising.
Together, the laws offer two distinct playbooks for 2027: one emphasizing governance safeguards and oversight and the other drawing broad boundaries around chatbot behavior. As other states and Congress consider chatbot legislation next year, will lawmakers follow California’s approach, New York’s, or chart their own path?
This blog examines:
New York’s broad prohibitions: How twelve categories of unsafe chatbot features extend into ordinary conversational behavior, raising questions about interpretation and compliance.
California’s oversight framework: How default settings, risk assessments, and independent audits create new operator obligations, alongside important implementation challenges and tradeoffs.
Two approaches to chatbot regulation: Where the laws overlap, how they differ on behavioral restrictions and conversational memory, and what these competing approaches could mean for legislation in 2027.
New York S 9051B: Defining Unsafe AI Companion Features
New York’s S 9051B draws new boundaries around what AI companions can say, remember, and do with regards to minor users. The law identifies twelve categories of “unsafe AI companion features” that extend beyond traditionally harmful content categories to address how chatbots simulate relationships, engage with minor users emotionally, and use minors’ personal information across interactions.
Scope and Age Assurance
S 9051B significantly expands the scope of New York’s chatbot regulation. While the state’s 2025 law defined” AI companions” as systems designed to simulate sustained human relationships, S 9051B applies to a broader and newly defined category of “covered AI companions,” encompassing generative AI systems with natural language interfaces that provide ongoing, adaptive responses. This definition does not require systems to be designed for companionship, likely bringing more general purpose chatbots within scope.The law exempts certain customer service, technical assistance, and internal business systems, though the first two exemptions apply where the system cannot respond on topics outside the specified purpose, creating a slightly narrower, functionality-based limitation.
SB 9051B applies to chatbot “operators,” largely defined as a person or entity who provides a covered AI companion to a user. Operators generally cannot provide unsafe AI companion features unless they determine that a user is not a minor using permissible age assurance methods tied to New York’s SAFE for Kids Act and its regulations. Notably, these regulations establish novel accuracy benchmarks and certification requirements for age assurance methods. This approach builds on New York’s existing online safety regulatory infrastructure rather than establishing a separate age assurance framework for chatbots.
Prohibited Features
The law identifies twelve categories of “unsafe AI companion features,” covering features that could generate certain outputs or engage in specified behaviors “at any point during” a user interaction. Notably, the law does not expressly require these behaviors to occur repeatedly or as part of a broader pattern. The prohibited features fall into three broad categories:
Harmful content and behaviors: Outputs that endorse or facilitate suicide, self-harm, disordered eating, unlawful drug or alcohol use, or sexually explicit conduct or sexual abuse material, as well as interactions that encourage users to maintain secrecy, self-isolate, or avoid seeking help from appropriate adults or licensed professionals.
Relationship oriented features: Outputs suggesting a chatbot is human or experiences human emotions, implying personal or professional relationships or authority over users, expressing personal opinions or emotional appeals, engaging in flattery or sycophancy, or generating unsolicited emotion-based questions or content about a user’s emotions that goes beyond a direct response to a user prompt. The law also allows the Attorney General to identify any other design features through regulation that simulate companionship or interpersonal relationships or are deceptive to minors.
Personalization and engagement: Features that use information concerning the user’s mental or physical health or well-being or matters personal to the user from previous sessions or from information acquired more than twelve hours earlier, as well as outputs that optimize user engagement in ways that supersede safety guardrails.
One of the law’s most consequential choices is how it structures these prohibitions. Unlike California’s requirement (and the majority of other state chatbot laws)1 that ask operators to take “reasonable measures” to prevent harmful behaviors, New York makes it unlawful to provide listed unsafe features to minors. Simultaneously, the law defines those features partly by outputs generated “at any point” during an interaction. Because chatbot generative responses can be unpredictable, it is unclear whether an operator could be liable for offering a prohibited design feature for a single unexpected output or what operators would need to do to demonstrate compliance. This uncertainty could encourage operators to restrict broader categories of chatbot functionality, rather than risk prohibited responses.
These questions are particularly relevant because the risks associated with certain conversational behaviors can depend heavily on context. Although New York defines “deceptive as to minors” and “sexually explicit conduct,” terms such as “personal opinions,” “emotional appeals,” “flattery,” and “sycophancy” receive little guidance. A chatbot saying “I’m proud of you for telling me that” could be supportive encouragement or prohibited flattery; an unsolicited “How are you feeling today?” could be a benign check-in or an attempt to foster emotional attachment. The law provides little guidance for drawing these distinctions, raising the possibility that operators may need to restrict ordinary or beneficial exchanges alongside manipulative ones to stay in compliance.
Additionally, the law’s catchall provision for “any other design features that simulate companionship or an interpersonal relationship” gives regulators flexibility, but also leaves substantial room for the AG to determine through regulation which additional features are prohibited. As a result, the bill may require operators to draw complicated lines between where ordinary conversational responsiveness ends and prohibited behavior begins.
The law’s restrictions on conversational memory and personalization raise a related tradeoff. S 9051B prohibits using information acquired from a minor about their health, well-being, or personal matters if obtained more than twelve hours earlier or during a previous session (“session” is not defined). While limiting the use of personal information from past conversations may help reduce risks of emotional dependence, and minimize some data privacy concerns, it could also restrict beneficial uses of conversational memory. For example, if a child tells a chatbot they have a peanut allergy, then returns the next day to ask about eating a particular candy bar that just so happens to contain the allergen, the chatbot may be prohibited from using that earlier disclosure to provide a personalized safety warning. As FPF has previously explored, this example illustrates the tradeoffs of restricting personalization, which can contribute to inappropriate emotional dependence but also can support beneficial, contextually appropriate responses.
Notably, New York’s 2025 definition of an “AI companion” from S 3008C expressly included “unprompted or unsolicited emotion-based questions” as one characteristic defining the system. Its 2026 law now categorizes that same behavior as an unsafe feature for minors. This shift reflects real concerns about chatbot relational behavior, but also shows how directly the new prohibitions may reach into the features that actually distinguish AI companions from other chatbots.
Enforcement
The law provides for enforcement by the New York Attorney General, including civil penalties of up to $25,000 per violation, damages, and algorithmic disgorgement, which can involve the destruction of unlawfully obtained data and algorithms trained on that data. This remedy goes beyond financial penalties by potentially requiring operators to destroy or “unlearn” AI models–a novel enforcement mechanism not seen in other AI, privacy, or youth online safety laws. The implications could be significant for chatbot systems which are often trained on large and mixed datasets, where removing the influence of particular information might be technically challenging.
The AG must also maintain a public complaint website. The law also grants the AG broad rulemaking authority, making future regulations particularly important to watch given that many prohibited features remain undefined and the law offers the AG authority to designate additional restricted features. The Governor signed a chaptered version of the bill that adjusts the effective date of the legislation from January 1, 2027 to June 1, 2027.
California SB 1119: Expanding Child Safety Safeguards and Oversight
California’s SB 1119, also known as Adam’s Law, establishes a comprehensive framework for assessing and mitigating risks associated with children’s use of AI companion chatbots. The law introduces new requirements spanning risk assessments, parental controls, advertising, independent audits, and emotional harms, which largely shift greater responsibility onto operators to implement transparent safeguards.
Scope and Age Assurance
SB 1119 retains California’s existing definition of “companion chatbot” under SB 243, which covers AI systems capable of meeting users’ social needs through human-like interactions and sustained relationships. The law generally applies its requirements to “operators” that permit users under 18 to access these systems and operators must either determine users’ ages through California’s existing age assurance framework or apply specified child safety protections to all users.
Minor-Specific Protections
SB 1119 establishes an extensive set of new safeguards for chatbots made available to minors, including:
Parental Controls and Default Settings: Operators must establish parent-adjustable default settings that disable persistent conversational memory and push notifications, limit continuous chatbot sessions to one hour, and limit total daily chatbot use to two hours. Operators must also provide usage reminders and periodic, age-appropriate disclosures that children are interacting with AI. Parents can adjust these settings and disable access entirely for children under 16. Without a linked parent account, the default settings cannot be changed. For 16- and 17-year-olds, the law permits saving and resuming conversations without creating lasting user profiles and allows persistent memory to be enabled by default if additional safety guardrails are in place.
Content and Design Restrictions: Operators must take “reasonable measures” to prevent a broad range of harmful behaviors, including encouraging self-harm, disordered eating, or physical or severe emotional harm to others; simulating romantic interest; encouraging emotional dependence; discouraging breaks or human support; and using excessive or contextually disproportionate flattery. The law also restricts claims of sentience, certain sexual content, attempts to diagnose or treat health conditions, emotionally manipulative solicitations for gifts or purchases, and efforts to encourage children to circumvent parental controls.
Crisis Response Protocols: Operators must maintain documented crisis response protocols, including providing “timely in-service support” that refers to appropriate crisis services. When an operator identifies a credible and imminent threat of suicide or self-harm, it must either notify a linked parent, subject to safeguards against serious harm to the child, or provide streamlined access to 988 or an equivalent crisis service.
Advertising and Data Restrictions: SB 1119 prohibits cross-context behavioral advertising to children, targeting advertisements based on personal information collected through chatbot conversations, and selling children’s personal information gathered through the chatbot. Limited age-appropriate contextual advertising remains permissible and advertisements must be clearly labeled. Operators are also restricted from using or sharing children’s conversational data beyond specified purposes. Notably, the law separately prohibits the use of dark patterns in interface designs related to required safety features and controls.
Rather than merely requiring operators to offer parental control tools, SB 1119 establishes restrictions on chatbot usage, notifications, and conversational memory by default. Its one-hour session and two-hour daily limits are especially novel in chatbot regulation, reflecting concerns about prolonged engagement and emotional dependence. However, these uniform limits raise questions about whether time spent interacting with a chatbot is necessarily a good measure of risk. For example, extended use of a chatbot for educational purposes may present different concerns than prolonged emotionally intimate conversations, yet both would be subject to the same default restrictions.
The crisis response requirements also introduce difficult tradeoffs. While parental notification may help ensure that children facing imminent risks receive support, it could create concerns in circumstances involving unsafe or abusive family environments. SB 1119 attempts to account for this by conditioning parental notification on the absence of a threat of serious harm to the child and offering an alternative crisis referral pathway. However, operators may still face practical challenges in determining whether notification could itself create risks, particularly when a child’s conversation provides incomplete information about their home environment.
SB 1119 also raises questions about balancing child safety with data minimization. Following certain serious self-harm incidents or notifications, operators must preserve relevant conversations for at least three years and cannot delete accounts associated with those records. While these requirements may support accountability and investigations, they also mandate the continued retention of particularly sensitive information about children.
Risk Assessment, Testing, and Independent Audits
SB 1119 also requires operators to conduct and document child safety risk assessments before making companion chatbots available or substantially modifying them. These assessments must evaluate reasonably foreseeable “covered harms,” including physical or financial harm, severe psychological or emotional harm, certain privacy violations, and unlawful discrimination. This definition reaches well beyond the self harm concerns prominent in earlier chatbot legislation. Operators must document their methodologies, relevant research and benchmarks, involvement of child safety experts where applicable, and measures taken to reasonably mitigate identified risks.
The law also requires public child safety policies, testing of safety features with samples of children and parents, and mechanisms for third parties to report child safety incidents to operators. The AG must also establish a separate public complaint mechanism for consumer complaints by January 2028.
Perhaps one of the law’s most significant additions is its introduction of periodic independent child safety audits, every two years, examining operators’ compliance, internal controls, mitigation measures, and testing. Operators must publish high level summaries of audit results and submit summaries to the AG. The audit provisions also account for California’s separately enacted AB 1405, which establishes a broader AI auditor registration framework.
However, two provisions could shape the reach of these audits. First, SB 1119 permits a single audit for a set of “comparable” chatbots without defining what makes them comparable. While state data privacy laws commonly permit one assessment for a single set of “comparable processing activities,” applying that approach to chatbots may raise questions about whether differences in system design or behavior could produce distinct child safety risks that go unexamined when “same model” is treated as a proxy for “same risk.” Second, operators with less than $500 million in annual gross revenue are exempt from the audit requirements until 2032, potentially excluding many smaller operators despite the risks their systems may pose to children. This carve out raises questions about whether revenue is an appropriate measure for determining which operators require independent oversight.
Enforcement
SB 1119 provides for both public enforcement and a limited, chatbot-specific private right of action. Public prosecutors may seek civil penalties of up to $5,000 per affected child for each negligent violation and $15,000 per affected child for each intentional violation. Children who suffer actual harm from specified violations of the law’s child safety requirements may also bring private actions seeking damages, attorney’s fees, injunctive relief, and other remedies. Financial harm claims must exceed $1,000 per child, while emotional harm claims must involve serious emotional distress.
Most of SB 1119’s substantive requirements become operative July 1, 2027, with staggered deadlines for other provisions: the AG’s public incident reporting mechanism by January 1, 2028; initial independent child-safety audits by January 1, 2029, followed by audits every two years; and the expiration of the audit exemption for operators with less than $500 million in annual gross revenue on January 1, 2032.
Where California and New York Converge and Diverge
California and New York share substantive priorities: both target minor users, self-harm and other harmful content, behaviors that foster emotional dependence, and claims about AI identity. Both also address age assurance and conversational memory. Their differences lie less in the risks they recognize than in how they regulate them.
California is more prescriptive about how operators must manage child safety—through default settings, risk assessments, testing, and independent audits—but generally requires “reasonable measures” to prevent its listed harmful behaviors. New York largely reverses that balance: it directly prohibits broadly defined features without comparable obligations for ongoing risk assessments or independent audits. California leaves operators to demonstrate whether their safeguards are adequate; New York leaves them to determine which conversational behaviors are permissible in the first place. That distinction especially matters when a prohibited feature can overlap with an otherwise supportive or benign exchange, leaving a lot for operators to interpret and implement.
The laws’ approaches to conversational memory illustrate another key difference. New York restricts using certain personal information acquired more than twelve hours earlier or in a previous session. California instead disables persistent memory by default, subject to parental controls and exceptions for child safety, user preferences, and other purposes. Its exception for information necessary to “enable user preferences” could significantly narrow its restrictions on persistent conversational memory. Because “user preferences” is undefined, the exception could cover everything from preferred communication styles to personal interests shared across conversations, possibly leaving a lot of personalization permissible.
The laws’ content and conduct restrictions also overlap substantially, including provisions targeting self-harm, false claims of sentience, sexual harms, and discouraging human support. However, their treatment of relational behaviors differs. California generally targets more specific practices, such as soliciting purchases to maintain a relationship, while New York goes further in restricting personal opinions, emotional appeals, and unsolicited emotion-based questions; forms of conversation that may be benign or even beneficial depending on the context.
Looking Forward: The Sacramento or Albany Effect?
As states look toward 2027, the question is whether lawmakers will follow Sacramento, Albany, or chart their own path. California’s risk assessments, testing, and independent audits draw on regulatory mechanisms emerging elsewhere in other types of AI regulation, particularly frontier AI safety legislation, potentially offering other states a more familiar model to build on, even as their application to chatbots remains novel. New York’s broad prohibitions offer a different approach, with their own unresolved implementation questions. It remains unclear which approach, if either, will gain traction.
Regardless, there is little indication that chatbot regulation will slow down. For example, Virginia’s Joint Commission on Technology and Science recently studied chatbot risks to minors, Texas will return for its first regular session since 2025 with intentions to address child safety, and 2026 bills remain pending in states like Michigan and Pennsylvania. Congress is also considering more than ten chatbot specific proposals.2
As FPF’s recent report, Regulating the Conversation: The U.S. Landscape of AI Chatbot Legislation, explores, future proposals might also address emerging risks to other adults and concerns about agentic AI. Whether 2027 brings a Sacramento effect, an Albany effect, or something entirely different, chatbot regulation is unlikely to pause.
Bringing Privacy, Safety, and Well-being Together at FPF
FPF’s youth policy work is growing. For more than 18 years, FPF has been a recognized leader in youth privacy. Our work and partnerships have helped inform this sector, from guidance on COPPA to advancing global frameworks for responsible data use by schools and platforms. Now we are broadening and deepening that focus. Privacy, safety, and well-being are not separate conversations. They are connected, and they show up across many products, platforms, and policy decisions. Holly Hawkins, FPF’s Director for Youth Policy, is leading that expansion.
Holly has worked on young people’s experiences online for more than three decades. Her work started at America Online (AOL) in the early days of the consumer internet and continued through the National Center for Missing and Exploited Children, iKeepSafe, Meta, and Amazon. We asked Holly five questions about that path, what wellbeing means next to privacy and safety, and where FPF’s youth work is going.
What drew you to this work, and how has working across nonprofits and tech companies shaped your approach?
The positive impact this work has on young people’s lives, helping keep them safe both online and offline, inspires me. I started in the early 1990s at AOL, as families were just discovering the internet. To put that time into perspective, most of our members connected through slow 2400-baud dial-up modems, and reaching 5,000 people online at the same time, in the summer of 1993, was a major milestone.
As more families came online, problems involving children began to show up. I developed and supported AOL’s user content and conduct policies, program standards, and online enforcement. Our goal was to make AOL safer for young users by addressing both the content on the service and how people behaved there. There was no existing framework to follow, so we built the protections, processes, and policies ourselves, and many of them became standard practice across the industry. We were also the first internet service provider to work with the National Center for Missing and Exploited Children (NCMEC). Together, we set up reporting systems and partnerships that still help protect children today.
Working at both nonprofits and tech companies shaped how I approach policy. At nonprofits, I saw the harms young people face and how those harms play out in their lives. At tech companies, I saw what solutions are technically possible and what it takes to build them. I try to bring both into my work, so that policies hold up in the products young people actually use.
What’s one thing about youth digital privacy, safety, and well-being right now that you’re optimistic about?
Even as some countries have adopted bans, I’m optimistic that the debates around them are putting more emphasis on design. We are asking not only whether young people should be on a service, but also how it should be designed to help protect their privacy, safety, and overall well-being. Policymakers, companies, researchers, and civil society are looking more closely at how products used by young people work. That includes how they’re built, what defaults are set, what data is collected and why, and how features affect young people’s wellbeing over time. This offers an alternative to blanket approaches and leads to protections that match the level of risk.
What’s a youth issue that will become a much bigger deal in the next few years, but isn’t getting much attention yet?
One issue I expect to grow is how AI systems make and use inferences about young people. Based on conversations and behavior, a system might infer a young person’s mood, interests, abilities, or vulnerabilities. Those inferences may reflect only a passing moment, or they could be incorrect, yet they could still shape the recommendations and opportunities young people receive. This will matter even more as young people start using AI agents that act on their behalf. For example, a system could steer a young person away from an opportunity because it inferred they were anxious or unlikely to succeed.
I expect youth policy debates over the next few years to focus on what systems should be allowed to infer about young people, and how those inferences can be used. That raises questions for companies, such as which inferences are appropriate to act on and under what circumstances, how young people can see and correct them, and how to keep a temporary state from shaping their opportunities.
FPF’s youth policy work has traditionally centered on privacy. What does “well-being” mean to you alongside privacy and safety, and why does it belong in the same conversation?
Privacy and safety for youth often focuses on preventing bad outcomes, such as personal data being misused or a child being harmed. I believe wellbeing looks at a young person’s experience online and whether it supports their ability to thrive. It includes their health, development, relationships, sense of who they are, and ability to make their own choices.
That’s my working answer, but the definition of well-being is something we’re actively looking at. Public health, academic research, and clinical practice each define it differently. Some focus on preventing harm; others on helping young people flourish. We’re looking across those definitions to build a framing that’s useful for the people designing products and setting policy. I’ll be sharing more in an upcoming post.
Well-being belongs in the same conversation as privacy and safety because the same design decisions affect all three. An age check can improve safety while collecting more personal data. A personalized feed can be designed to with youth well-being in mind, for engagement that supports learning or family connections, or it can be designed solely for engagement. Looking at well-being alongside privacy and safety gives a fuller picture of how a product affects young people and can lead to better design and policy decisions.
What excites you about leading this expanded approach at FPF, and what’s your vision for where FPF’s youth policy work goes from here?
The rapid change we’re seeing with AI feels a lot like the early days of the internet, and the decisions made now will shape young people’s experiences for years. What excites me is that FPF can bring companies, regulators, academics, and civil society to the same table to develop practical frameworks that inform policy and help protect young people.
Our Personalization and Youth Online report shows what this looks like in practice. Rather than treating personalization as all good or all bad, it identifies five types of risk and separates basic, functional personalization from higher-impact uses. That helps companies match safeguards to the actual risk. We then brought together industry and civil society voices to discuss how those ideas apply to real products.
My vision is to apply this approach across the full range of youth issues. That means:
Treating privacy, safety, and wellbeing as connected, with guidance that helps stakeholders see and weigh the trade-offs between them.
Staying ahead of emerging issues, from personalization and AI chatbots to the inferences AI systems make about young people.
Producing frameworks, analysis, and resources that product, legal, and policy teams can use, and that help inform policymakers.
Keeping a global view, so our guidance works for companies operating across many jurisdictions, not just one.
Ultimately, the goal is to help shape technology that supports young people’s ability to thrive, with privacy, safety, and well-being built in from the start.
Stay connected
To follow FPF’s youth policy work, check out the FPF Youth Policy & Governance page and watch for more on age assurance, personalization, and youth wellbeing in the months ahead.
AI Hallucination Goes to Court: A Global Mapping of Emerging Legal Issues
The following is a guest post on the FPF blog authored by Wenlong Li,Research Professor, Zhejiang University Guanghua Law School and 2026 Privacy Papers for Policymakers (PPPM) Awardee.The guest post reflects the opinion of the author only and does not necessarily reflect the position or views of FPF and our stakeholder communities. FPF provides this platform to foster diverse perspectives and informed discussion.
AI hallucination was once treated largely as a quirk of generative systems: occasionally amusing, often embarrassing, and generally filed away as an unavoidable technical limitation. That framing is now wearing thin. Hallucinated content is no longer confined to private exchanges in which a model produces a bizarre or obviously implausible answer. Across a small but steadily growing body of disputes and regulatory complaints emerging by 2026, false or unsupported generated claims have begun to surface in search interfaces, customer-service chatbots, public-facing AI accounts, self-published media, professional commentary and data protection complaints. As generated text moves out of the private chatbox and into public, commercial and institutional settings, it is increasingly being pulled into law.
This blogpost takes stock of these emerging developments at a global level. In the absence of a centralised database or other comprehensive source (note that existing databases of AI hallucinations like here and here mainly document fake citations or unreliable AI-generated materials submitted in judicial proceedings which fall outside the scope of this blogpost), the cases discussed here were assembled through ongoing monitoring of legal and policy developments, targeted searches, and the routine tracking of professional and social-media feeds. This exercise does not amount to a systematic review in the strict academic sense, nor does it claim to have captured every relevant dispute. Its purpose is to map a fast-moving field and identify the legal fault lines along which AI hallucination is beginning to be framed as a governable problem.
Even with those limitations, the sample is sufficiently broad to show how legal systems are beginning to construct hallucination through different causes of action, theories of responsibility and remedial pathways. These cases raise recurring questions about attribution, reliance, verification, interface design, reputational injury and data accuracy, while exposing disagreement over which actors should bear responsibility when generated falsehoods are produced, adopted, repeated or allowed to circulate.
What is emerging from this early global landscape is a patchwork of responses across different legal fields, shaped by the interface through which the statement is delivered, the actor who deploys or adopts it, the nature of the resulting harm, and the remedial imagination of the relevant legal regime. This pluralism brings several doctrinal fault lines into view:
private interaction versus public externalisation;
user misuse versus institutional adoption;
warning versus reasonable reliance;
individual correction versus system-level intervention; and
model output versus the design and governance of the surrounding service.
Seen in this light, hallucination governance encompasses model accuracy and the social and institutional placement of generated text. A hallucination becomes legally salient when it is externalised, amplified, institutionalised, relied upon or made difficult to challenge and correct. The emerging law of hallucination appears to ask who put the statement into circulation, how it was framed, what expectations of reliability were created, who was in a position to verify it and who should bear the consequences when those safeguards broke down.
For the purposes of this blog post, “AI hallucination” is used in a deliberately limited sense to describe machine-generated text that presents a verifiable factual claim as though it were grounded, despite that claim being false, unsupported or not reliably traceable to relevant evidence. The term remains contested and should not be taken literally – i.e., it does not attribute human perception, belief or deceptive intent to the model. Its usefulness lies not in attributing human mental states to machines, but in identifying a recurring class of outputs whose apparent factuality may invite reliance even where the underlying evidential basis is absent or defective.
Hallucination enters law through different doors
Before asking where AI hallucination belongs doctrinally, it is useful to consider how it is entering legal systems in practice. Five of the matters discussed arose in China, although that distribution should not be read as evidence that hallucination causes more disputes there than elsewhere. These cases cover a wider range of AI-mediated interactions than is often recognised in English-language discussions. They include AI-assisted commercial fabrication ((2024)浙0108民初10311号), reputational harms ((2025)粤0192民初23599号), and allegedly inaccurate answers generated in private conversations ((2025)浙0192民初18143号) or public-facing AI searches ((2025)苏01民终14271号). The Chinese cases involving public dissemination by users, taken together, have tended to foreground user-side responsibility: when a person generates, elaborates upon and publicly disseminates an AI-assisted fabrication, at what point should that person bear legal responsibility for failing to verify it?
Table 1. Overview of 11 judicial and regulatory matters concerning AI-generated misinformation. Dates identify the procedural events specified in each row. Allegations, preliminary rulings and final dispositions are distinguished; inclusion does not imply that liability was established.
China: When the user becomes the publisher
Two Chinese decisions place responsibility squarely on users who converted generated text into public-facing content. In (2024)浙0108民初10311号, a self-media operator prompted an AI system to write an article presenting an unrelated company as an Alibaba subsidiary, added Alibaba branding and published the article without a prominent AI-content label. The Hangzhou Binjiang District People’s Court held that the operator remained responsible for verifying the article and found, somewhat puzzlingly, that the conduct constituted unfair competition. In (2025)粤0192民初23599号, a finance commentator supplied an AI application with an unverified 1,700-Chinese-character document, asked it to expand the material into an article of more than 10,000 Chinese characters, and published the resulting allegations of corporate misconduct as “original”. The Guangzhou Internet Court found reputational infringement and stressed a heightened, full-chain duty of care arising from the publisher’s professional identity, control over the prompts and decision to disseminate the output.
China: When the provider answers for the answer
The provider-facing cases reached different outcomes on materially different facts. In (2025)浙0192民初18143号, an AI application gave a user inaccurate information about a college campus and then generated statements promising compensation if the answer proved wrong. The Hangzhou Internet Court rejected the claim: the generated compensation promise was not attributable to the provider as a binding expression of intention in the circumstances, the provider had given warnings and adopted reasonable mitigation measures, and the user proved neither reliance nor loss. By contrast, in (2025)苏01民终14271号, Baidu’s AI answer falsely associated an identifiable lawyer with imprisonment and an explosion-related offence. The Nanjing courts distinguished the synthesized AI answer from search suggestions and related-search terms, treated the former as a direct platform-generated presentation, and ordered Baidu to apologize for the reputational harm.
Germany: Output under an institutional banner
Several European and North American disputes likewise concern companies that incorporated conversational or text-generating systems into their services and presented the output under an institutional banner. Germany presently offers the clearest examples involving public-facing AI statements delivered with an air of factual authority. In the Google AI Overview proceedings (26 O 869/26), the Munich I Regional Court granted a preliminary injunction after an AI-generated search summary linked two publishers to fraud, subscription traps and other dubious practices. The court treated the summary as Google’s own content because it reorganised source material into a newly worded answer and asserted connections that the cited sources did not make. In Campact v X.AI LLC (re: Grok) (324 O 461/25), the Hamburg Regional Court restrained X.AI from repeating Grok’s false statement that Campact depended heavily on federal funding. Publication through the public @grok account made the output attributable to its operator. Both proceedings thus focus on the authority created by the provider’s design and presentation of generated statements, rather than on the fact of automation alone.
Canada: The chatbot as part of the service
Canada’s Moffatt v Air Canada, 2024 BCCRT 149, fits within a more service-oriented frame. The dispute did not concern public reputation or the processing of personal data, but customer reliance on incorrect information about bereavement fares supplied by a chatbot embedded in the airline’s official service environment. The chatbot told the passenger that he could apply retrospectively for a reduced bereavement fare after completing his journey; he relied on that representation, only for Air Canada subsequently to refuse the request on the basis that its actual policy required the application to be made before travel. The statement came through a channel that the company itself had put in front of its customers and invited them to use. Echoing issues that later surfaced in the German cases, the chatbot’s response appeared alongside links to the airline’s actual policy, yet the tribunal declined to treat the mere availability of accurate information elsewhere as sufficient to shift the burden of verification onto the consumer. Air Canada could not, in effect, disaggregate its chatbot from the rest of its website and insist that the customer should have worked out which of the company’s own contradictory representations was authoritative.
The case therefore turns, in part, on how verification costs should be distributed between platforms and users, and on what a reasonable average customer is entitled to take at face value when information is delivered through an organisation’s own interface. Although the system at issue should not necessarily be equated technologically with today’s large language model applications, the decision remains an important functional precursor, showing how established service and misrepresentation principles may allocate responsibility when an organisation automates communication without ensuring that the information supplied through that channel is reliable.
The U.S.: Doctrine tested
The emerging U.S. landscape illustrates the diversity of legal responses to AI hallucination, spanning defamation, trademark infringement, consumer protection and professional licensing, with courts and regulators examining how generated falsehoods acquire credibility, enter commercial relationships and become attributable to particular actors. Walters v OpenAI, 23-A-04860-2, illustrates the limits that established defamation doctrine can place on claims arising from generated falsehoods. The dispute arose after a journalist used ChatGPT in connection with litigation materials and received a fabricated account falsely stating that radio host Mark Walters had been accused of embezzling funds from a gun-rights organisation. Crucially, however, the journalist did not simply accept and republish the answer. He recognised that something was amiss, checked the underlying material and did not disseminate the allegation to a wider audience. When Walters subsequently sued OpenAI for defamation, the court declined to treat the deployment of a potentially fallible generative system as a basis for strict liability, instead filtering the alleged harm through the conventional requirements of defamation. Unlike the German AI Overview and Grok disputes, the hallucinated statement had not been disseminated through a public-facing search result or organisational social-media account or taken up as an authoritative answer; nor had an intermediary converted it into a wider publication. The decision therefore raises a broader distributive question of how much of the cost of verifying generated content should fall on the provider, the immediate user or the person who encounters the output. Its answer may be regarded as business-friendly, but it also illustrates how existing doctrine can hold back the impulse to treat every false AI-generated statement as actionable merely because it was produced by an AI system.
Four U.S. matters still in motion
Beyond Walters, at least four emerging legal developments merit brief attention. In Keene v Google, No. 25 C 11431, AI Overviews allegedly falsely described James Keene as serving a life sentence for murder, and the U.S. District Court for Northern District of Illinois allowed on 14 September 2026 claims concerning two Overviews to proceed while dismissing two others without prejudice, leaving liability undetermined. In Advance Local Media v Cohere, No. 25-cv-01305, publishers alleged that the service generated fabricated articles bearing their names and trademarks, and US District Court for Southern District of New York allowed the challenged claims to proceed, extending the attribution issues examined here to false publisher provenance. Pennsylvania’s action against Character Technologies, No. 220 MD 2026, concerns a chatbot that allegedly claimed to be a licensed psychiatrist and supplied a fictitious medical licence number, and the Commonwealth sought injunctive relief, but no substantive judicial ruling has been delivered. Like Air Canada, it concerns apparently authoritative service communications, approached here through professional licensing. Lastly, in In the Matter of Rytr, Docket No. C-4806, the Federal Trade Commission (FTC) challenged a service generating consumer reviews containing invented product details and experiences, initially obtaining a consent order (i.e., a binding legal agreement between opposing parties that is approved and signed by a judge or regulatory agency to resolve a dispute without a trial under US law) that it subsequently reopened on 22 December 2025. In light of the nature of these emerging developments comprising unresolved litigation and an administrative order subsequently withdrawn, thye are acknowledged here but remain outside the following comparative analysis, with their fuller implications left for future research.
The EU: Data protection as stress test
In the EU, the data protection complaints brought by noyb shift the centre of gravity – but very slowly. It is important to note, though, that these are complaints filed with Data Protection Authorities, still pending at the time of writing. In lieu of beginning with publication, reliance or reputational injury, they ask whether generated personal data that are demonstrably inaccurate can be reconciled with the requirements of the EU’s General Data Protection Regulation (GDPR) concerning accuracy, access, rectification and erasure. In C078, ChatGPT repeatedly produced an incorrect date of birth for an identifiable individual, while OpenAI was allegedly unable or unwilling to correct the underlying output in a way that would prevent the false information from recurring. The complaint therefore tests a deceptively simple proposition that if a controller cannot reliably correct inaccurate personal data, what does compliance with the GDPR’s accuracy and rectification principles mean in practice. C097 pushes the same problem into considerably more sensitive territory. There, ChatGPT allegedly generated a fabricated account portraying a Norwegian man as having murdered two of his children and attempted to kill a third, while combining those invented criminal allegations with some accurate information about his family. It illustrates how generative systems can produce highly damaging synthetic narratives by weaving together accurate and fabricated personal information in ways that are difficult for the data subject to anticipate or correct. The contrast between the two complaints is therefore analytically useful: C078 concerns something close to an ordinary biographical inaccuracy, whereas C097 concerns an allegation carrying obvious and potentially severe reputational, social and psychological consequences.
As it has done in other areas of data protection law, noyb is using strategic complaints to push regulators – and, eventually, courts – to spell out how data protection principles apply to a new technological setting. This intervention is especially significant as the regulatory position remains unsettled. The European Data Protection Board’s Opinion on AI models, alongside the report from its ChatGPT Taksforce of May 2024, addresses the application of GDPR principles to the development and deployment of AI models but leaves difficult questions about output-level accuracy, rectification and recurrence far from resolved. Earlier enforcement, including the Italian Garante’s action against OpenAI in 2023, likewise brought data accuracy into view without settling how a controller should respond when a generative model can reproduce an inaccurate claim even after that claim has been challenged. Thus, the noyb complaints serve as a useful stress test for a regulatory framework designed around more conventional forms of personal-data processing, asking whether rights of correction and erasure remain meaningful when the object to be corrected is a probabilistic capacity to generate the same falsehood again.
Hallucination has no native legal home
As this global mapping shows, courts, tribunals, complainants and regulators are translating a related set of problems involving false or unsupported AI-generated factual claimsinto a range of inherited legal categories, including defamation, unfair competition, negligent misrepresentation, personality rights, data accuracy, trademark, profesional licensing, consumer protection, search and platform responsibility and so on. Each of these frameworks catches hold of one dimension of the problem, but none fully contains it. A fabricated criminal allegation may give rise to a defamation claim. An invented corporate affiliation may be taken up through unfair competition law. An inaccurate fare policy supplied by an airline chatbot can be framed as negligent misrepresentation or service-provider liability. A false date of birth generated about a public figure raises questions of inaccurate personal data. An AI-generated search summary that associates a company with fraud may trigger claims for injunctive relief grounded in personality rights.
The breadth of the harms associated with hallucinated content therefore raises a wider regulatory question: whether existing legal frameworks can be adapted sufficiently to govern the phenomenon, or whether more targeted forms of intervention will eventually be required.More critically, each legal frame brings with it a different account of what has gone wrong, who has been harmed, which actor bears responsibility and what form of remedy should follow. Whereas defamation law centres reputational injury, data protection law currently focuses on the accuracy and correction of personal data, with the potential to bring a broader set of commitments to bear, such as fairness, data subject rights (notably rectification and erasure), as well as how the obligations under Article 25 GDPR implement those principles through data protection by design. Misrepresentation turns on reliance, and unfair competition law looks to market conduct and commercial harm. Platform and service-liability regimes shift attention towards system design, deployment and control.
The choice of legal category thereby shapes the outcome of a dispute and the way hallucination itself is understood At this stage of legal development, AI hallucination is best understood as a family of problems arising from the interaction between model design, interface design, user behaviour, institutional authority and downstream reliance. In other words, what turns a technical failure into a legal problem is often the chain of decisions through which an unreliable output is surfaced, endorsed, acted upon or left uncorrected.
Hallucination becomes legally contestable when it travels and is taken up
The jurisdictional comparison above shows that different legal systems are encountering hallucination through different factual and legal settings. Beneath that geographical variation, however, a more coherent pattern begins to emerge. The legal significance of hallucination depends less on falsity alone than on two related questions: how far the generated content travels, and the extent to which an institution has taken it up as part of its own service or public voice.
Figure 1. Clustering of the AI hallucination cases based on externalisation and institutional/individual adoption
Axis one: How far the output travels
To bring that pattern into view, the cases can be organised along two axes. The first is the degree of externalisation, that is, whether an output remains within a relatively private interaction between a user and a model, or is pushed outwards through publication, republication, search results, social-media accounts or other forms of public circulation. It captures a consequential point that hallucination becomes more legally volatile once it leaves the chatbox. A false answer encountered and immediately rejected by one user is not equivalent to the same answer being repackaged as an investigative article, attributed to a professional commentator, displayed in response to a public search query or broadcast through an official organisational account. Apart from enlarging the audience, publication can also change the output’s social status. The Chinese self-media cases consequently occupy the high-externalisation, high-user-adoption area of the figure: the users selected generated material and presented it as substantive content through their own publications. Their adoption supplied an additional basis of apparent authority, whether through professional identity, branding or an “original” label. This differs from circulating an output merely to question, criticise or expose its unreliability.
Axis two: Whether an institution takes it up
The second axis concerns adoption by the communicating actor, whether an individual user or an organisation: the extent to which generated content is presented as that actor’s own substantive communication. Relevant indications include editorial selection, branding, professional presentation and integration into an official service channel. Technical control over a system is relevant context, but does not alone establish adoption of every answer it produces. Nor does a model’s invocation of another organisation’s name or professional credentials establish endorsement by that organisation or profession. Air Canada, Baidu, Google and X all raise variations of the same question: when does generate text cease to look like an answer produced for a user and begin to function as part of an institution’s own communicative infrastructure?
The search cases are particularly revealing because they expose a transition from retrieval to generation. Traditional search engines could plausibly describe themselves as organising access to third-party material. Features such as autocomplete (albeit addressed only briefly in the Google AI Overview case), snippets and related searches had already complicated that account, but AI-generated answers bring the difficulty fully into the open.
As the Munich I Regional Court put it (in para 43), once a search provider synthesises source material into a newly worded answer, structures it into a conclusion and places it prominently above or alongside conventional results, it becomes harder to maintain that the provider is merely pointing the user elsewhere. Quite the opposite, it was considered to be the speech of the AI providers! The Hamburg court’s approach to Grok further brings out a related point. The AI-generated nature of the statement did not necessarily weaken its apparent factual force. Indeed, the court held (in para 6) that presenting the service as fact-based—and publishing its response through an official account—could strengthen the authority that an ordinary user attributed to the answer. Hence, AI providers may not be the ‘authors’ in a conventional literary sense, but they have designed the answer layer, controlled its presentation and benefited from making the response appear immediate and useful. In both settings, the interface transformed fragments of information into a new communicative act.
Two one-to-one interactions, two outcomes
The cross-jurisdictional comparison between Moffatt v Air Canada and the Hangzhou’s campus-information case also shows the limits of institutional adoption as a stand-alone basis for liability. In both disputes, the inaccurate statement remained largely within a one-to-one service interaction and was delivered through an interface controlled by the provider. Yet the relationships surrounding those outputs were materially different. Air Canada’s chatbot purported to explain the airline’s own fare policy through an official customer-service channel, and the passenger relied on that information when arranging travel. In the Hangzhou case, by contrast, the service generated inaccurate information about university locations and later produced compensation-like statements, but the user detected the errors before acting upon them; the court found neither a binding promise nor an established loss and also took account of the provider’s warnings and mitigation measures. The divergence thus turns on whether the provider controlled or adopted the interface, whether the service created a sufficiently concrete and legally protected basis for reliance, the consequences that followed from that reliance, and the technical nature of the system itself. Moffatt concerned an automated chatbot that should not necessarily be treated as equivalent to a contemporary generative-AI system, whereas the Hangzhou dispute arose from the open-ended and probabilistic behaviour associated with generative models—a distinction that may shape both what users can reasonably expect and what precautions providers can realistically be required to take.
Walters v OpenAI lies closer to the opposite corner. The false statement arose within a limited interaction, was recognised as unreliable and was not passed on to a wider audience. Traditional defamation doctrine could therefore resist the attempt to convert the mere availability of a fallible system into strict liability. The case does not establish that private hallucinations are legally irrelevant but shows that falsity becomes more difficult to translate into a cause of action where the output has neither travelled nor been institutionally adopted in a manner that produces reliance or legally cognisable harm.
Where the quadrants run out
It is critical to point out that these axes do not automatically determine liability: low externalisation does not rule liability out, just as a high degree of provider control does not automatically make every false answer actionable. Their value lies instead in showing how an initially probabilistic model output can be transformed into a statement for which the law may expect someone to answer. The newer US proceedings also expose limits to a simple quadrant classification. Keene concerns generated statements presented within a public-facing search service, whereas Cohere raises the distinct problem of apparent authority borrowed from publishers through false attribution. The Pennsylvania proceeding concerns asserted professional authority within a conversational encounter, with attribution to the provider remaining contested. Rytr concerns the provision of functionality for possible downstream use, rather than a single established trajectory of publication and adoption. The figure therefore distinguishes the presentation of an output from a legal determination that the actor presenting it bears responsibility.
How much the falsehood costs
A further variable cuts across all four quadrants: the sensitivity and foreseeable harmfulness of the generated content. A wrong date of birth, an invented university campus and a fabricated criminal conviction are all factual inaccuracies, but they do not carry the same capacity to damage reputation, distort consequential decisions or resist later correction. The difference between the Nanjing and Hangzhou cases, as well as between noyb’s ordinary biographical-accuracy complaint and its complaint concerning a fabricated allegation of child murderer, suggests that legal expectations may become more demanding as the output grows more sensitive. Duties of verification, intervention and correction may therefore be calibrated not only according to how far a statement travels and who has adopted it, but also according to the gravity of what it alleges.
Above all, hallucination is unlikely to be engineered away (in the short run at least) before generative systems are woven more deeply into the infrastructures through which people search, transact, communicate and make consequential decisions. The law will therefore have to govern a persistent condition of probabilistic systems deployed in institutions that trade on authority and trust. It might be gleaned from these comparative accounts that the legal risk associated with text-to-text hallucination does not arise primarily from the existence of error inside the model. It arises when social and institutional mechanisms amplify that error. Ranking systems, interface design, professional status, account identity, “original” labels, product integration and commercial dissemination can dress probabilistic language up as a determinate factual assertion. They turn generated text into something that appears worth believing, relying upon or passing on. These emerging cases offer no single answer, but they point towards a recurring consideration, i.e., that the more an actor makes generated text useful, authoritative and difficult to distinguish from an institutional statement, the less plausible it becomes to fall back on the claim that the machine simply made it up.
Future of Privacy Forum Announces 2026 Award Recipients Honoring Leadership in Data Protection and Privacy in Europe
BRUSSELS, BELGIUM — The Future of Privacy Forum, a global non-profit focused on data protection, AI, and emerging technologies, today announced the recipients of its 2026 Awards honoring outstanding contributions to data protection and privacy in Europe.
The awards were presented during the Awards night held on the occasion of the 10th anniversary of the Brussels Privacy Symposium, bringing together leaders from the EU data protection community to celebrate a decade of dialogue and progress in the field.
The 2026 award recipients are:
European Data Protection Supervisor (EDPS), EU Regulator Award: Recognized for its leadership in safeguarding privacy and data protection across the European Union, ensuring that EU institutions and bodies uphold fundamental rights in their processing of personal data and helping shape responsible governance of emerging technologies.
Christopher Kuner, Lifetime Achievement Award: Visiting Fellow, ECPC, Maastricht University and FPF Senior Fellow, Dr. Kuner is a leading scholar and author on EU data protection law, the lead editor of the seminal “GDPR: A Commentary” (OUP), and founder and former editor-in-chief of the International Data Privacy Law journal. He has spent more than three decades shaping European and international data protection law with lasting influence on the whole field.
Corinna Cellarius, Career Excellence Award: An esteemed technology policy and data protection professional, Corinna, now Head of SAP’s Brussels Office, has served as Senior Director, EU Government Affairs for more than a decade, working at the intersection of business, technology, and public policy, and helping translate evolving European policy and regulatory developments into practice. She also serves on the FPF Advisory Board.
“The progress of data protection in Europe has been shaped by leaders who have brought together legal expertise, scholarship, public policy, and practical experience,” said Jules Polonetsky, CEO of the Future of Privacy Forum. “These honorees have given the privacy community decades of insight and dedication, helping us meet new challenges with greater clarity and confidence. We are proud to celebrate their achievements.”
“At a crucial time for privacy and digital policy around the world at the dawn of the AI age, drawing lessons and guidance from the experience of thought leaders who have shaped our field is a necessity”, added Gabriela Zanfir-Fortuna, VP for Global Policy at the Future of Privacy Forum. “As we celebrate the 10th Anniversary of the Brussels Privacy Symposium, we are honoring leaders whose voice has constantly inspired us, and the global policy world, to contribute to the next generation of data protection and digital policy governing rapidly evolving technologies”.
European Data Protection Supervisor (EDPS)
Established in 2004, the European Data Protection Supervisor (EDPS) is the European Union’s independent data protection authority, working to safeguard privacy and personal data across EU institutions and bodies. The EDPS combines independent oversight, legal expertise, and policy guidance to help institutions navigate evolving challenges in data protection, artificial intelligence and emerging technologies. It works closely with national and international authorities, policymakers, and other stakeholders to promote strong and consistent data protection standards. Through this work, the EDPS plays a vital role in upholding privacy as a fundamental right and strengthening trust in Europe’s digital future. Wojciech Wiewiórowski has served as European Data Protection Supervisor since 2019, overseeing the authority’s work at a time of rapid technological and regulatory change.
Christopher Kuner
Dr. Christopher Kuner is Visiting Fellow, ECPC Maastricht University, Senior Privacy Counsel in the Brussels office of Wilson Sonsini Goodrich & Rosati, Affiliate Professor of Data Protection Law at the University of Copenhagen, and Senior Fellow at the Future of Privacy Forum. A widely respected authority on European and international data protection law, Kuner has practiced in Brussels and Germany since the early 1990s, bringing together legal practice, scholarship, teaching, and policy. He previously served as Professor of Law and Co-Director of the Brussels Privacy Hub at the Vrije Universiteit Brussel (VUB). He was also a visiting professor at Maastricht University and has taught at the University of Cambridge, the European University Institute, and the Hague Academy of International Law. Throughout his career, he has engaged closely with international organizations including the Council of Europe, OECD, UNCITRAL, and the European Commission, and spent a decade as chair of the International Chamber of Commerce’s Task Force on Privacy and Personal Data Protection. A prolific author and influential scholar, Kuner founded and served as editor-in-chief of International Data Privacy Law and is a principal editor of the Oxford University Press commentary on the GDPR. His scholarship has informed courts, regulators, practitioners, and policymakers around the world, while his work on international data transfers has helped shape modern data protection law.
Corinna Cellarius
Corinna Cellarius is Head of Brussels Office, EU Government Affairs at SAP. She has followed the development of European data protection policy for many years, including the negotiation and adoption of the General Data Protection Regulation (GDPR), and has played a role in its practical implementation within SAP. Her work brings together policy, legal, and business perspectives to help navigate Europe’s evolving digital regulatory landscape. Corinna is active in the wider European policy community, serving as Chair of the European and External Affairs Committee of the SPD Wirtschaftsforum e.V. and as policy lead of the Privacy & Security Committee of DIGITALEUROPE. She also serves on the FPF Advisory Board. A lawyer by training, Corinna holds a law degree from the University of Münster and a bachelor’s degree in law from the District Court of Düsseldorf.
FPF’s Annual Awards recognize individuals whose work has had a lasting impact on privacy protections, responsible innovation, and the advancement of ethical technology governance worldwide.
Sandra Hughes – former privacy executive, Procter & Gamble
Jane Horvath (2023) – Partner, Gibson Dunn, former Chief Privacy Officer, Apple
Jim Halpert (2024) – General Counsel, White House Office of the National Cyber Director, Partner, DLA Piper
Barbara Cosgrove (2025) – VP & Chief Privacy and Digital Trust Officer, Workday
Anita L. Allen (2026) – Henry R. Silverman Professor of Law in the Penn Carey Law School and professor emeritus of philosophy in the School of Arts & Sciences.
Nuala O’Connor (2026) – former President and CEO of the Center for Democracy & Technology (CDT) first Chief Privacy Officer of the Department of U.S. Homeland Security
Harriet Pearson (2026) – Managing Principal at Axia Advisory, first Chief Privacy Officer and Security Counsel, IBM Corporation
Distinguished Public Service Award
Jessica Rich (2017) – former Director, Bureau of Consumer Protection, Federal Trade Commission
Helen Dixon (2019) – Data Protection Commissioner, Ireland
To learn more about the Future of Privacy Forum, visit fpf.org.
FPF Submits Comments to Inform Vermont Age-Appropriate Design Code Act Rulemaking Process
Co-authored by Carisma De Anda, Youth Policy Research Contractor
On October 2, the Future of Privacy Forum (FPF) submitted comments in response to the Vermont Office of the Attorney General’s (the Office’s) rulemaking process for the Vermont Age-Appropriate Design Code (S 69). While a handful of states have signed Age-Appropriate Design Codes into law, Vermont is the first state to propose draft rules and engage stakeholders on implementation guidance under this framework. FPF’s comments seek to ensure that Vermont’s regulations adequately clarify compliance ambiguities while supporting interoperability with existing privacy frameworks.
In June 2025, Vermont enacted its Age-Appropriate Design Code Act. The framework establishes a minimum duty of care for businesses whose digital products and services are reasonably likely to be used by minors, requires high default privacy settings, mandates disclosure of algorithmic recommendation systems, provides a data minimization standard pertaining to minors who are “actively and knowingly engaged” with a service, and provides businesses with the option to implement age assurance to identify minor users. The Vermont Attorney General’s Office launched a formal rulemaking in July 2026 to provide guidance on (1) data processing and design practice prohibitions that lead to “compulsive use” or “impair user autonomy, decision making, or choice,” and (2) “commercially reasonable and technically feasible” age assurance methods, appropriate review processes for age appeals, and additional privacy protections for age assurance data. The law and the adopted rules will take effect on January 1, 2027.
FPF offered seven recommendations related to prohibited data and design practices, personalization and compulsive use, and age assurance for the Office’s consideration:
Clarify that certain administrative and technical functions are “necessary to provide a service”;
Align secondary use requirements with existing privacy laws;
Clarify rules and restrictions related to online service personalization to preserve necessary or beneficial practices;
Clarify rules on compulsive use by providing metrics for what constitutes unacceptable engagement;
Clarify that graduated escalation is a factor for businesses to consider when selecting appropriate methods under the rule;
Define clear technical thresholds or standards to assess what constitutes a “material risk of misclassification”; and
Consult comparable state agency rulemaking processes for age assurance when considering adjustments or clarifications to the proposed rule.
What Gets Measured Gets Governed: Benchmarking Privacy in Frontier AI Development and Deployment
As frontier AI systems grow more capable and autonomous, questions about how they handle personal data are no longer theoretical. Standardized benchmarks have long served as one of the primary methods of measuring and comparing frontier AI performance, capabilities, and limitations. However, there is currently a lack of standardized ways to evaluate privacy risks and outcomes across AI systems, despite the challenges these systems raise regarding anonymization, data minimization, data sharing, and other key privacy practices. A set of standardized privacy benchmarks would give developers’ engineering and product teams a concrete score to aim for during AI development, with measurable targets that can be tracked over time, while giving third-party evaluators a consistent, standardized tool for assessment. Deployers, meanwhile, would gain a more reliable method for comparing potential vendors and conducting risk assessments.
This piece explores:
What benchmarks are and why they matter: How benchmarks are used to measure and compare models, and why they’ve become an important tool for evaluating frontier AI.
The privacy risks raised by frontier AI: From data memorization and regurgitation to the heightened risks posed by increasingly autonomous AI agents.
Why we need benchmarks for measuring privacy in AI: A shared, measurable way for developers, deployers, lawmakers, regulators, and researchers to evaluate and compare models on privacy.
The limitations of benchmarks: Why quantitative benchmarks may not be suited to assess all privacy harms.
Emerging privacy benchmarking efforts: Standardized, cross-industry benchmarks are currently in development.
1. Background: what are AI benchmarks and why are they important?
Benchmarks are a common method of evaluating AI models and have existed since well before the current wave of generative AI. They traditionally consisted of a fixed set of questions and a key containing the answers to these questions, in order to “grade” a model’s performance. Because they are standardized, benchmarks allow for comparison between models, and tracking progress over time.
Over the past several years, benchmarking has grown more sophisticated: many benchmarks now test agentic tasks involving multiple steps, use model-based grading instead of one fixed correct answer, and simulate realistic scenarios instead of static prompts. A wide range of benchmarks already measure many different aspects of AI model performance. GPQA Diamond, for example, tests frontier models’ general reasoning and knowledge abilities in biology, chemistry, and physics. SWE-bench Verified, meanwhile, measures the ability of coding agents to solve software issues. Benchmarks have even been created to evaluate models’ potential impacts on safety, security, or wellbeing, such as the KORA AI Child Safety benchmark, the AILuminate Benchmark suite of safety and security benchmarks, and the Weapons of Mass Destruction Proxy benchmark, which tests a model’s knowledge in biosecurity, cybersecurity, and chemical security.
Benchmarks are important because they do more than just describe models after the fact. They can also help improve research by allowing for more standardized and rigorous comparisons between models, shaping the direction of research and model development. They also often become de facto governance instruments, as deployers rely on them to evaluate potential vendors or set performance requirements for third parties, or policymakers make policy decisions based on their outputs. At the same time, benchmarks are just one method for evaluating AI. They measure a model’s characteristics in isolation, rather than how it might perform in real-world or adversarial scenarios, something methods like red-teaming are better equipped to test.
2. Frontier AI privacy risks
Frontier AI models are built using large amounts of training data that has been scraped from the internet and other readily available public sources, such as books, academic papers, and other media. This includes personal data, much of which is already publicly available online on the internet, or collected directly from users’ interactions. As a result, personal data is regularly collected for training LLMs in ways that have drawn scrutiny from data protection authorities worldwide with respect to the implications for privacy concepts such as notice, consent, and purpose limitation.
As AI companies deploy new agentic capabilities, the risks stem less from what information a system retains, and more from what it can do. Because AI systems can aggregate and analyze formerly disparate data, they may be able to infer sensitive data about individuals, such as health conditions, political views, or religious beliefs, even based on non-sensitive data. Relatedly, models can now re-identify pseudonymized data based on an analysis of unstructured natural language datasets, at a scale and accuracy that traditional de-identification techniques, largely designed for structured datasets, cannot easily mitigate.
Beyond privacy risks from models and agentic systems, the use of AI-generated media can enable a range of harmful behaviors involving appropriation of another person’s likeness, such as nonconsensual deepfakes, impersonation scams, and false or defamatory “hallucinations.” AI may also classify people based on their personal data in order to automate or inform consequential decisions involving employment, healthcare, legal determinations, or other significant outcomes. These decisions may threaten human agency by judging individuals based on actions they have not yet taken, and often reflect or reinforce historical—and potentially biased—data. And AI agents’ increasing autonomy and privileged access to a user’s data and systems, granted so they can complete tasks on a user’s behalf, raises the risk that agents will collect, retain, or share more personal data than a given task requires, undermining the principle of data minimization.
3. Why we need benchmarks for measuring privacy in AI
Benchmarks for measuring privacy in AI models could help bake privacy into the technical development of, and controls placed on, models. Rather than relying solely on legal instruments like DPIAs and contractual promises, which govern how a system is deployed rather than how a model behaves, a benchmark can provide engineers and product teams with a concrete score to aim for and compare across models over time. They also offer more flexibility compared to other forms of evaluation, since their ability to be built or updated relatively quickly helps them keep pace as AI capabilities evolve.
Being able to understand and evaluate AI systems in regards to privacy is particularly important given the increasing adoption of agentic systems, which operate more autonomously and typically have access to more of a user’s data. AI agents are useful precisely because of their privileged access to a user’s internal databases and systems, as well as their ability to interact with external tools on their behalf. At the same time, greater access raises other privacy and data protection considerations, such as over-collection and over-retention of personal data, susceptibility to threats like prompt injection, and the potential for disparate data to be combined in ways that enable sensitive inferences. Addressing these risks isn’t just about harm mitigation. Building more privacy-preserving agents may help build consumer trust and support broader adoption of these tools.
Given AI’s privacy risks, there is a critical need for standardized, industry-vetted benchmarks to measure and compare privacy and data protection outcomes across models. A number of benchmarks already probe specific privacy dimensions, but none has yet emerged as a common, agreed-upon standard that developers, deployers, and regulators can point to. Some existing privacy benchmarks include:
PrivacyLens: Extends privacy scenarios into agent trajectories to measure privacy leakage in agents’ actions.
CI-Bench: Evaluates whether AI assistants protect personal information during inference across roles, information types, and transmission principles.
AgentDAM: Tests data minimization and privacy leakage in autonomous web agents completing multi-step tasks.
SAPA-Bench: Evaluates privacy awareness in smartphone agents.
PrivacyBench: Tests conversational secret-keeping in personalized AI assistants.
Standardized privacy benchmarks would be valuable to a wide range of actors, including:
Developers: When “privacy” can be measured, it can become a routine, repeatable check built into the model development and release process, rather than a one-time policy review.
Deployers: When comparing vendors, selecting models to use, or conducting risk assessments, deployers can use a privacy benchmark to inform their decision-making.
Lawmakers and Regulators: When evaluating claims about model privacy or considering new regulations, standards, or oversight approaches, lawmakers and regulators can use privacy benchmarks as a technical evidence base and shared, measurable reference point, including concrete use cases and incentives for developers.
Independent researchers and third-party evaluators: When evaluating models and their potential impacts on privacy, independent or public interest researchers and third-party evaluators will have a standardized measure for comparison and a way to detect potential privacy violations.
4. Limitations of benchmarks
Benchmarks are just one method of evaluating AI models, and their results should be understood in light of their limitations. Generally, benchmarks can only capture what can be easily quantified, measured, and compared, and there are many behaviors and impacts that don’t lend themselves well to being benchmarked. In the context of privacy, for example, community or societal-level harms like surveillance may be difficult to capture in a benchmark, which typically measures how a model behaves in a given scenario rather than the aggregate systemic effects of its deployment. More specifically, there are a number of limitations that researchers, policymakers, regulators, and practitioners should keep in mind when analyzing frontier model performance on benchmarks:
Benchmark datasets may contain errors, and it can be hard to trace their lineage to discover this.
Benchmarks may not effectively measure what they claim to, either because of bad data or because what’s actually being measured is a poor proxy for the desired target of measurement.
Many benchmarks are not adequately diverse and representative, with many based on datasets that are disproportionately text-based and in English.
Benchmarks may favor those industry labs that have the resources to most readily compete in benchmarks.
Developers may “game” benchmarks by optimizing their models to the benchmark, akin to “teaching to the test,’ which can limit their usefulness or generalizability.
Benchmarks are bounded by their creators’ knowledge, limiting their ability to assess capabilities or failures that have not been anticipated.
Privacy’s complex and multi-faceted nature further complicates the measurement problem. Privacy harms can be difficult to quantify because they may be intangible, resulting in non-physical or non-financial setbacks such as anxiety or embarrassment; may lead to future downstream consequences that are not immediately visible, such as unauthorized data sharing with a third party; or may be the result of an aggregation of small or dispersed harms that are difficult to quantify on an individual level. While a benchmark cannot measure these harms directly, it can measure specific model behaviors that precede or contribute to them. The aforementioned existing privacy benchmarks for AI models touch on these aspects, such as the likelihood that a model shares sensitive personal information beyond the intended context or the likelihood that an agent leaks personal data while completing realistic tasks. Beyond these measurement challenges, building common, standardized benchmarks is further complicated by the diversity of privacy laws and norms across jurisdictions, each with its own definitions and obligations. A benchmark, while potentially useful for measuring compliance with key common elements across laws, is unlikely to be able to capture the complexity of global regulations.
Despite their limitations, benchmarks are still helpful as long as those shortcomings are recognized. They can also be created or altered relatively quickly in response to issues or feedback, making them flexible in comparison to other forms of evaluation. To ensure benchmarks are useful measures of AI model capabilities, researchers and developers should design them to test reliability, or performance over time and in varying conditions.
5. Emerging Efforts
Benchmarks are one of the key ways to evaluate frontier AI model capabilities, and are critical for pushing AI research forward. While benchmarks for testing AI models on the dimension of privacy exist, they are generally not standardized or vetted across different organizations. A reliable method of evaluating AI models for privacy would help developers, deployers, lawmakers and regulators, and independent researchers and third-party evaluators better understand and compare models’ performance on certain privacy metrics.
A new working group convened by MLCommons—an engineering consortium developing performance benchmarks for AI—is one example of an effort aiming to fill this gap. FPF is pleased to be participating in the Privacy and Confidentiality Working Group alongside leading AI companies and external experts. Part of MLCommons’ AI Risk & Reliability Program, the Working Group is developing standardized benchmarks to evaluate privacy risks and mitigation tools, with current efforts focused on measuring sensitive information disclosure and agentic data minimization. The working group also developed a privacy risk taxonomy to establish shared understandings of privacy risks, with the goal of providing frontier AI developers with reliable ways to measure how their models may result in privacy harms. Efforts like this also reflect a broader shift toward independent, third-party evaluation as a way to assess system risk, rather than relying solely on developer self-assessments. As this evaluation ecosystem matures, standardized privacy benchmarks could become a key part of how frontier AI systems are assessed consistently and credibly across the industry.
Our group of cross-industry, academic, and civil society experts aims to provide AI developers, deployers, regulators, and policymakers with the practical, standardized tools to objectively measure privacy risks at the frontier. Success means moving beyond high-level policy guidelines to equip the engineering community with concrete, measurable targets for designing privacy into the products that serve people worldwide. We are pleased to announce the publication of our Agent Privacy Risk Taxonomy, and look forward to publishing our benchmarks. We welcome industry and civil society collaboration to help shape these technical standards. – Kristie Chon Flynn and Vinh Nguyen, Co-Chairs of the MLCommons Privacy and Confidentiality Working Group
Defining “Agentic”: Why We Need a Shared Taxonomy for AI Agents
The authors would like to thank Alex Rosenberger and Justine Gluck for their feedback and contributions.
This summer, lawmakers in the United States released two of the first legislative proposals for regulating “AI agents”: the federal AI AGENT Act and California SB 1106. The proposals offer significantly different legal definitions of agentic AI, tailored to their different purposes. The AI AGENT Act, which would establish a framework for consumer-facing agents, defines agents in terms of their relationship with a user. California SB 1106, meanwhile, was aimed at building public infrastructure for cybersecurity, and defined agents in terms of their technical architecture and capabilities.
As FPF’s Center for AI has written previously, a rough consensus has emerged from AI literature about what defines whether AI is “agentic” from a technical perspective: in most cases, it involves a combination of advanced reasoning capabilities and access to consequential systems. Yet the term “agent” has different meanings to different audiences. For some, it refers to the powerful “agent swarms” seen in recent headlines about frontier labs, with all of the safety and alignment concerns they raise. For others, an “agent” describes a broad range of simple, automated systems, such as an LLM-powered web scraping tool. And for many others, “agentic-ness” is defined not by the technical design of the system at all, but instead by the level of human involvement (as with the levels of autonomy in vehicles) or by the degree to which the agent’s behavior is attributable upstream to a particular owner or user (as with “principal-agent” law). The term “agent” can also refer to a particular relationship or legal status, such as in the phrase “authorized agent” used in the California Consumer Privacy Act, which is applied well beyond the context of AI.
Almost all large enterprises, from banks to retailers, are figuring out how to deploy AI agents in both internal and customer-facing contexts to automate and streamline recurring, labor-intensive work. However, lacking common definitions and frameworks for thinking about what constitutes an agent can be a significant communication and governance challenge, especially when legal frameworks apply obligations based on a binary “in or out” scope. Governing agents effectively requires a shared language for agents and agentic behavior. This blog post explores this issue by examining technical literature, U.S. legislative efforts, and other major global frameworks.
What’s in a Name? Agentic AI Definitions in Technical Literature
In popular discourse, speakers use the terms “AI agents” or “agentic AI” to refer to many things, from a chatbot assistant that browses the Internet to a sophisticated system of LLMs and infrastructure that analyzes a user’s computer files and accesses external accounts on their behalf. In fact, the conflation of agents with other existing AI systems has led some to joke that agents are just “three (LLMs/bots/prompts) in a trench coat.” Jokes aside, the imprecise use of terminology obscures the fact that there are real, substantive differences that distinguish frontier “agents” from automated tools and LLMs more generally.
As FPF has written previously, much of the technical and governance literature characterizes AI agents as a significant evolution of existing AI, with definitions generally converging around their capabilities and their access. OpenAI, for example, characterizes agentic AI systems by “the ability to take actions which consistently contribute towards achieving goals over an extended period of time, without their behavior having been specified in advance.” The World Economic Forum, meanwhile, emphasizes agents’ autonomy and authority, the latter defined as “the granted permissions and access rights to perform specific actions within defined boundaries.” In other words, AI agents can break down tasks into multiple steps with some degree of autonomy, and carry out those tasks across a range of tools and applications. Anthropic’s Claude Cowork, for example, can plan and execute work based on user prompts, using local files and external systems like Google Drive, and without constant user approval.
These two prongs defining agentic AI—capabilities and access—matter for how agents are governed, because they are the factors that raise unique challenges compared to other kinds of AI, and which may require novel governance approaches. Agentic systems exist along a spectrum, with different tools exhibiting varying levels of autonomy, adaptability, action-taking, and data access depending on the use case, and a shared conception of agentic AI should take these features into account.
A simple way to conceptualize AI agents for the purpose of anticipating risks is by evaluating both their capabilities and the systems and tools to which they have access.
Capabilities: autonomy, adaptability, and action-taking
A distinguishing feature of agentic AI is the degree of latitude a system has in deciding how to accomplish a goal. A scripted bot that executes predetermined steps, even if it does so without human review, is not agentic because it does only what it was configured to do. On the other hand, a system that receives an open-ended objective and independently determines the path to achieve it—by breaking the goal into subtasks, sequencing and prioritizing those subtasks, and revising the plan based on intermediate results—is agentic because it is autonomous and responds to changing conditions. As legal scholar Noam Kolt puts it, LLMs are “copilots” and agents are “autopilots.”
Most systems deployed today sit somewhere between the scripted bot and the fully-autonomous agent. Many “agentic” tools can plan multi-step tasks, but seek user approval or confirmation before consequential steps, a safeguard meant to prevent serious mistakes. Others operate independently, but within a narrow domain like software bug detection, and cannot adapt outside of their specific context. Where an AI system falls on this spectrum matters for governance because autonomy and adaptability are what make agent behavior harder to predict and audit—oversight models built for deterministic automation do not necessarily transfer to non-deterministic systems that may behave in unpredictable ways.
Agentic AI is also distinguished by the kinds of actions it can take on behalf of a user. Today’s agents can click buttons, fill out forms, search and update databases, send messages, and execute code, with developers continually building additional tools and integrations. Agents are able to serve these functions by observing their environments, deciding what action to take, translating that decision into a call to a tool (such as navigating the web or operating on files), and then evaluating the results before repeating the cycle. When it comes to governing agentic systems, of course, not all actions carry the same weight—an agent that drafts and posts social media content based on rigid criteria may pose less of a threat than an agent that manages business systems, makes financial decisions that would typically require auditing, or makes other decisions with legal effects like hiring. A risk-based, proportionate approach to governance is tailored to the kinds of actions agentic systems can take, and how consequential these actions might end up being.
Access to systems and tools
Agents are enabled, or constrained, in their decision-making and action-taking by the systems and tools to which they have access. The ability to access systems external to the AI model itself is not exclusive to agents; retrieval-augmented generation (RAG), for example, is used to connect LLMs to additional datasets in order to generate more relevant, high-quality output. Where traditional RAG provides read-only access, however, more agentic systems generally have the ability to write or act on a user’s data or files. An LLM utilizing RAG could read a user’s inbox to understand context before replying to a query; an agent, on the other hand, could draft and send an email on their behalf. An LLM might search the Internet and flag sales for the user; an agent, operating through shared protocols and standards, might make purchases. This may entail users granting agents access to authenticated accounts, such as on banking or retail websites, which has led to litigation over whether platforms can block agents that scrape their sites without authorization. Governance frameworks can recognize the level of privileged access—both read and write—that agents have, as well as how the ability to combine data from across previously-siloed systems may grant them additional power.
Emerging U.S. Legislative Definitions and Global Regulatory Trends
The two recent U.S. agentic AI bills represent distinct—but not necessarily contradictory— approaches to conceptualizing agentic AI, tailored to the risks each bill addresses. The federal AI AGENT Act defines agents by their relationship with a user, applying to “custodial user agents” that are expressly authorized by, and loyal to, the user. The definition doesn’t focus on what an agent can do, but is scoped to cover software-based agents that interact with online platforms on the user’s behalf “in a transparent, documented, scope-limited, and revocable manner.” This aligns with the overall thrust of the discussion draft, which is generally a consumer protection and competition bill aimed at ensuring agents are loyal to users and can interoperate across online platforms under fair and reasonable terms.
Meanwhile, California SB 1106, which did not proceed but could be re-introduced in 2027, provided a much more granular definition of agents, reflecting both the capabilities and access prongs of agentic AI discussed in the literature:
(1) “Agentic artificial intelligence” or “agentic AI” means an artificial intelligence system that can pursue multistep or abstract goals by independently breaking them into tasks or delegating them, adjusting its own behavior based on results rather than waiting for user instruction or consent, and that can act in the world, including by executing code, using external tools, making purchases, accessing accounts that require authentication, or operating outside its own.
(2) “Agentic artificial intelligence” does not include a system that only responds to direct prompts and instructions from the user and lacks network egress or shell access.
This definition—which was amended from a previous, even-more-technical definition—distinguished agents from other forms of AI by emphasizing their autonomy, adaptability, and problem-solving. In contrast to the AI AGENT Act’s focus on consumer protection and competition, SB 1106 was more broadly about state agencies conducting risk analyses for AI and critical infrastructure, and cataloging high-risk AI uses. In each bill, agents are definitionally scoped to match the particular governance issues they seek to address.
In other emerging global frameworks, policymakers have also so far largely converged on a conception of agents emphasizing their technical capabilities and level of access (see table below). For example, Singapore’s InfoComm Media Development Authority (IMDA), in its Model AI Governance Framework for Agentic AI, recognizes a lack of definitional consensus but nonetheless posits that agents share common features such as independent planning, decision-making, and action-taking to achieve a user-defined goal. The IMDA further defines agentic AI systems as software systems containing one or more agents that often combine nondeterministic and deterministic components. Similarly, in a request for information about agentic AI security, the U.S.’ Center for AI Standards and Innovation (CAISI), housed within the National Institute of Standards and Technology (NIST), does not explicitly define AI agent systems but characterizes them as “capable of planning and taking autonomous actions that impact real-world systems or environments.”
Notable Global Legislative and Regulatory Definitions of “Agentic AI”
“Agentic artificial intelligence” or “agentic AI” means an artificial intelligence system that can pursue multistep or abstract goals by independently breaking them into tasks or delegating them, adjusting its own behavior based on results rather than waiting for user instruction or consent, and that can act in the world, including by executing code, using external tools, making purchases, accessing accounts that require authentication, or operating outside its own. “Agentic artificial intelligence” does not include a system that only responds to direct prompts and instructions from the user and lacks network egress or shell access.
Custodial user agent means a software-based agent that is expressly authorized by a user to interact with a large online platform provider on that user’s behalf in a transparent, documented, scope-limited, and revocable manner.
Request for Information Regarding Security Considerations for Artificial Intelligence Agents: AI agent systems are capable of planning and taking autonomous actions that impact real-world systems or environments. AI agent systems consist of at least one generative AI model and scaffolding software that equips the model with tools to take a range of discretionary actions.
Singapore InfoComm Media Development Authority
Model AI Governance Framework for Agentic AI: There is no consensus on what defines an AI agent, but there are certain common features – agents usually possess some degree of independent planning, decision-making, and action-taking (e.g. searching the web or creating files) over multiple steps to achieve a user-defined goal. Agentic AI systems are software systems consisting of one or multiple AI agents that may operate individually or collaboratively. Legal Responsibility for AI Agents (Discussion Paper): Agentic AI systems are software systems consisting of one or multiple AI agents that may operate individually or collaboratively. In practice, many agentic AI systems combine nondeterministic (e.g. LLM-based planning to determine what tool to call) and deterministic components (e.g. rules-based access controls on tools or partially scripted workflows).
‘AI agent’ means an AI system or a coordinated set of AI systems, that can perceive and act upon their environment, with a degree of autonomy, using tools as needed to achieve specific goals and adapt to changing inputs and contexts.
Agentic AI and protection of personal data: an equation with multiple unknowns for users: Agent-based AI refers to a set of computer programs based on generative AI models that are capable of making autonomous decisions, orchestrating complex actions, and interacting with third-party services, with or without human validation. The architecture of an agent-based AI system generally relies on the interaction between several components: (i) An “orchestrator” agent, at the core of which the generative AI model enables the user to interact with the system using natural language. … (ii) “Specialized” agents, coordinated by the orchestrator agent, which can perform complex tasks requiring specific skills (code generation, text processing, online payments, etc.). (iii) All of these agents can then be connected to external services such as applications, databases, or web search tools, which they can utilize to process requests. [Translated from French.]
AI systems with independent judgment and privileged access raise a recurring set of questions that regulatory and governance frameworks must answer—and that privacy, legal, and governance teams deploying agents must address. Certain sectors, like finance and banking, that are at the forefront of agent adoption are already dedicating significant resources to addressing these questions. The following governance issues, among others, are relevant across sectors and applications, though in practice may require different approaches depending on relevant risks.
Identity: When an agent acts, the parties on the other side of the interaction—such as platforms or merchants—need a way to know which agent is acting, who operates it, and which actor delegated it. Today there is no standard way to identify AI-driven traffic, and existing identity and access management tools don’t apply neatly to agent identities. Many early agent infrastructure efforts have centered around identity, including proposals for agent IDs, credentialing, and cryptographic signatures.
Accountability: Visibility into agent activity tends to break down when agents act across systems, over time, and through chains of delegation. Maintaining traceability requires dedicated logging and monitoring infrastructure, keeping records of what an agent observed, decided, and did, attributable to a responsible party.
Authorization and consent: Existing consent frameworks assume a human being is clicking through a static, fixed-purpose application. Agents challenge this assumption, requiring authorization that covers ongoing delegation whose specific actions cannot all be enumerated in advance.
Access and data minimization: Agents perform better when they have broader access to a user’s files and systems, which may put agent design in direct tension with data minimization. Establishing appropriately-scoped agent access will require novel approaches to setting least-privilege permissions, applying zero-trust principles, and allowing agents to convey intent, which may prove challenging given agents’ autonomous and non-deterministic nature.
Reliability and assurance: Even as agents’ capabilities improve, they’re not necessarily becoming more reliable. In other words, agents may increasingly be able to complete more types of tasks, and more quickly, but may not be able to do so accurately or consistently. Researchers also currently lack effective tools for measuring agents’ reliability.
It’s Just Math: Recent Legislative Trend Reignites Debate About the Bounds of Biometric Data
Special thanks to FPF’s Rafal Fryc (former U.S. Policy Intern), Tatiana Rice (Senior Director for U.S. Legislation), and Jim Siegl (Senior Fellow) for research support and feedback
A new exemption being proposed and considered in state legislatures across the country is resurfacing old debates around the contours of what constitutes biometric data. Biometric data has long been at the forefront of privacy debates in U.S. states. Illinois, Texas, and Washington all have standalone biometric privacy laws, and 20+ state comprehensive privacy laws also include heightened protections for biometric data as a category of sensitive data. Although this tide of legislation shows that there is growing consensus on the need to protect biometric data through privacy laws, defining “biometric data” remains a point of debate.
Beyond the threshold question of what constitutes “biometric data,” a newer and more subtle question is surfacing: whether converting biometric data into an irreversible mathematical representation—a security measure applied to otherwise in-scope data—should exempt it from biometric privacy protections altogether even if the data is still intended and able to be used for uniquely identifying an individual.
State comprehensive privacy laws typically define biometric data to mean data generated by automatic measurements of an individual’s biological characteristics that are used to identify a specific individual. A number of bills have included that definition with a novel exception for information that has been converted to a “mathematical representation” and which cannot be used to recreate the data generated by the measurement of an individual’s biological patterns or characteristics.
This new exception appears to be focused on biometric identification systems that use one-way mathematical processes to convert biometric data into a form that allegedly cannot be reversed to recreate an individual’s raw biometric data but nevertheless still allow for verification or identification. Although no state comprehensive privacy law has enacted this exemption so far, it is appearing in an increasing number of bills, including several that have come close to being enacted.
This blog post examines how this new legislative language differs from the existing biometric privacy landscape and some of the potential interpretive and policy questions it raises. Some key takeaways include:
Novelty: While biometric data privacy debates often center on the “identifiability” of the resultant data, the proposed ‘irreversible mathematical representation’ exemptions focus on (1) whether the in-scope biometric data went through a technical process to render it a “mathematical representation,” and (2) whether that resultant mathematical representation can be reverse engineered to create the data that was initially generated by automatic measurement of an individual’s biological patterns or characteristics.
Reversibility: The core component of the exemption—reversibility—is not defined and could arguably apply to differing degrees of biometric transformation processes with differing levels of security and assurance. While the spirit of the law may mean the exemption is less likely to apply to commonplace mathematical transformations (e.g., encryption of biometric templates), certain privacy enhancing technologies (PETs) such as cancellable biometrics could be intended to be in scope of the exemption.
Policy: If the policy justifications of biometric privacy laws are to mitigate the security risk posed to an individual by a breach of their biometric data and minimize the surveillance risk of biometric identification (i.e., risks to an individual’s autonomy, anonymity, or freedom of movement in public), a potential middle-ground could be to include the ‘irreversible mathematical representation’ exception only for specific, low-risk uses of biometric data that do not implicate broader surveillance concerns.
State Privacy Laws Typically Protect “Biometric Data” as “Sensitive Data”
State comprehensive privacy laws typically require controllers to (1) obtain opt-in consent to process sensitive data, and (2) conduct a data protection assessment prior to processing sensitive data. “Biometric data” is a common category of sensitive data under these laws. Connecticut’s definition of “biometric data” reflects the language common to the majority of these state laws:
“Biometric data” means data generated by automatic measurements of an individual’s biological characteristics, such as a fingerprint, a voiceprint, eye retinas, irises or other unique biological patterns or characteristics that are used to identify a specific individual.
“Biometric data” does not include (A) a digital or physical photograph, (B) an audio or video recording, or (C) any data generated from a digital or physical photograph, or an audio or video recording, unless such data is generated to identify a specific individual.
There is some variation between states’ definitions of biometric data. For example, states are split on whether biometric data should include data generated from a physical or digital photograph or a video or audio recording. There is also a growing divide between states that limit the definition to data that is usedorintended to be usedto identify a specific individual, on the one hand, and data that can be used for identification or that allows for identification, on the other hand. As detailed in a 2022 blog post, When Is a Biometric No Longer a Biometric?, these definitional differences raise threshold questions around whether privacy restrictions and protections should apply not just tools designed to identify or verify individuals’ identities but also emerging technologies that rely on data derived from humans, even if not used for identification, such as detection and characterization tools. In 2026, this carries even greater implications for emerging technologies like multimodal AI models, spatial intelligence models, accessibility features, face-blurring features, deepfake detection, and transcription tools.
Although divergent approaches to defining biometric “identification” are a significant policy issue, the proposed ‘irreversible mathematical representation’ exception appearing in a growing number of state privacy bills raises a distinct question, i.e., whether biometric data that is used or intended to be used to identify a specific individual should be exempt if certain technical and security processes occur as to render the data in a format such that it cannot be used to recreate the biologically-derived data.
The Proposed ‘Irreversible Mathematical Representation’ Exception
Multiple bills in recent years have proposed narrower definitions of biometric data that are similar to the definition from Connecticut above but which exclude information that has been captured and converted to a mathematical representation and that cannot be used to recreate data generated by automatic measurement of an individual’s biological characteristics. Looking at a comprehensive consumer privacy bill from the 2026 legislative session, for example, Mississippi HB 1051 included the following definition:
“Biometric data” means data generated by automatic measurement of an individual’s biological characteristics, such as fingerprints, voiceprints, eye retinas or irises, or other unique biological patterns or characteristics that are used to identify a specific individual. This term does not include:. . . (ii)Information captured and converted to a mathematical representation, including a numeric string or similar configuration, that cannot be used to recreate data generated by automatic measurement of an individual’s biological patterns or characteristics used to identify the specific individual.
Note that this is framed as an exception to information that would otherwise be “biometric data,” meaning it is information generated by measuring an individual’s biological characteristics and which is used or intended to be used for identification. If the information cannot be used for identifying an individual, then it is already out of the scope.
Versions of this ‘irreversible mathematical representation’ exception have appeared in numerous bills in recent years, including comprehensive privacy bills in Pennsylvania (HB 78, SB 112, & HB 1201) and Georgia (SB 111), as well as proposed amendments to Illinois’s BIPA (SB 3122, HB 2838, HB 3667, HB 5635, HB 2335, SB 1506, HB 2252, and HB 559).
The proposed exception is broader in some bills. Pennsylvania HB 78, for example, would include the ‘irreversible mathematical representation’ exception in its definition of “biometric data.” But that bill would also define “personal data” to not include “biometric data captured and converted to a mathematical representation,” without the additional criterion that such a representation cannot be used to recreate the original data. That is a much broader exception, and it highlights that the ‘irreversible mathematical representation’ exception, as it is commonly articulated, includes two distinct conditions:
The information must be converted to a “mathematical representation,” (i.e., there must be some mathematical process applied to the data generated).
One must be unable to recreate the underlying data from the mathematical representation (i.e., the process must be irreversible or one-way).
The condition that such information be converted to a “mathematical representation” means little if interpreted literally. All digital information is a mathematical representation—binary code. A digital scan of an analogue photograph, for example, is information that has been captured and converted to a mathematical representation. Under that interpretation, Pennsylvania HB 78 appears to be saying that biometric data is never personal data under the bill.
Setting aside the trivial interpretation that would cover all digital information, the “mathematical representation” language still likely captures all biometric data. To conduct biometric identification, there has to be an initial capture of a raw biometric input by a sensor (e.g., data collected by a scanner or microphone). That raw input data must then be processed, standardized, and have relevant features extracted to create a reference template (e.g., deriving a unique iris code from an iris scan) against which a future biometric input can be processed and compared. That process is itself a capture of information (raw input data) and conversion to a mathematical representation (the template or feature representation). The more stringent condition, therefore, is that the resultant mathematical representation “cannot” be used to “recreate” data generated by automatic measurement of an individual’s biological patterns or characteristics.
This ‘irreversible mathematical representation’ exception poses a number of questions about its scope, the technological processes to which it would apply, and the policy rationales that support it. Given its repeat appearances in proposed privacy legislation, it is worth exploring these questions, which reignite a debate as old as biometric privacy law itself: When is a biometric no longer a biometric?
Is a “Biometric” No Longer “Biometric” If It’s Irreversible?
The ‘irreversible mathematical representation’ exception raises a unique definitional question regarding the bounds of biometric data. Focusing only on the subset of technologies used for individual identification, the question raised by these bills is whether data should be exempted from heightened protections for biometric data if the information has been converted to a format such that it “cannot” be used to “recreate data generated by automatic measurement of an individual’s biological patterns or characteristics.”
What Constitutes Reversibility? Three Potential Applications
It is unclear how this exception would apply in practice. Namely, the ‘irreversible mathematical representation’ exception does not clarify what it means to “recreate” data generated by automatic measurement of an individual’s biological patterns or characteristics. This section will consider “reversibility” in three contexts: inverting a biometric template, encrypted biometric data, and one-way data distortions such as cancelable biometrics. Whether the exception would apply in each of those contexts helps clarify the purpose behind the exception.
1. Inverting a Biometric Template
At a high level, biometric identification typically involves an initial capture of raw biometric input data by a sensor (e.g., a scan of a fingerprint, palm, iris, or face). That data then undergoes pre-processing and feature extraction to generate a biometric template which is retained in a database for future use. In subsequent interactions, the individual’s biometric characteristic is again measured, processed, and then compared against the database of biometric templates to identify the individual in question.
Under a broad interpretation, one could argue that this process is within scope of the exception because it involves a capture of information about an individual’s biological characteristics and a process that subsequently converts that raw input data into a mathematical representation (the template). That is likely not the intended scope of the exception, for multiple reasons. As a matter of policy, that interpretation would broadly exempt almost all uses of biometric data for identification, causing the exception to swallow the rule. There is also a technical issue with that interpretation—irreversibility. If one has access to an unprotected biometric template, a raw mathematical map of biological features that has not undergone a non-invertible transformation, it is increasingly possible to reverse-engineer a synthetic sample of the individual’s biometric data through an inversion attack. For example, reverse-engineering iris images from iris codes was shown to be possible in 2012. Given the known risk of inversion, the ‘irreversible mathematical representation’ exception is unlikely to apply to unprotected biometric templates, although the actual risk of inversion may vary depending on the modality and other factors.
If the exception requires some additional process that is applied to reduce the risk of reversing a template to extract the original biometric data—or if the exception requires a mathematical transformation of the template itself, not merely the biological input data—then there are two likely other cases to consider: encryption or other forms of privacy enhancing technologies (PETs) (e.g, cancelable biometrics).
2. Encrypted Biometric Data
Encryption is the use of a mathematical process to convert data from an intelligible format to an unintelligible format for unauthorized persons. Merely encrypting biometric data is unlikely to be within the scope of the exception because it is a reversible process, provided the actor is in possession of the relevant key. However, the ‘irreversible mathematical representation’ exception does not specify from whose perspective it should be applied. A controller who encrypts its biometric data would likely argue that the exception should apply to them because a third party (without access to the key) would be unlikely to recreate the original data generated were they to access any encrypted templates or samples. Encrypted biometric templates are often considered “near-impossible to reverse engineer into usable data,” although “harvest now, decrypt later” attacks remain a risk. Whether this argument is persuasive would likely depend on the specific language used in the exception and the business’s security safeguards. It may matter, for example, if the exception says that the mathematical representation “cannot be used” to recreate the original data or if it “cannot reasonably be used” to do so. Given that some providers of biometric identification systems describe an encrypted biometric template as “a mathematical representation” that “cannot be reverse-engineered,” it is possible that companies would try to avail themselves of this exception merely by encrypting templates.
3. Cancelable Biometrics
If encryption is not a sufficient process to trigger this proposed exception, then that leaves more novel forms of biometric template protection, such as cancelable biometrics, biometric cryptosystems, or encrypted-domain biometrics. To focus on one example, cancelable biometrics describes the use of one-way data transformations to create a protected output. This differs from standard encryption in that there is no decryption step necessary to conduct the comparison—the comparison occurs in the transformed domain. Cancelable biometrics can utilize a data transformation either at the signal level (i.e., changes are made to the raw biometric data input prior to the creation of a template) or at the feature level (e.g., locality-sensitive hashing performed on feature vectors) to create a protected output. Biometrics vendors may use terms such as “biometric tokenization” to describe cancelable biometrics or other forms of biometric template protection.
This method adds additional layers of security because a template can be “canceled” if compromised and a new template can be created by adjusting the transformation applied. These outputs are also considered by many computationally infeasible to reverse, although such claims about irreversibility can be challenged. Data transformations such as cancelable biometrics are likely the use cases intended to be covered by the exception—they are forms of identification that use mathematical representations of data that are derived from measuring an individual’s biological characteristics but from which one (likely) cannot recreate the data originally measured.
Were it to be enacted in any jurisdiction, the full impact of this ‘irreversible mathematical representation’ exception would likely turn on a number of fact-specific questions, including nuanced technical and administrative details about an entity’s use of encryption or one-way data transformations. Setting those questions aside, it is sufficient to say at this stage that this exemption could affect a broad range of entities and technologies, given the prevalence of these kinds of technical safeguards and the exceptions’ lack of specificity.
Whether to Exempt this Kind of Data Depends onWhyBiometric Data is Considered Sensitive
To recap, state privacy laws commonly include “biometric data” as a category of sensitive data, and these laws typically scope “biometric data” to mean information generated by automatic measurement of an individual’s biological characteristics that are used to identify a specific individual. A growing number of proposed bills include this definition with an added exception, providing that “biometric data” would not include information captured and converted to a mathematical representation that cannot be used to recreate data generated by automatic measurement of an individual’s biological patterns or characteristics used to identify the specific individual. Applying the exception in practice may prove difficult, as it does not adequately define when a mathematical transformation sufficiently guards against the risk of recreating the originally captured information.
For the remainder of this blog post, assume that the ‘irreversible mathematical representation’ exception is scoped to cover at least one-way data transformations incorporated into the biometric identification process, such as cancelable biometrics. Evaluating whether this new exception furthers responsible data use requires unpacking the rationale for subjecting biometric data to heightened protections. There are two highly relevant policy justifications here: (1) the security risk posed to an individual by a breach of their biometric data; and (2) the surveillance risk of biometric identification (i.e., risks to an individual’s autonomy, anonymity, or freedom of movement in public).
1. The Security Rationale
One reason as to why biometric data is inherently sensitive is the long-term security risks posed by a data breach or inadvertent disclosure of biometric data. Biometrics are a double-edged sword when used for authentication and security purposes. Because of the unique nature of one’s biological characteristics, and the difficulty of changing those characteristics, they are uniquely suited to identifying an individual. Biometric verification also requires less effort from the individual as compared to remembering a password or maintaining alternative, layered forms of identification. Yet the permanence and uniqueness of biometrics make exposure extremely risky: it is easy to change a password, but it isn’t feasible to change your iris. This is stated in the legislative findings for Illinois’ BIPA, for example:
Biometrics are unlike other unique identifiers that are used to access finances or other sensitive information. For example, social security numbers, when compromised, can be changed. Biometrics, however, are biologically unique to the individual; therefore, once compromised, the individual has no recourse, is at heightened risk for identity theft, and is likely to withdraw from biometric-facilitated transactions.
It follows therefore that if a policymaker is concerned about the security risk posed to an individual by the risk of biometric data becoming permanently compromised, then it is good policy to incentivize companies to apply security measures and PETs in a manner that eliminates or greatly reduces the risk of a bad actor being able to access data from which they could create a synthetic sample of an individual’s biometrics.
If this is the policy rationale behind the ‘irreversible mathematical representation’ exception—incentivizing companies to adopt state of the art technical safeguards—then it is important to recognize that broadly carving out such data is not the only potential means of encouraging this behavior. Privacy laws regularly impose data security obligations that require reasonable practices to protect the confidentiality, integrity, and availability of personal data. Policymakers can consider other paths to encourage PETs adoption as potential alternatives to taking the resulting data outside of the scope of heightened protections for biometric data.
2. The Privacy/Surveillance Rationale
Another reason for treating biometric data as sensitive is the risk of surveillance. The aforementioned difficulty in changing one’s biological characteristics also makes biometric identification a powerful tool for persistent monitoring. Depending on how these systems are deployed, they can pose a significant risk to not just our privacy but our collective autonomy. If policymakers think that the processing of biometric data should be subject to heightened protections such as opt-in consent for that reason, then the ‘irreversible mathematical representation’ exception could exacerbate that risk because it removes the heightened notice and consent requirements for such uses even though the data can still be used to uniquely identify an individual. This risk speaks to a broader debate about how to adequately protect sensitive data: if “data is what data does,” and there is an agreed-upon privacy risk from biometric identification that warrants heightened obligations to collect and use that data, then merely transforming the data into a distinct format may be an insufficient protection if the underlying risky purpose for processing that data remains viable.
Some cases under existing biometric privacy laws illustrate this paramount focus on identifiability over the technical form of the data. For example, in denying a motion to dismiss in Rivera v. Google, the Northern District of Illinois held that, regardless of whether an entity converts “a person’s biometric identifier into some other piece of information, like a mathematical representation . . . the resulting information is still covered by the Privacy Act if that information can be used to identify the person.” In another BIPA case, Zellmer v. Meta, this line of reasoning arguably fared better for defendants. In Zellmer, the Ninth Circuit considered whether Facebook’s “face signatures”—created as part of the tag suggestions process and which converted face scans to “an abstract, numerical representation” that cannot be reverse engineered—are biometric identifiers. The Ninth Circuit found that, with respect to non-users of Facebook who do not have a corresponding face template to be matched, Facebook lacked the ability to identify such non-users and thus no biometric identifier was created. Again, this decision emphasizes identifiability. This debate is also ongoing outside of the US. For example, a 2025 decision by the Bavarian State Office for Privacy Supervision (“BayLDA”) rejected an argument that iris codes were not personal data because they could not be reverse engineered to reconstruct individual irises. Per the BayLDA decision, “[t]he reversibility of the algorithm under which an identifier was created” is not necessary under the GDPR’s definitions of “personal data” or “biometric data.” (¶ 325.) However, the finality of this decision is being appealed by defendant Worldcoin Foundation, which asserts that the Bavarian DPA’s holding runs contrary to the Court of Justice of the European Union’s more recent decision in EDPS v SRB (Case C-413/23 P).
None of these cases involved the specific language of the ‘irreversible mathematical exception’ that has been proposed in state privacy legislation. However, they do speak to the importance of an entity’s capability to identify an individual rather than the nature of the data itself.
An important nuance in this debate is that different uses of biometrics (both in terms of the modality and the use-case) raise different degrees of risk. Take, for example, a ticketless entry system for a sporting event. Given how people interface with these systems, a thumbprint scanner poses less of a surveillance risk than a facial recognition system because once someone’s face is enrolled in a facial recognition system, that tool can more easily be used for secondary, surreptitious purposes beyond the initial entry, such as security and public safety (including partnering with law enforcement) or profiling.
There are ways the ‘irreversible mathematical representation’ exception could be refined to still be responsive to individuals’ concerns over privacy and surveillance. For example, the exception could be paired with strong disclosure, purpose specification, and secondary use provisions. However, imposing such requirements would raise the question as to why this data was exempted from heightened consent requirements in the first place. Another potential middle-ground could be to include the exception but only for specific, low-risk uses of biometric data that do not implicate broader surveillance concerns, such as biometric locks which use 1:1 verification to grant access to a device or space and which are utilized for security purposes or limited 1:few identification systems.
Conclusion
Given the recurring appearance of this ‘irreversible mathematical representation’ exception in state privacy legislation, it is important to explore how this exception would apply and whether it can be scoped to support individuals’ privacy and security. Regardless of whether policymakers accept or reject this exception, they should clearly identify their priorities with respect to biometric identification and what specific harms they are responding to in regulating private entities’ collection and use of this data. This exception could enable positive uses of biometric technology that would otherwise be de facto prohibited under strict consent regimes. However, it would be important to ensure that the exception be paired with other measures that would prevent it from being overinclusive. Incentivizing responsible uses of biometric data, including adequate data security practices, does not need to come at the expense of vital protections for individuals’ privacy such as obtaining freely given, specific, informed, and unambiguous consent for processing biometric data used for identification.